
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

prompt-gallery dataset

A prompt-gallery dataset is a structured collection of user-submitted text prompts paired with the synthetic media, such as images or videos, generated by generative artificial intelligence models. These datasets typically aggregate real-world prompt-output pairs along with related metadata and generation parameters from public artificial intelligence platforms or community galleries. By capturing how people formulate inputs and how generative systems interpret them, prompt-gallery datasets serve as resources for analyzing user prompting behavior, benchmarking model quality, conducting prompt engineering, detecting generated content, and training or fine-tuning text-to-media models.

1 item
VidProM: A Million-scale Real Prompt-Gallery Dataset for Text-to-Video Diffusion Models

VidProM: A Million-scale Real Prompt-Gallery Dataset for Text-to-Video Diffusion Models

Wenhao Wang, Yi Yang

OrganizationsUniversity of Technology SydneyZhejiang University

Why you should read this

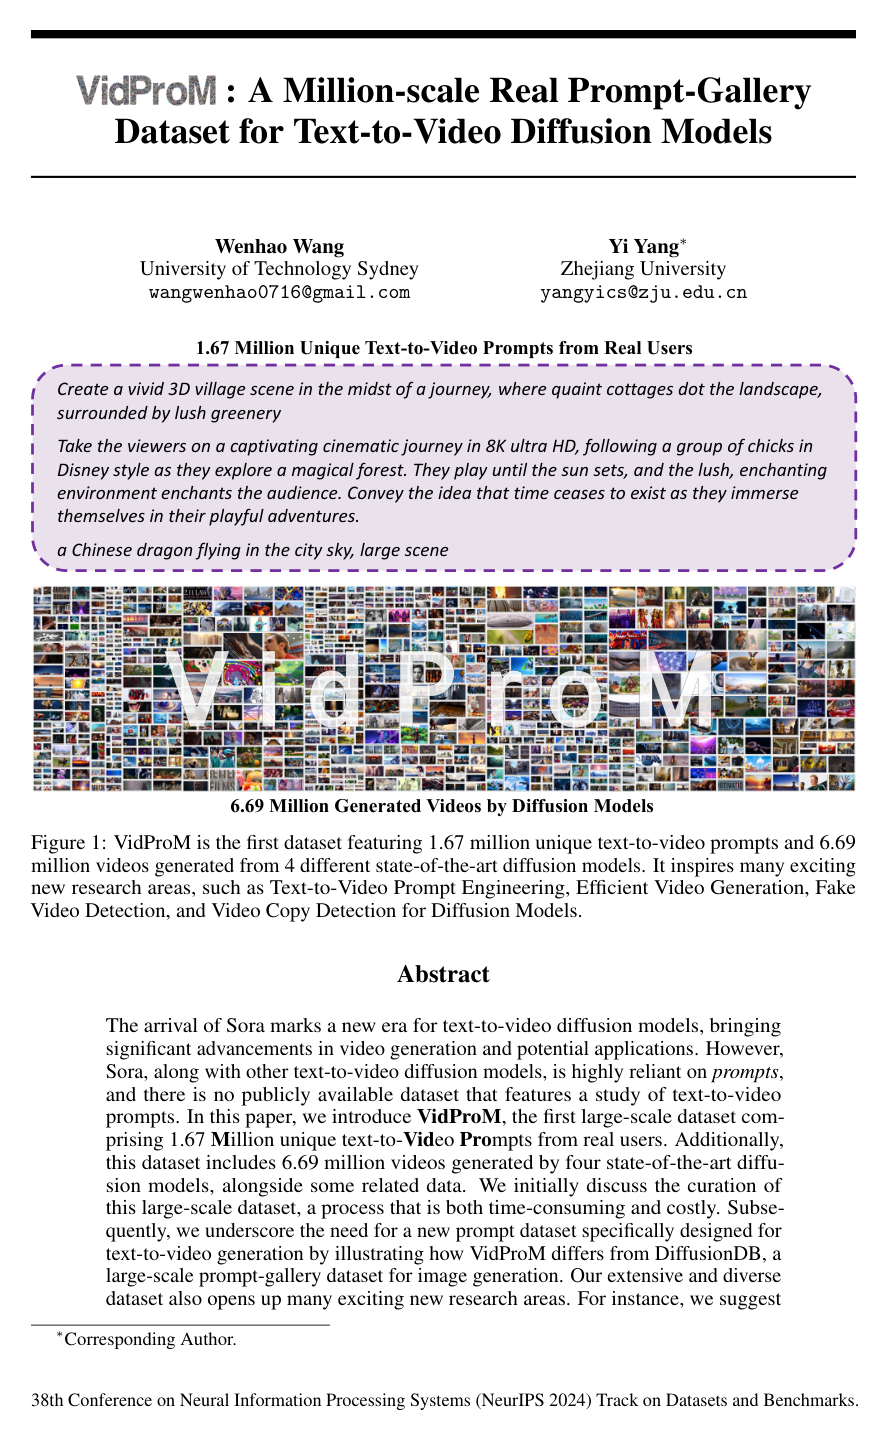
Introduces VidProM, the first large-scale prompt-gallery dataset containing 1.67 million real-user text-to-video prompts paired with 6.69 million synthesized videos from four diffusion models to advance research in video prompt engineering, efficient generation, and synthetic video detection.

The arrival of Sora marks a new era for text-to-video diffusion models, bringing significant advancements in video generation and potential applications. However, Sora, along with other text-to-video diffusion models, is highly reliant on prompts, and there is no publicly available dataset that features a study of text-to-video prompts. In this paper, we introduce VidProM, the first large-scale dataset comprising 1.67 Million unique text-to-Video Prompts from real users. Additionally, this dataset includes 6.69 million videos generated by four state-of-the-art diffusion models, alongside some related data. We initially discuss the curation of this large-scale dataset, a process that is both time-consuming and costly. Subsequently, we underscore the need for a new prompt dataset specifically designed for text-to-video generation by illustrating how VidProM differs from DiffusionDB, a large-scale prompt-gallery dataset for image generation. Our extensive and diverse dataset also opens up many exciting new research areas. For instance, we suggest

Added

2026-09-26