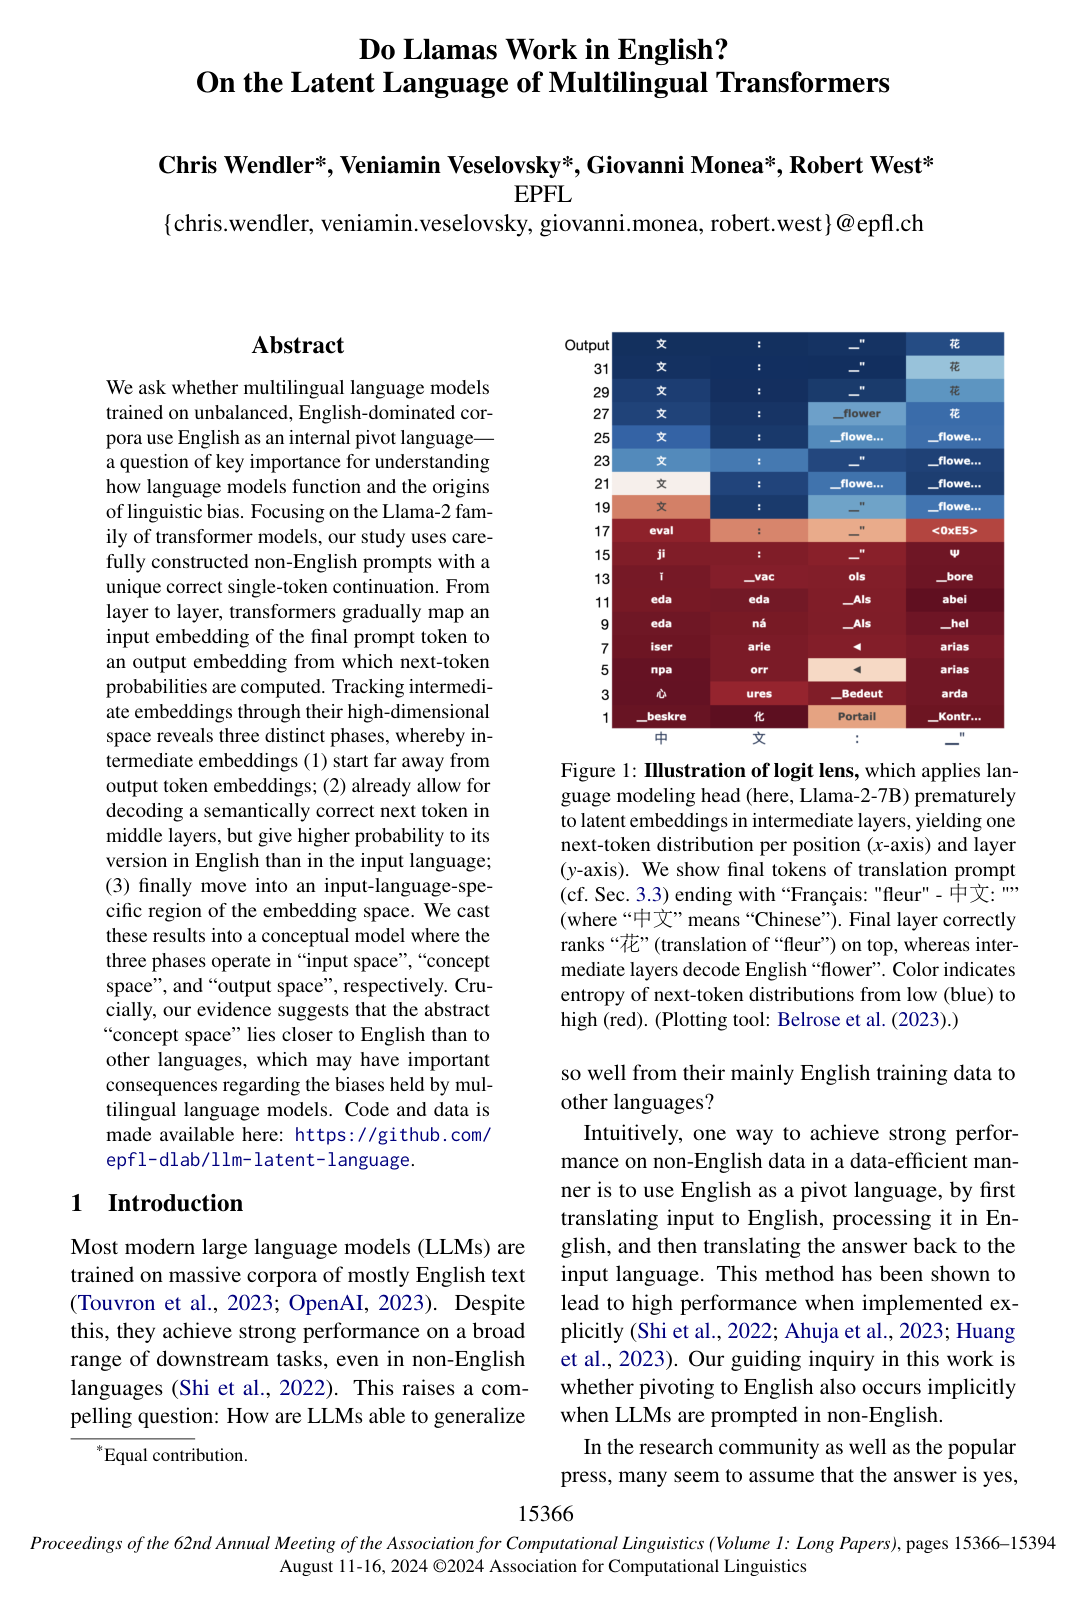
A next-token distribution is a probability distribution defined over a language model vocabulary that indicates the relative likelihood of every possible token occurring as the immediate continuation of a given sequence of text. In autoregressive neural networks, this distribution is generated by projecting the hidden representation of the final input position through an output embedding layer and applying a softmax function to convert the resulting raw scores into normalized probabilities. These distributions serve as the fundamental mechanism for step-by-step text generation, guiding decoding strategies such as greedy selection or sampling while reflecting the internal associations, certainty, and linguistic preferences of the model during computation.