
keyword
nearest neighbor queries
A nearest neighbor query is a database search operation that finds the point or set of points in a dataset closest to a specified query point according to a given distance metric. Rather than retrieving all objects within a fixed spatial boundary or predetermined radius, these queries determine the closest match or the k most similar matches based on relative proximity. They are widely applied in geographic information systems, similarity search, multimedia retrieval, and pattern recognition. To process nearest neighbor queries efficiently over large or high-dimensional datasets without scanning every record sequentially, systems typically utilize spatial and metric index structures alongside branch-and-bound traversal techniques to prune distant regions of the search space.
3 items
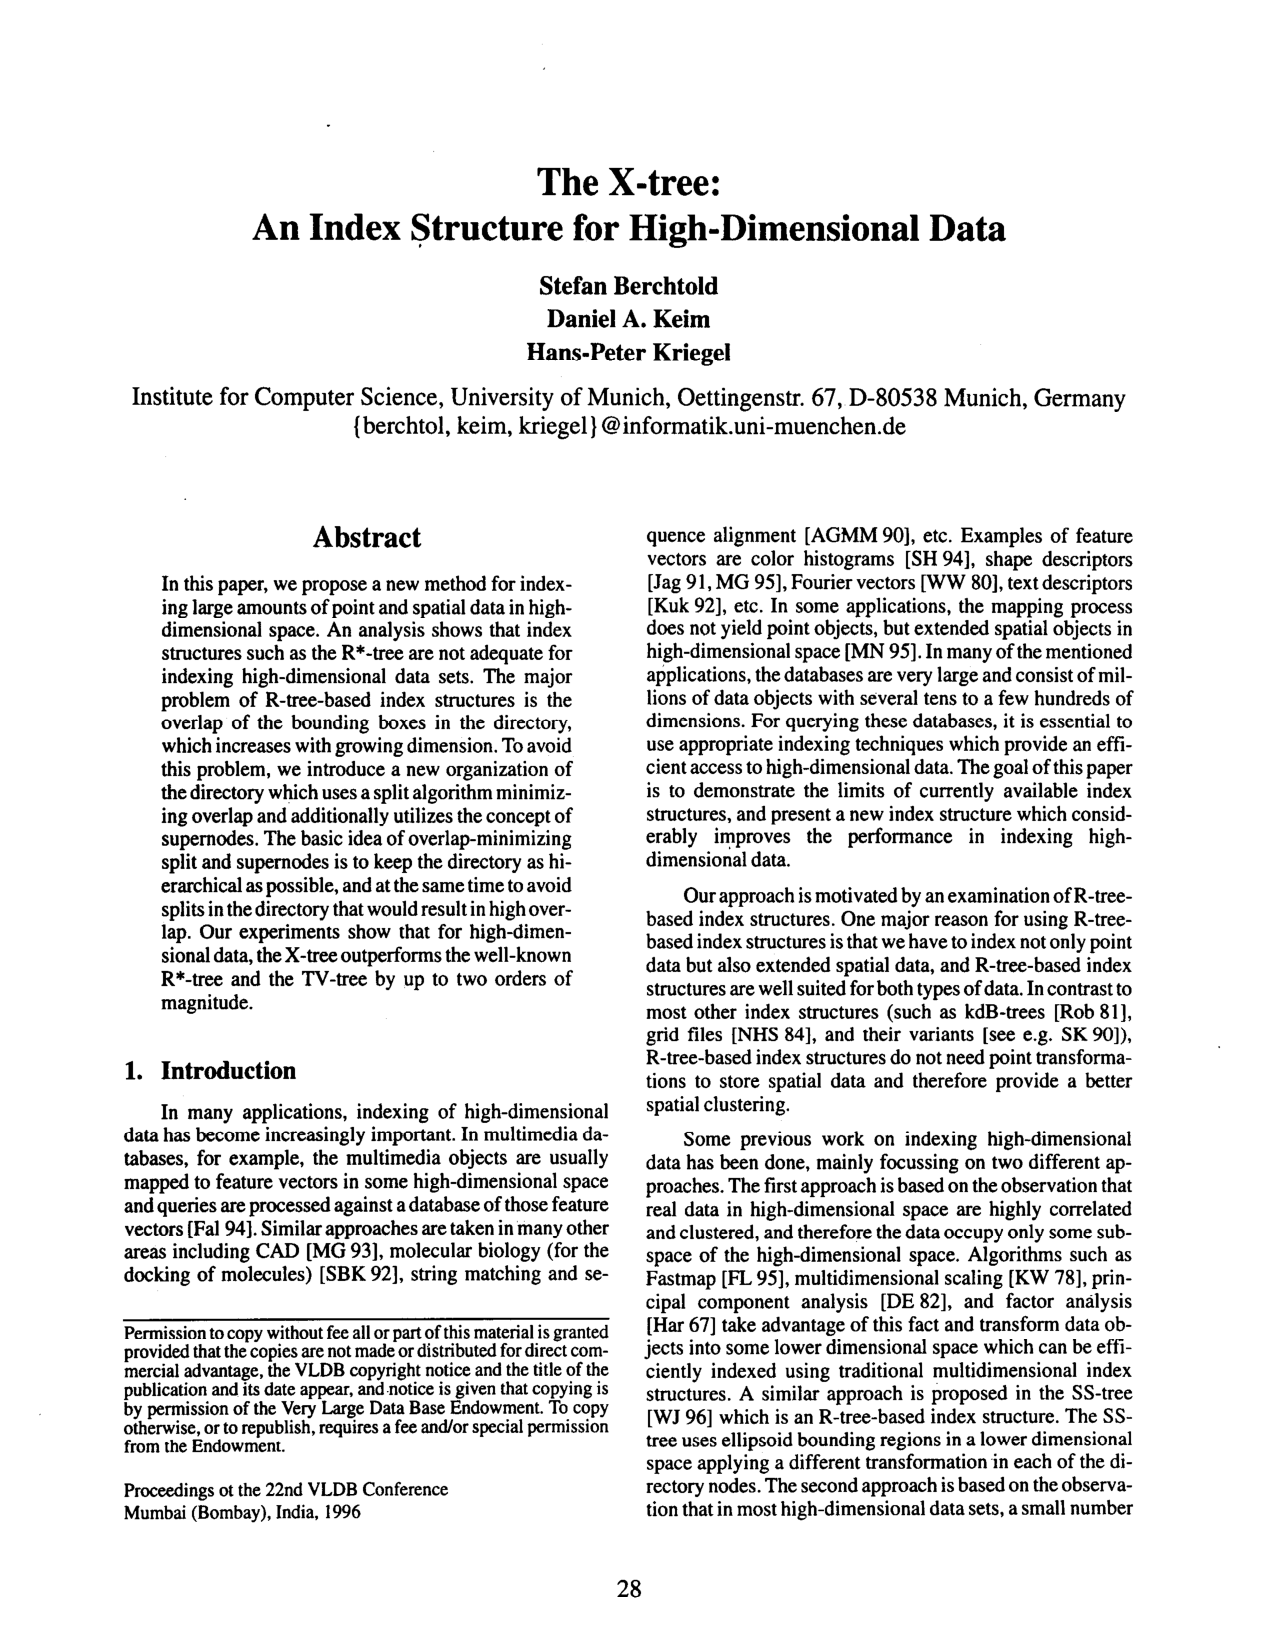
The X-tree : An Index Structure for High-Dimensional Data
S. Berchtold, D. Keim, H. Kriegel
Why you should read this
Introduces the X-tree, an efficient high-dimensional indexing structure that avoids bounding-box overlap by combining an overlap-minimizing split algorithm with variable-sized supernodes to outperform standard R*-trees and TV-trees by orders of magnitude.
In this paper, we propose a new method for indexing large amounts of point and spatial data in high-dimensional space. An analysis shows that index structures such as the R*-tree are not adequate for indexing high-dimensional data sets. The major problem of R-tree-based index structures is the overlap of the bounding boxes in the directory, which increases with growing dimension. To avoid this problem, we introduce a new organization of the directory which uses a split algorithm minimizing overlap and additionally utilizes the concept of supernodes. The basic idea of overlap-minimizing split and supernodes is to keep the directory as hierarchical as possible, and at the same time to avoid splits in the directory that would result in high overlap. Our experiments show that for high-dimensional data, the X-tree outperforms the well-known R*-tree and the TV-tree by up to two orders of magnitude.
Added
2026-09-24
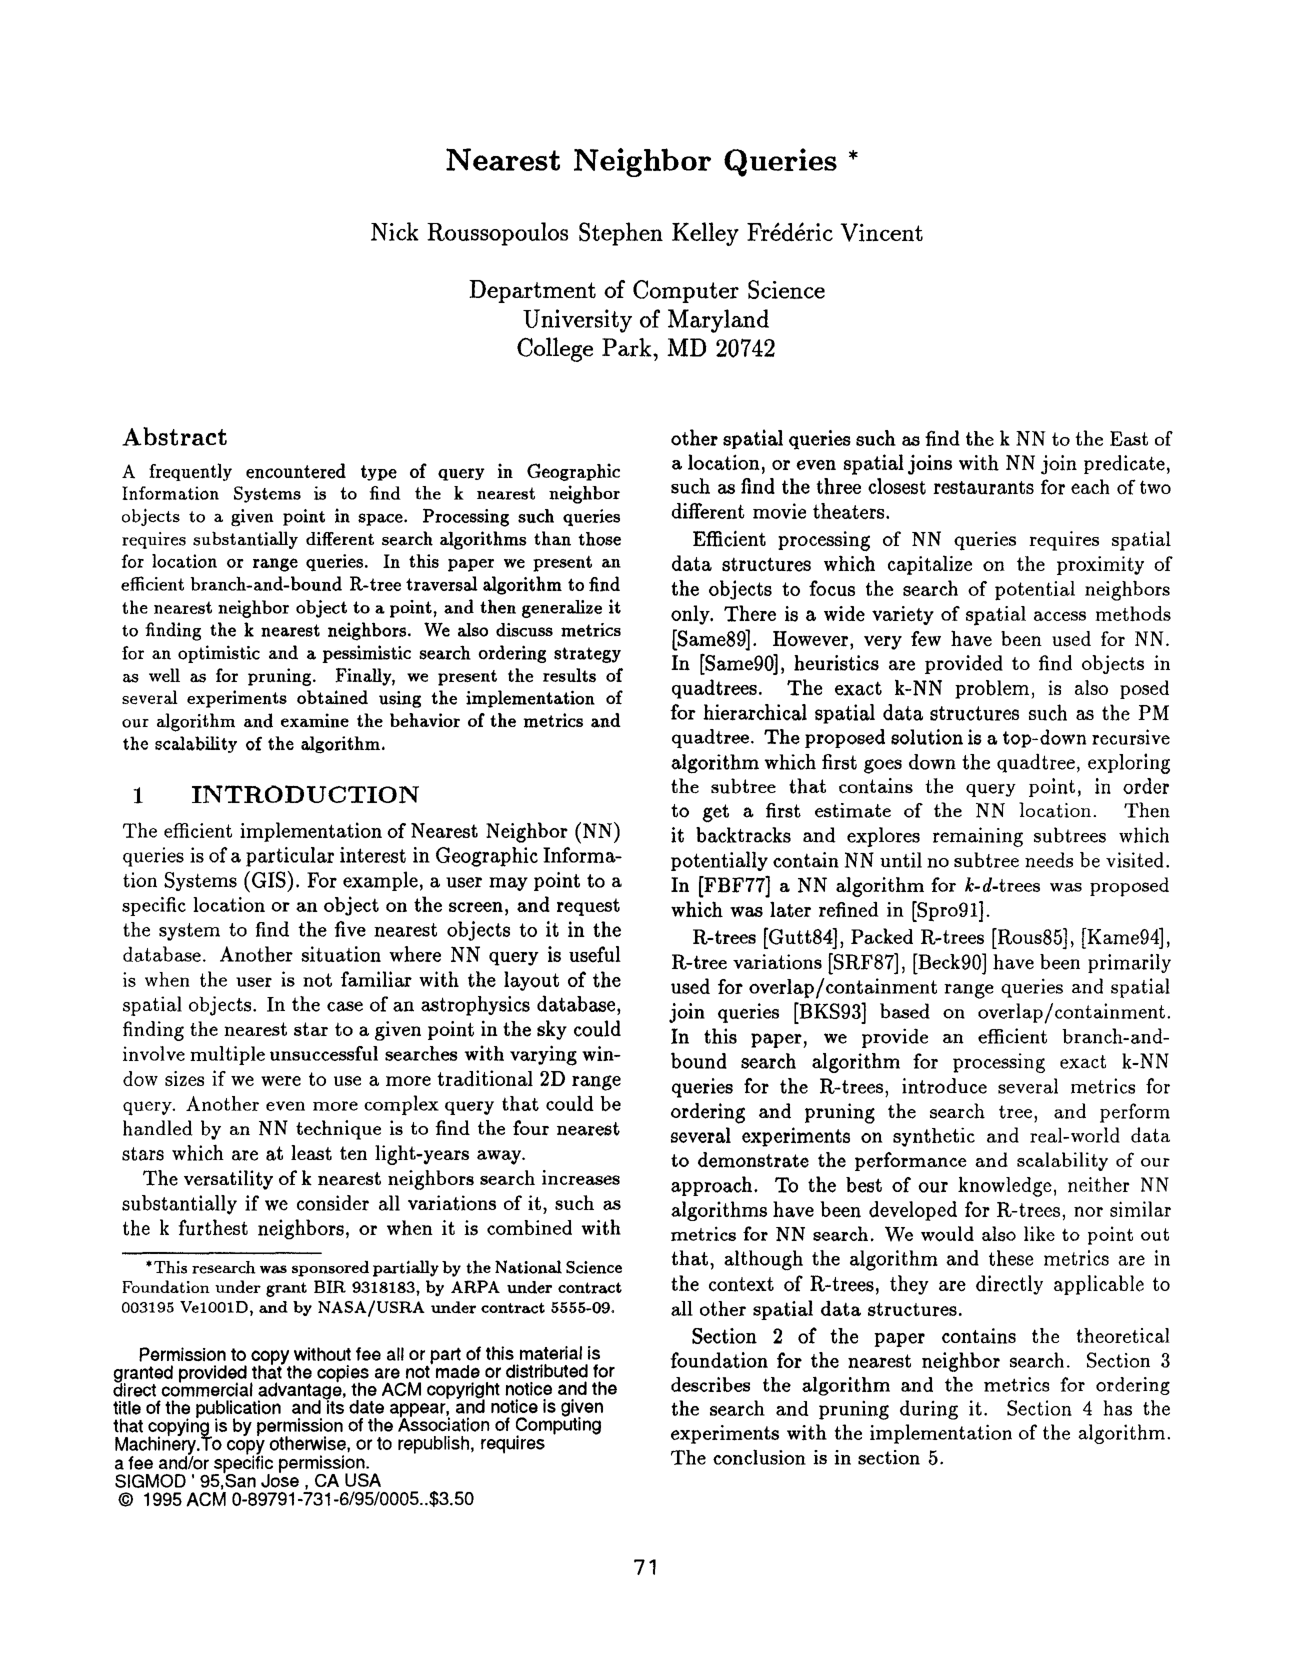
Nearest neighbor queries
N. Roussopoulos, Stephen Kelley, F. Vincent
Why you should read this
Proposes a foundational branch-and-bound R-tree search algorithm with distance metrics for effective search ordering and pruning to efficiently solve exact k-nearest neighbor queries in spatial databases.
A frequently encountered type of query in Geographic Information Systems is to find the k nearest neighbor objects to a given point in space. Processing such queries requires substantially different search algorithms than those for location or range queries. In this paper we present an efficient branch-and-bound R-tree traversal algorithm to find the nearest neighbor object to a point, and then generalize it to finding the k nearest neighbors. We also discuss metrics for an optimistic and a pessimistic search ordering strategy as well as for pruning. Finally, we present the results of several experiments obtained using the implementation of our algorithm and examine the behavior of the metrics and the scalability of the algorithm.
Added
2026-09-24
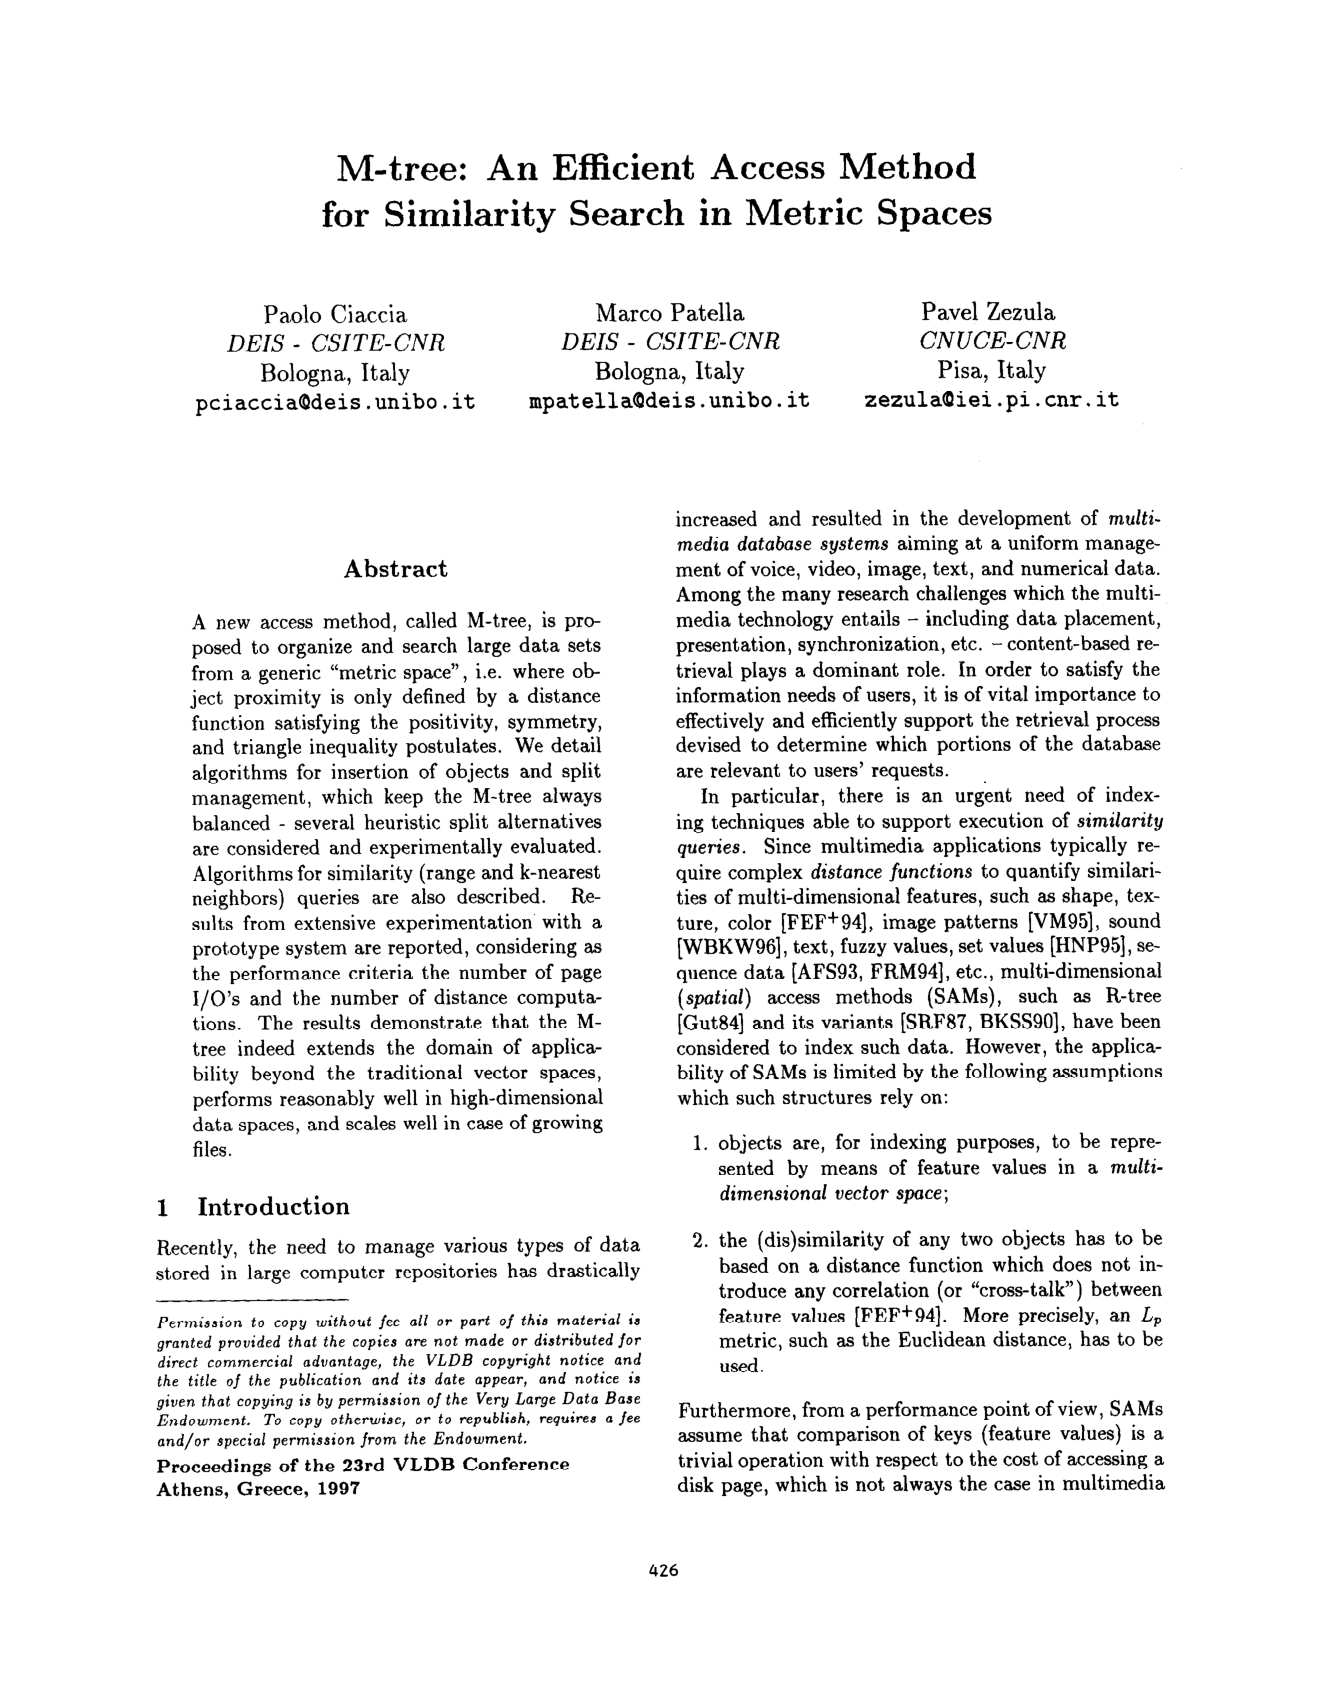
M-tree: An Efficient Access Method for Similarity Search in Metric Spaces
Paolo Ciaccia, Marco Patella, Pavel Zezula
Why you should read this
Presents the M-tree, a dynamic and balanced indexing structure designed for metric spaces that optimizes both disk I/O and distance computations during range and k-nearest neighbor similarity searches.
A new access method, called M-tree, is proposed to organize and search large data sets from a generic "metric space", i.e. where object proximity is only defined by a distance function satisfying the positivity, symmetry, and triangle inequality postulates. We detail algorithms for insertion of objects and split management, which keep the M-tree always balanced - several heuristic split alternatives are considered and experimentally evaluated. Algorithms for similarity (range and k-nearest neighbors) queries are also described. Results from extensive experimentation with a prototype system are reported, considering as the performance criteria the number of page I/O's and the number of distance computations. The results demonstrate that the M-tree indeed extends the domain of applicability beyond the traditional vector spaces, performs reasonably well in high-dimensional data spaces, and scales well in case of growing files.
Added
2026-09-18