
keyword
multimodal representation
A multimodal representation is a mathematical encoding or feature description that captures and integrates information from two or more distinct data modalities, such as text, images, audio, and video. In artificial intelligence and machine learning, it provides a structured way to combine heterogeneous sensory inputs, capturing both modality-specific patterns and complementary cross-modal relationships. These representations are typically learned as joint embeddings, where multiple modalities are fused into a single shared vector space, or as coordinated embeddings, where separate representations are mapped or aligned with one another. By translating diverse data streams into compatible computational formats, multimodal representations enable systems to perform complex cross-modal tasks such as visual question answering, multimedia retrieval, automated captioning, and holistic sensory understanding.
4 items
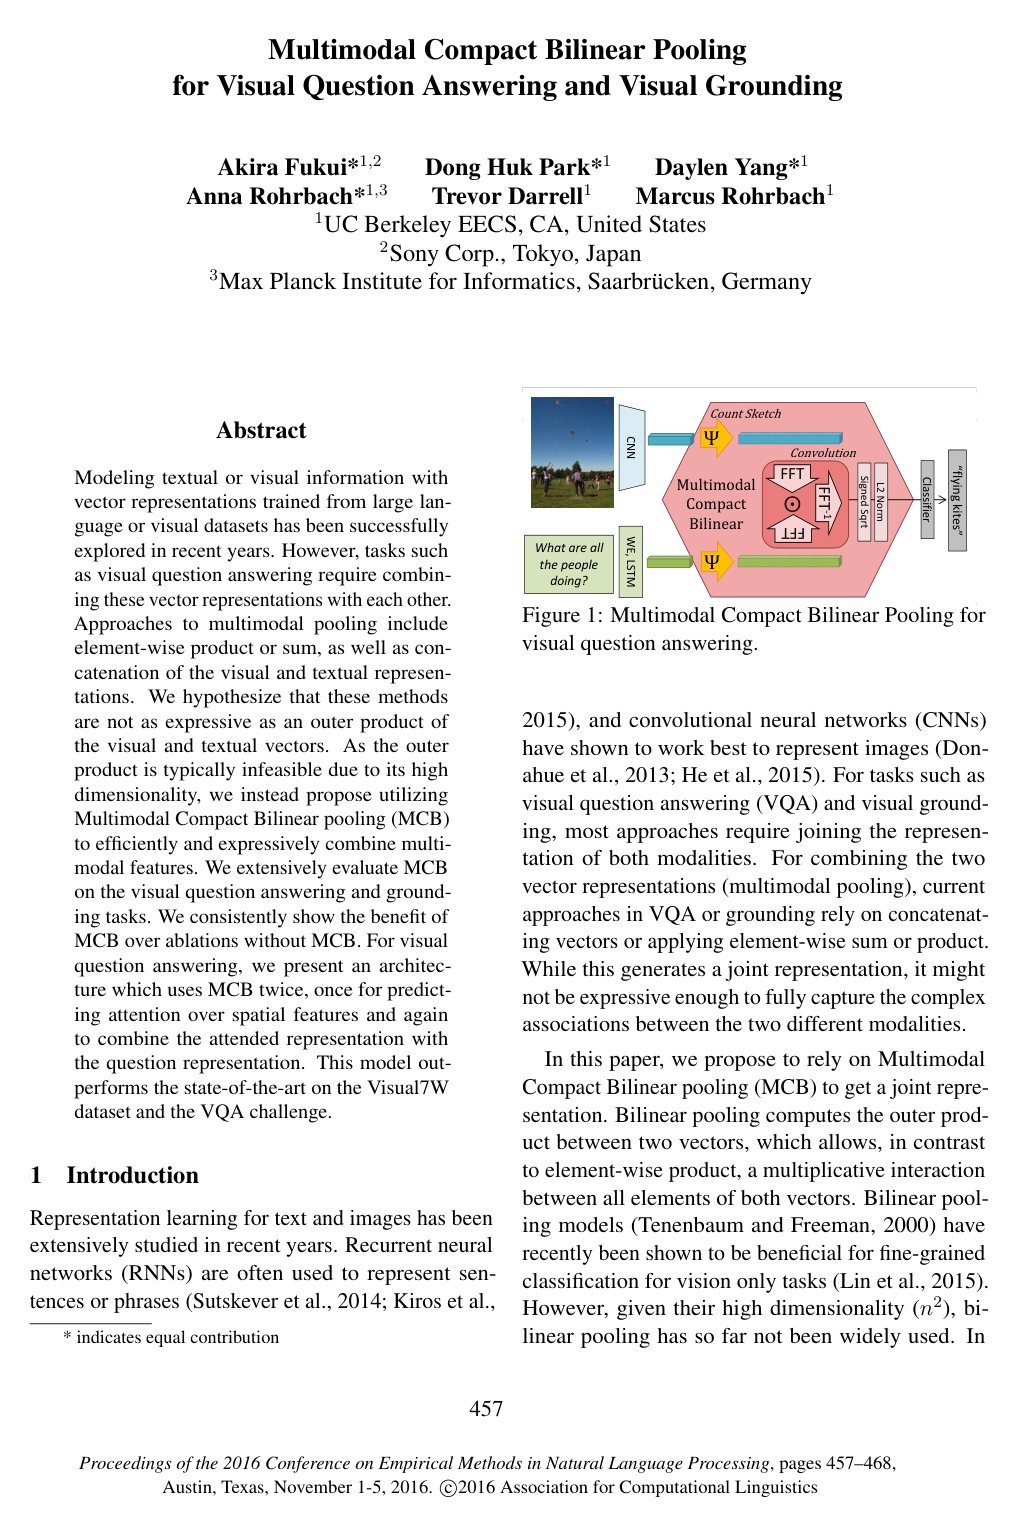
Multimodal Compact Bilinear Pooling for Visual Question Answering and Visual Grounding
Akira Fukui, Dong Huk Park, Daylen Yang, Anna Rohrbach, Trevor Darrell, Marcus Rohrbach
Why you should read this
Introduces Multimodal Compact Bilinear pooling to efficiently capture high-dimensional cross-modal interactions, achieving state-of-the-art performance in visual question answering and visual grounding.
Modeling textual or visual information with vector representations trained from large language or visual datasets has been successfully explored in recent years. However, tasks such as visual question answering require combining these vector representations with each other. Approaches to multimodal pooling include element-wise product or sum, as well as concatenation of the visual and textual representations. We hypothesize that these methods are not as expressive as an outer product of the visual and textual vectors. As the outer product is typically infeasible due to its high dimensionality, we instead propose utilizing Multimodal Compact Bilinear pooling (MCB) to efficiently and expressively combine multimodal features. We extensively evaluate MCB on the visual question answering and grounding tasks. We consistently show the benefit of MCB over ablations without MCB. For visual question answering, we present an architecture which uses MCB twice, once for predicting attention over spatial features and again to combine the attended representation with the question representation. This model outperforms the state-of-the-art on the Visual7W dataset and the VQA challenge.
Added
2026-09-25

Multimodal Deep Learning
Cem Akkus, Luyang Chu, Vladana Djakovic, Steffen Jauch-Walser, Philipp Koch, Giacomo Loss, Christopher Marquardt, Marco Moldovan, Nadja Sauter, Maximilian Schneider, Rickmer Schulte, Karol Urbanczyk, Jann Goschenhofer, Christian Heumann, Rasmus Hvingelby, Daniel Schalk, Matthias Aßenmacher
This book is the result of a seminar in which we reviewed multimodal approaches and attempted to create a solid overview of the field, starting with the current state-of-the-art approaches in the two subfields of Deep Learning individually. Further, modeling frameworks are discussed where one modality is transformed into the other, as well as models in which one modality is utilized to enhance representation learning for the other. To conclude the second part, architectures with a focus on handling both modalities simultaneously are introduced. Finally, we also cover other modalities as well as general-purpose multi-modal models, which are able to handle different tasks on different modalities within one unified architecture. One interesting application (Generative Art) eventually caps off this booklet.
Added
2026-09-12
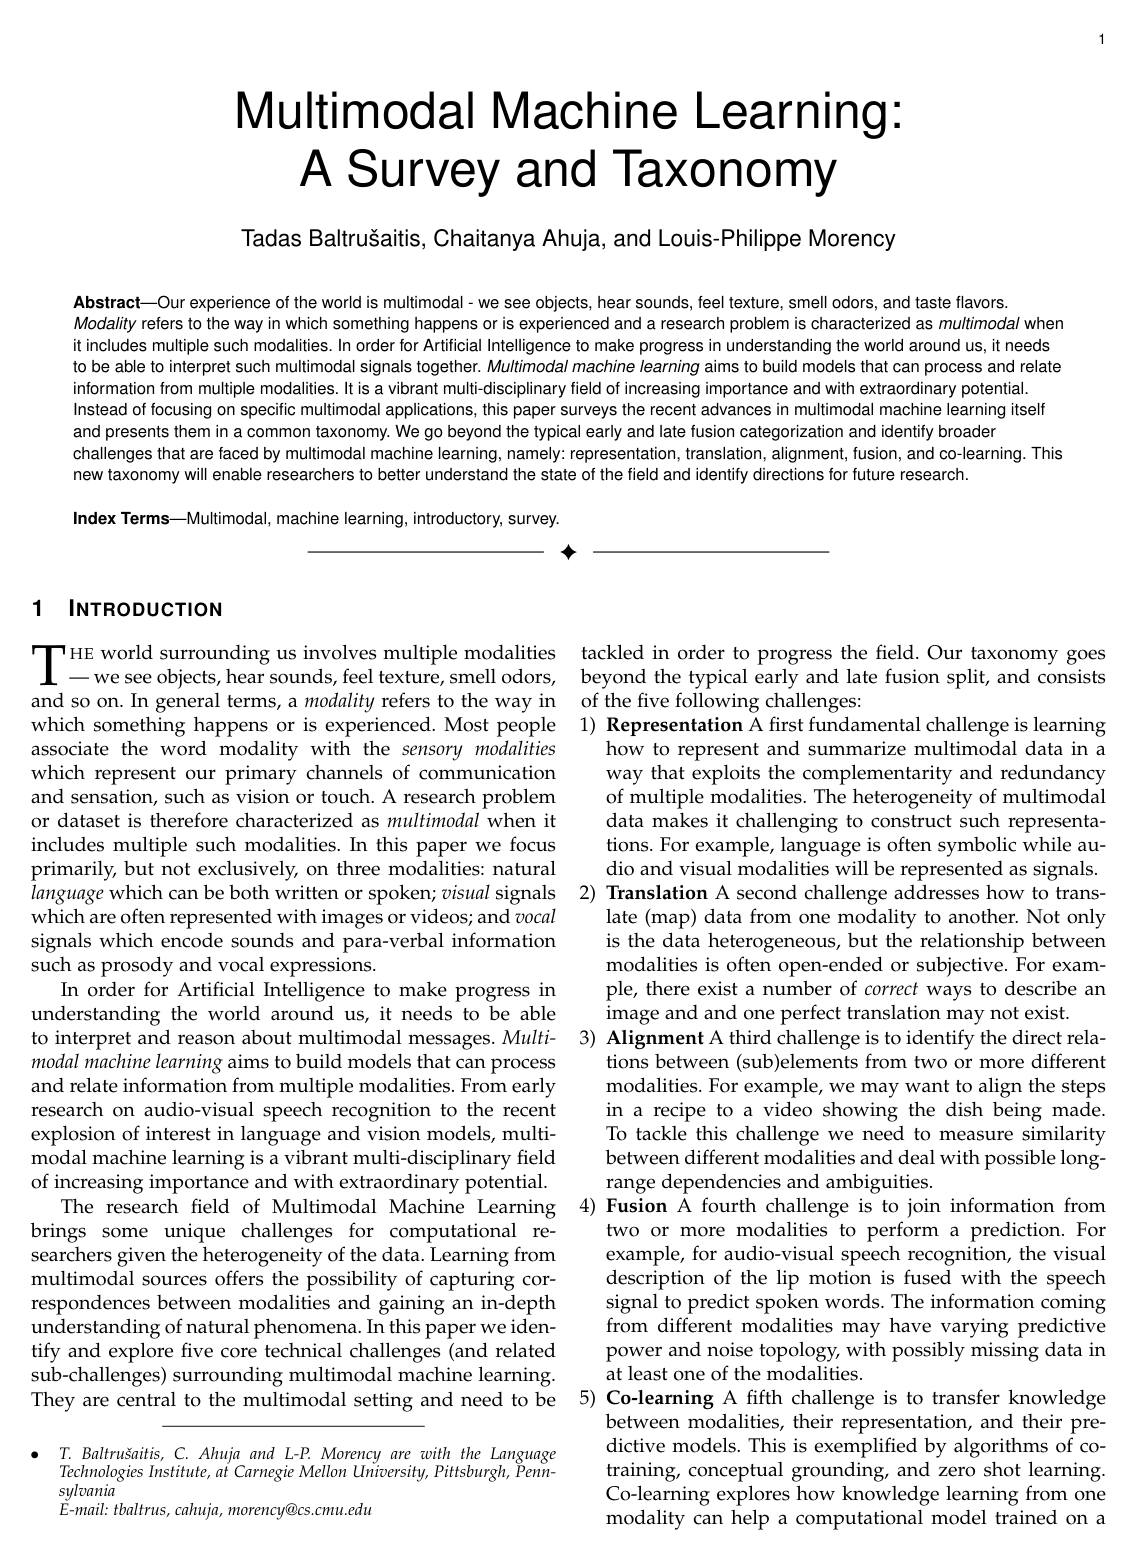
Multimodal Machine Learning: A Survey and Taxonomy
Tadas Baltrušaitis, Chaitanya Ahuja, Louis-Philippe Morency
Why you should read this
Establishes a comprehensive taxonomy for multimodal machine learning by structuring the field around five fundamental technical challenges: representation, translation, alignment, fusion, and co-learning.
Our experience of the world is multimodal - we see objects, hear sounds, feel texture, smell odors, and taste flavors. Modality refers to the way in which something happens or is experienced and a research problem is characterized as multimodal when it includes multiple such modalities. In order for Artificial Intelligence to make progress in understanding the world around us, it needs to be able to interpret such multimodal signals together. Multimodal machine learning aims to build models that can process and relate information from multiple modalities. It is a vibrant multi-disciplinary field of increasing importance and with extraordinary potential. Instead of focusing on specific multimodal applications, this paper surveys the recent advances in multimodal machine learning itself and presents them in a common taxonomy. We go beyond the typical early and late fusion categorization and identify broader challenges that are faced by multimodal machine learning, namely: representation, translation, alignment, fusion, and co-learning. This new taxonomy will enable researchers to better understand the state of the field and identify directions for future research.
Added
2026-09-10
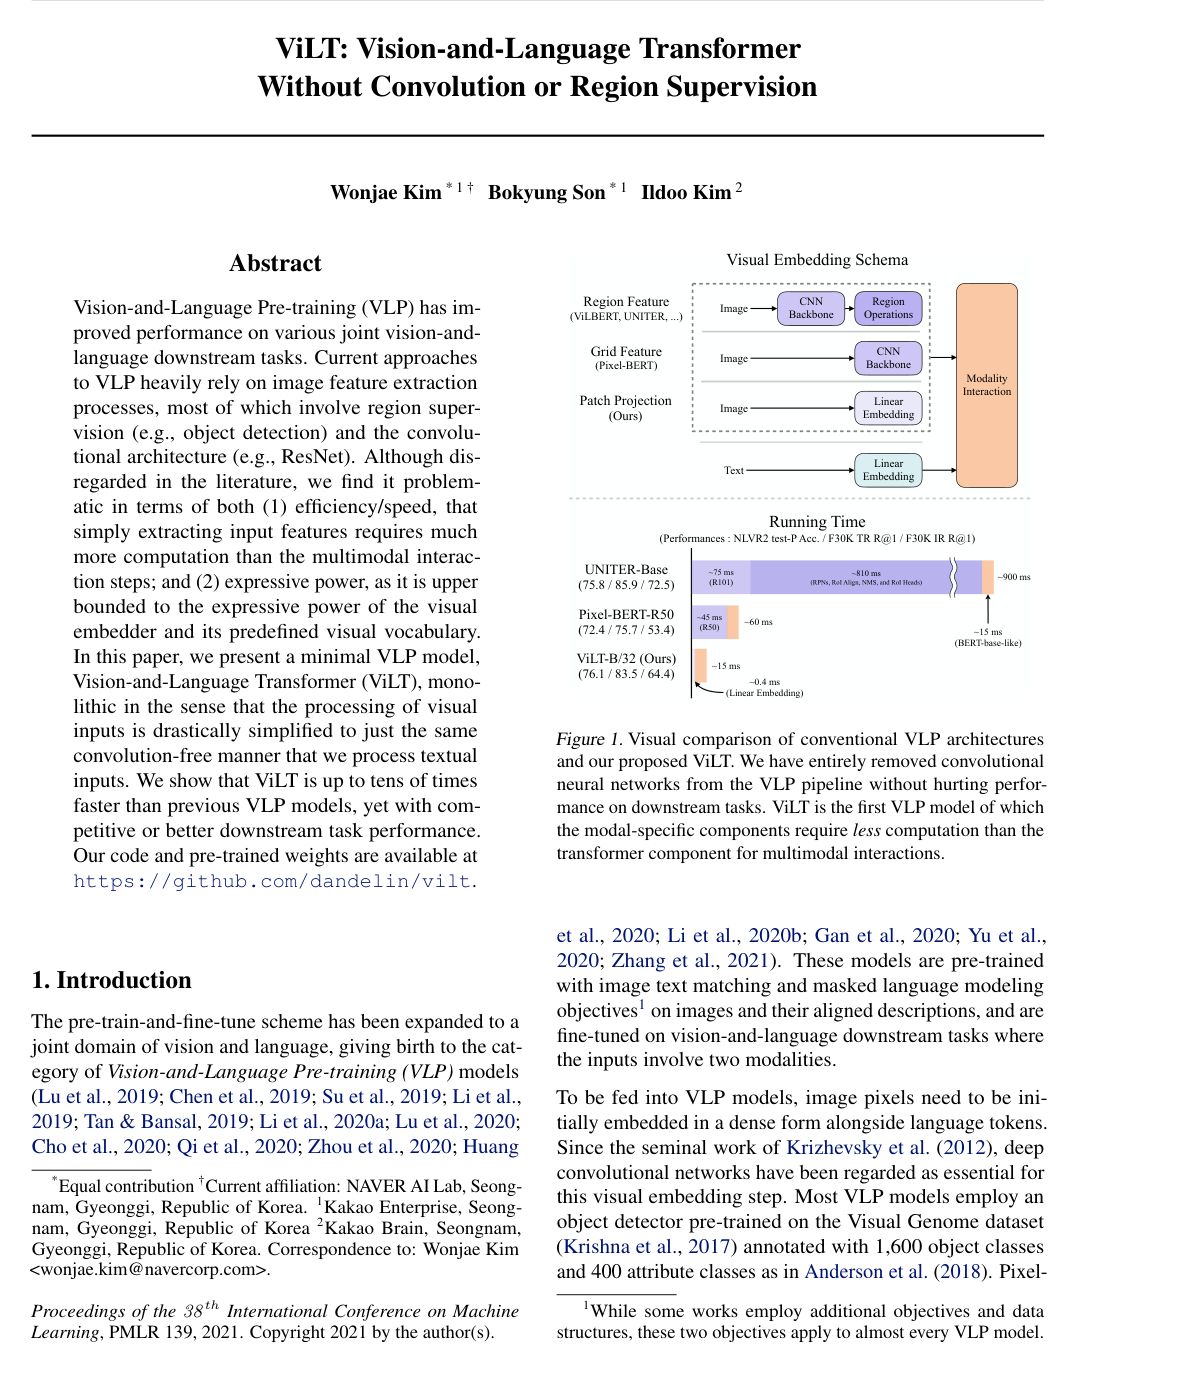
ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision
Wonjae Kim, Bokyung Son, Ildoo Kim
Why you should read this
Demonstrates that multimodal tasks can be solved by feeding raw image patches directly into a Transformer, eliminating the need for expensive object detectors.
Vision-and-Language Pre-training (VLP) has improved performance on various joint vision-and-language downstream tasks. Current approaches to VLP heavily rely on image feature extraction processes, most of which involve region supervision (e.g., object detection) and the convolutional architecture (e.g., ResNet). Although disregarded in the literature, we find it problematic in terms of both (1) efficiency/speed, that simply extracting input features requires much more computation than the multimodal interaction steps; and (2) expressive power, as it is upper bounded to the expressive power of the visual embedder and its predefined visual vocabulary. In this paper, we present a minimal VLP model, Vision-and-Language Transformer (ViLT), monolithic in the sense that the processing of visual inputs is drastically simplified to just the same convolution-free manner that we process textual inputs. We show that ViLT is up to tens of times faster than previous VLP models, yet with competitive or better downstream task performance. Our code and pre-trained weights are available at https://github.com/dandelin/vilt.
Added
2026-01-28