
keyword
multi-task benchmark
A multi-task benchmark is a standardized evaluation suite in machine learning comprising a diverse collection of distinct tasks used to measure an artificial intelligence model across multiple domains or reasoning skills. Unlike single-task benchmarks that assess specialized performance on an isolated objective, a multi-task benchmark evaluates a system for overall generalization, robustness, and the ability to share or transfer knowledge across different problem settings. Model performance is typically evaluated using both individual task metrics and an aggregate score across all included datasets, incentivizing the development of versatile, unified architectures and learning methods rather than narrow, task-specific solutions.
2 items
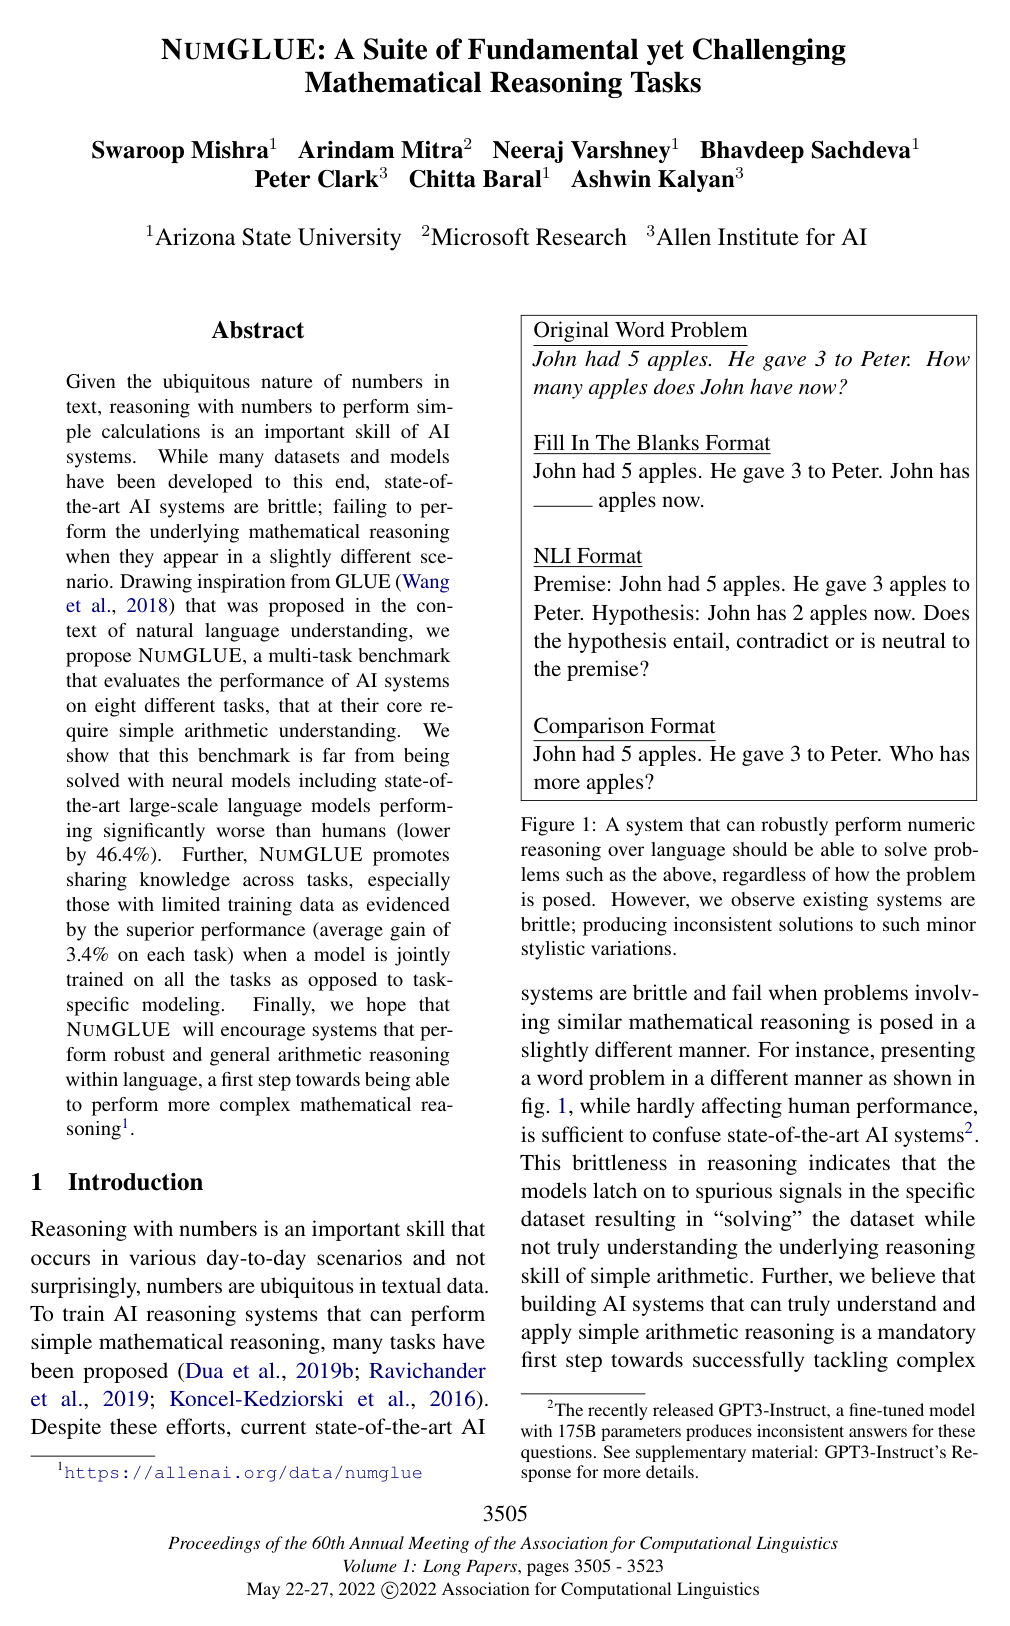
NumGLUE: A Suite of Fundamental yet Challenging Mathematical Reasoning Tasks
Swaroop Mishra, Arindam Mitra, Neeraj Varshney, Bhavdeep Singh Sachdeva, Peter Clark, Chitta Baral, Ashwin Kalyan
Why you should read this
Presents NUMGLUE, an eight-task benchmark spanning roughly 100,000 problems that exposes large language models' severe arithmetic brittleness compared to human reasoning while showing that joint multi-task training significantly boosts numerical performance across diverse question formats.
Given the ubiquitous nature of numbers in text, reasoning with numbers to perform simple calculations is an important skill of AI systems. While many datasets and models have been developed to this end, state-of-the-art AI systems are brittle; failing to perform the underlying mathematical reasoning when they appear in a slightly different scenario. Drawing inspiration from GLUE (Wang et al., 2018) that was proposed in the context of natural language understanding, we propose NUMGLUE, a multi-task benchmark that evaluates the performance of AI systems on eight different tasks, that at their core require simple arithmetic understanding. We show that this benchmark is far from being solved with neural models including state-of-the-art large-scale language models performing significantly worse than humans (lower by 46.4%). Further, NUMGLUE promotes sharing knowledge across tasks, especially those with limited training data as evidenced by the superior performance (average gain of 3.4% on each task) when a model is jointly trained on all the tasks as opposed to task-specific modeling. Finally, we hope that NUMGLUE will encourage systems that perform robust and general arithmetic reasoning within language, a first step towards being able to perform more complex mathematical reasoning.
Added
2026-09-26
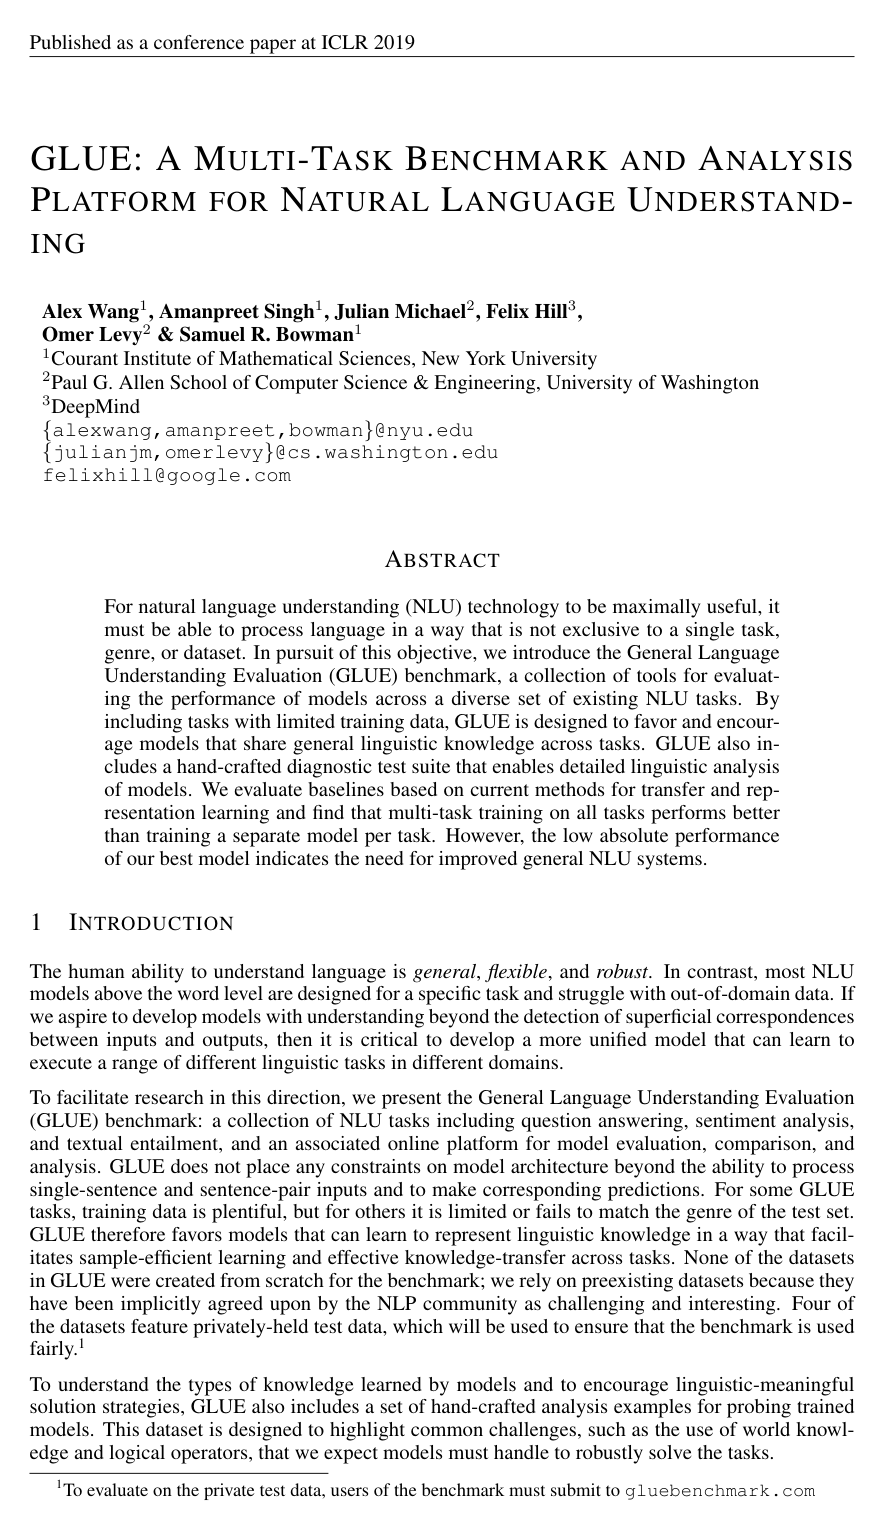
GLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding
Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, Samuel R. Bowman
Why you should read this
Establishes the General Language Understanding Evaluation (GLUE) benchmark to provide a standardized multi-task platform and diagnostic suite for evaluating whether NLP models can learn general, transferable linguistic representations across diverse language understanding tasks.
For natural language understanding (NLU) technology to be maximally useful, both practically and as a scientific object of study, it must be general: it must be able to process language in a way that is not exclusively tailored to any one specific task or dataset. In pursuit of this objective, we introduce the General Language Understanding Evaluation benchmark (GLUE), a tool for evaluating and analyzing the performance of models across a diverse range of existing NLU tasks. GLUE is model-agnostic, but it incentivizes sharing knowledge across tasks because certain tasks have very limited training data. We further provide a hand-crafted diagnostic test suite that enables detailed linguistic analysis of NLU models. We evaluate baselines based on current methods for multi-task and transfer learning and find that they do not immediately give substantial improvements over the aggregate performance of training a separate model per task, indicating room for improvement in developing general and robust NLU systems.
Added
2026-09-09
