Built independently by an author, for readers. Read the story and support ChapterPal

keyword

MixFormer

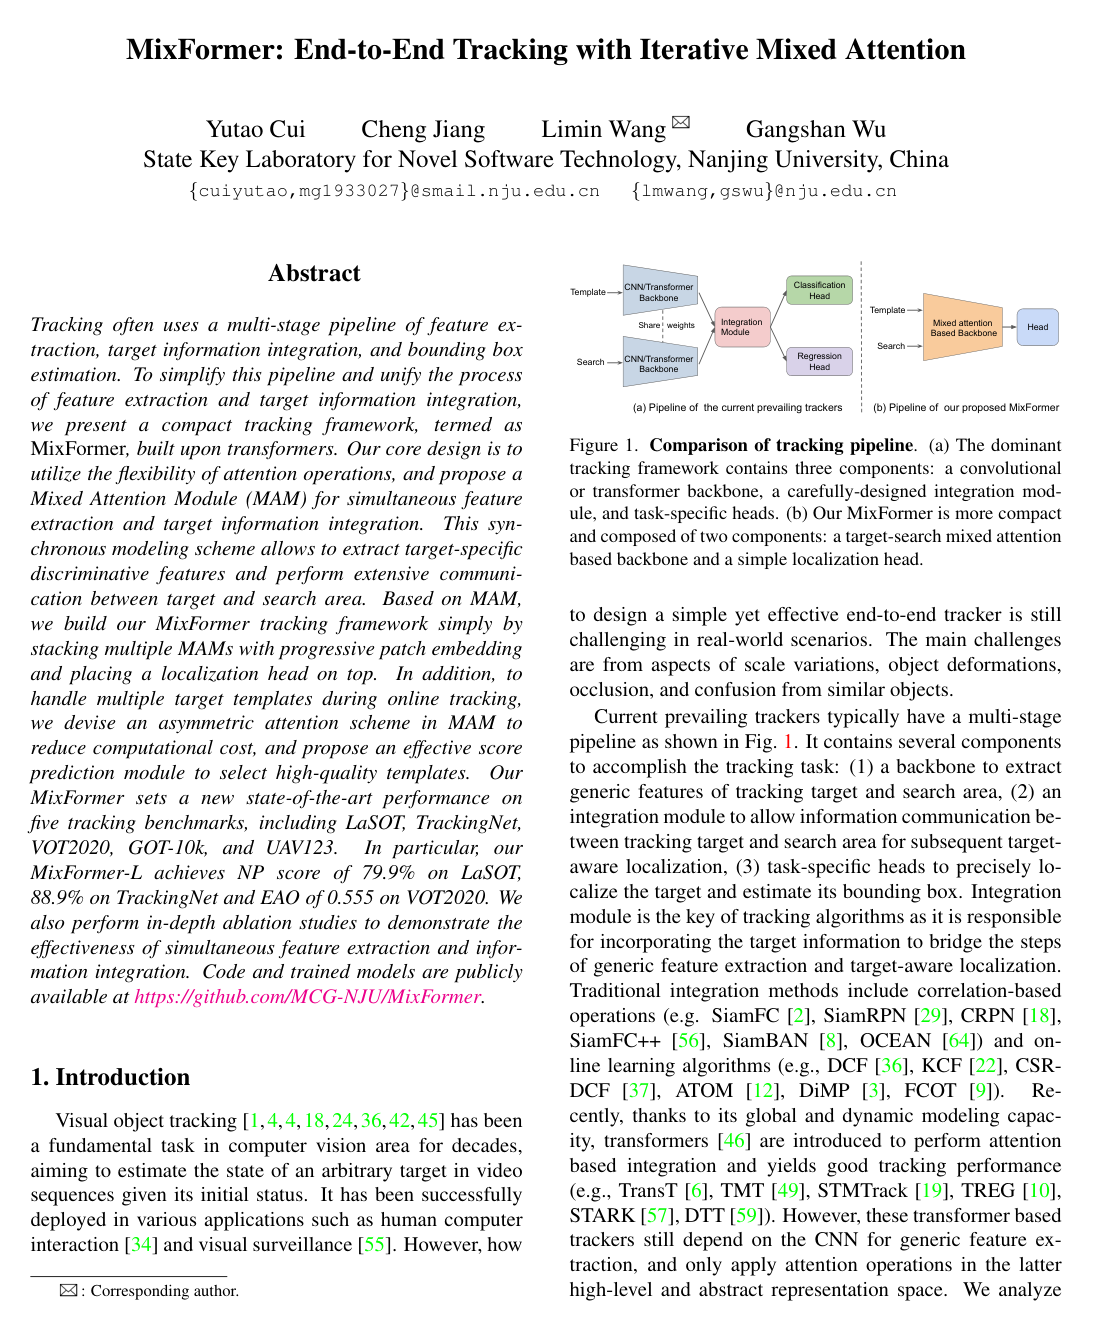
MixFormer is an end-to-end vision transformer architecture designed for visual object tracking in computer vision. Unlike traditional tracking frameworks that separate feature extraction and target-search relation modeling into distinct multi-stage processes, MixFormer unifies these operations using iterative mixed attention modules. These modules simultaneously perform self-attention within individual image regions and cross-attention between target templates and the search area, enabling the model to extract target-specific features while facilitating continuous information exchange across frames. Constructed by stacking these mixed attention layers with patch embeddings and a localization head, the architecture simplifies the tracking pipeline and efficiently supports dynamic template updates to accurately track moving objects in video sequences.

1 item

MixFormer: End-to-End Tracking with Iterative Mixed Attention

MixFormer: End-to-End Tracking with Iterative Mixed Attention

Yutao Cui, Cheng Jiang, Limin Wang, Gangshan Wu

OrganizationsNanjing University

Why you should read this

Proposes MixFormer, an end-to-end transformer tracker that unifies feature extraction and target information integration through iterative mixed attention to set new state-of-the-art performance across five major visual tracking benchmarks.

Tracking often uses a multi-stage pipeline of feature extraction, target information integration, and bounding box estimation. To simplify this pipeline and unify the process of feature extraction and target information integration, we present a compact tracking framework, termed as MixFormer, built upon transformers. Our core design is to utilize the flexibility of attention operations, and propose a Mixed Attention Module (MAM) for simultaneous feature extraction and target information integration. This synchronous modeling scheme allows to extract target-specific discriminative features and perform extensive communication between target and search area. Based on MAM, we build our MixFormer tracking framework simply by stacking multiple MAMs with progressive patch embedding and placing a localization head on top. In addition, to handle multiple target templates during online tracking, we devise an asymmetric attention scheme in MAM to reduce computational cost, and propose an effective score prediction module to select high-quality templates. Our MixFormer sets a new state-of-the-art performance on five tracking benchmarks, including LaSOT, TrackingNet, VOT2020, GOT-10k, and UAV123. In particular, our MixFormer-L achieves NP score of 79.9% on LaSOT, 88.9% on TrackingNet and EAO of 0.555 on VOT2020. We also perform in-depth ablation studies to demonstrate the effectiveness of simultaneous feature extraction and information integration. Code and trained models are publicly available at this https URL.

Added

2026-09-26