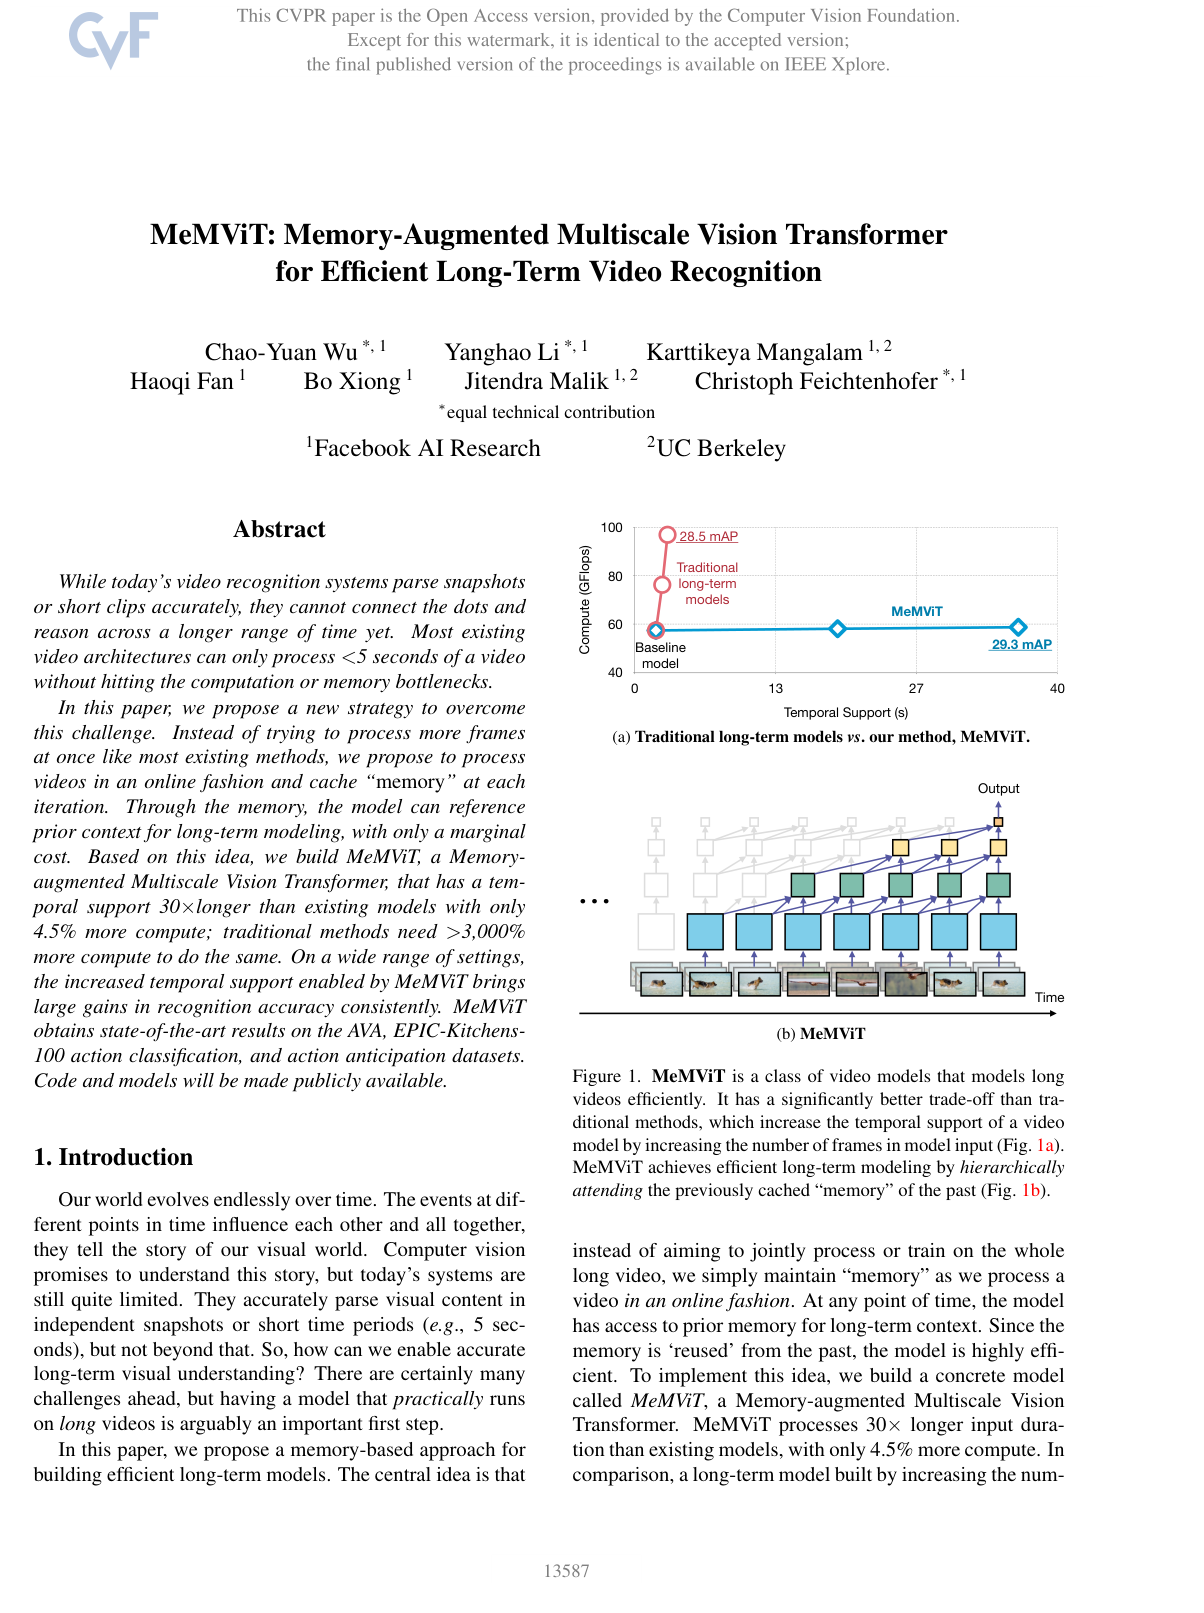
MeMViT, short for Memory-Augmented Multiscale Vision Transformer, is a deep learning architecture designed for efficient long-term video recognition and temporal reasoning. While standard video transformer models face steep computational and memory bottlenecks when attempting to process extended video sequences simultaneously, MeMViT processes video clips sequentially in an online streaming manner and caches past representations into a persistent memory. By allowing subsequent transformer layers to cross-attend to this cached historical context, the architecture enables models to connect information across long durations of video with minimal additional computational overhead, facilitating scalable performance on tasks such as long-term action classification and action anticipation.