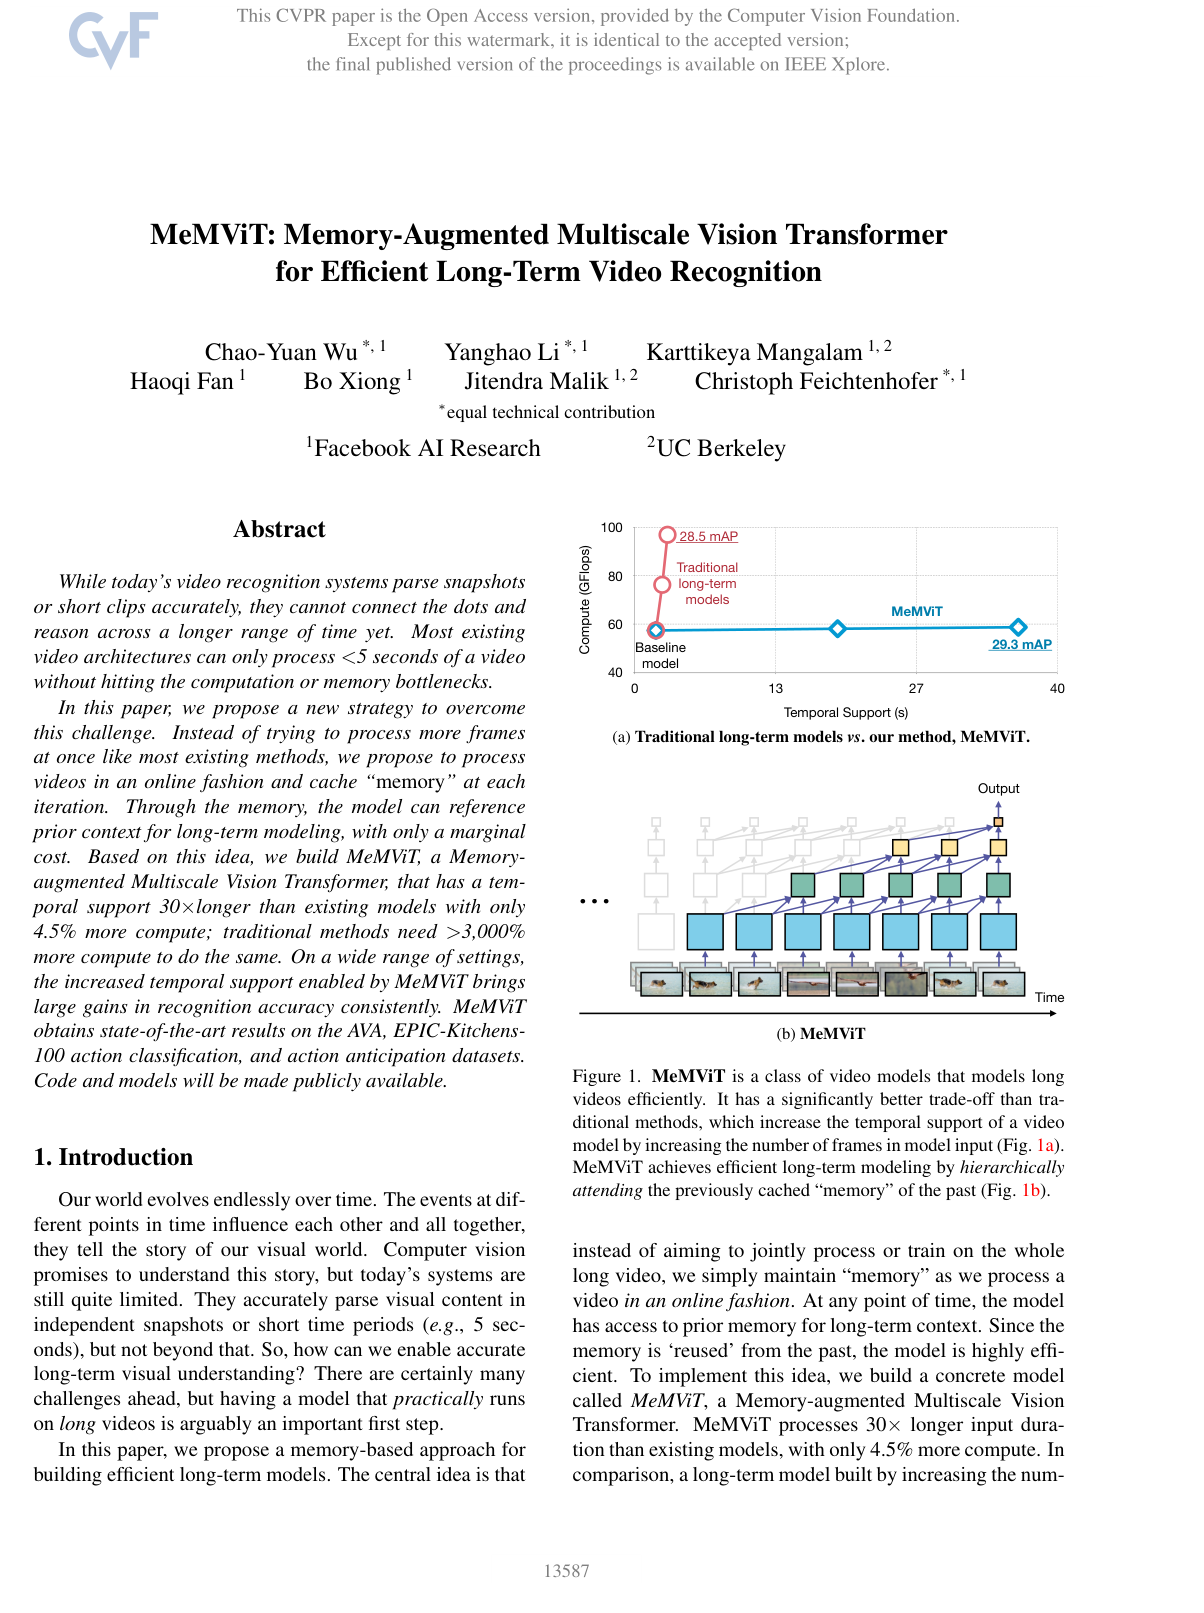
A Memory-Augmented Multiscale Vision Transformer is a computer vision neural network architecture designed for efficient, long-term video understanding by integrating a persistent temporal memory mechanism into a multiscale transformer framework. Instead of attempting to process an entire extended video sequence simultaneously, which creates severe computational and memory bottlenecks, the architecture processes video clips sequentially and caches intermediate feature representations over time. Current and subsequent segments then attend to these stored memory states across multiple hierarchical feature scales, allowing the model to capture long-range temporal dependencies and contextual history across extended durations with minimal additional computational overhead.