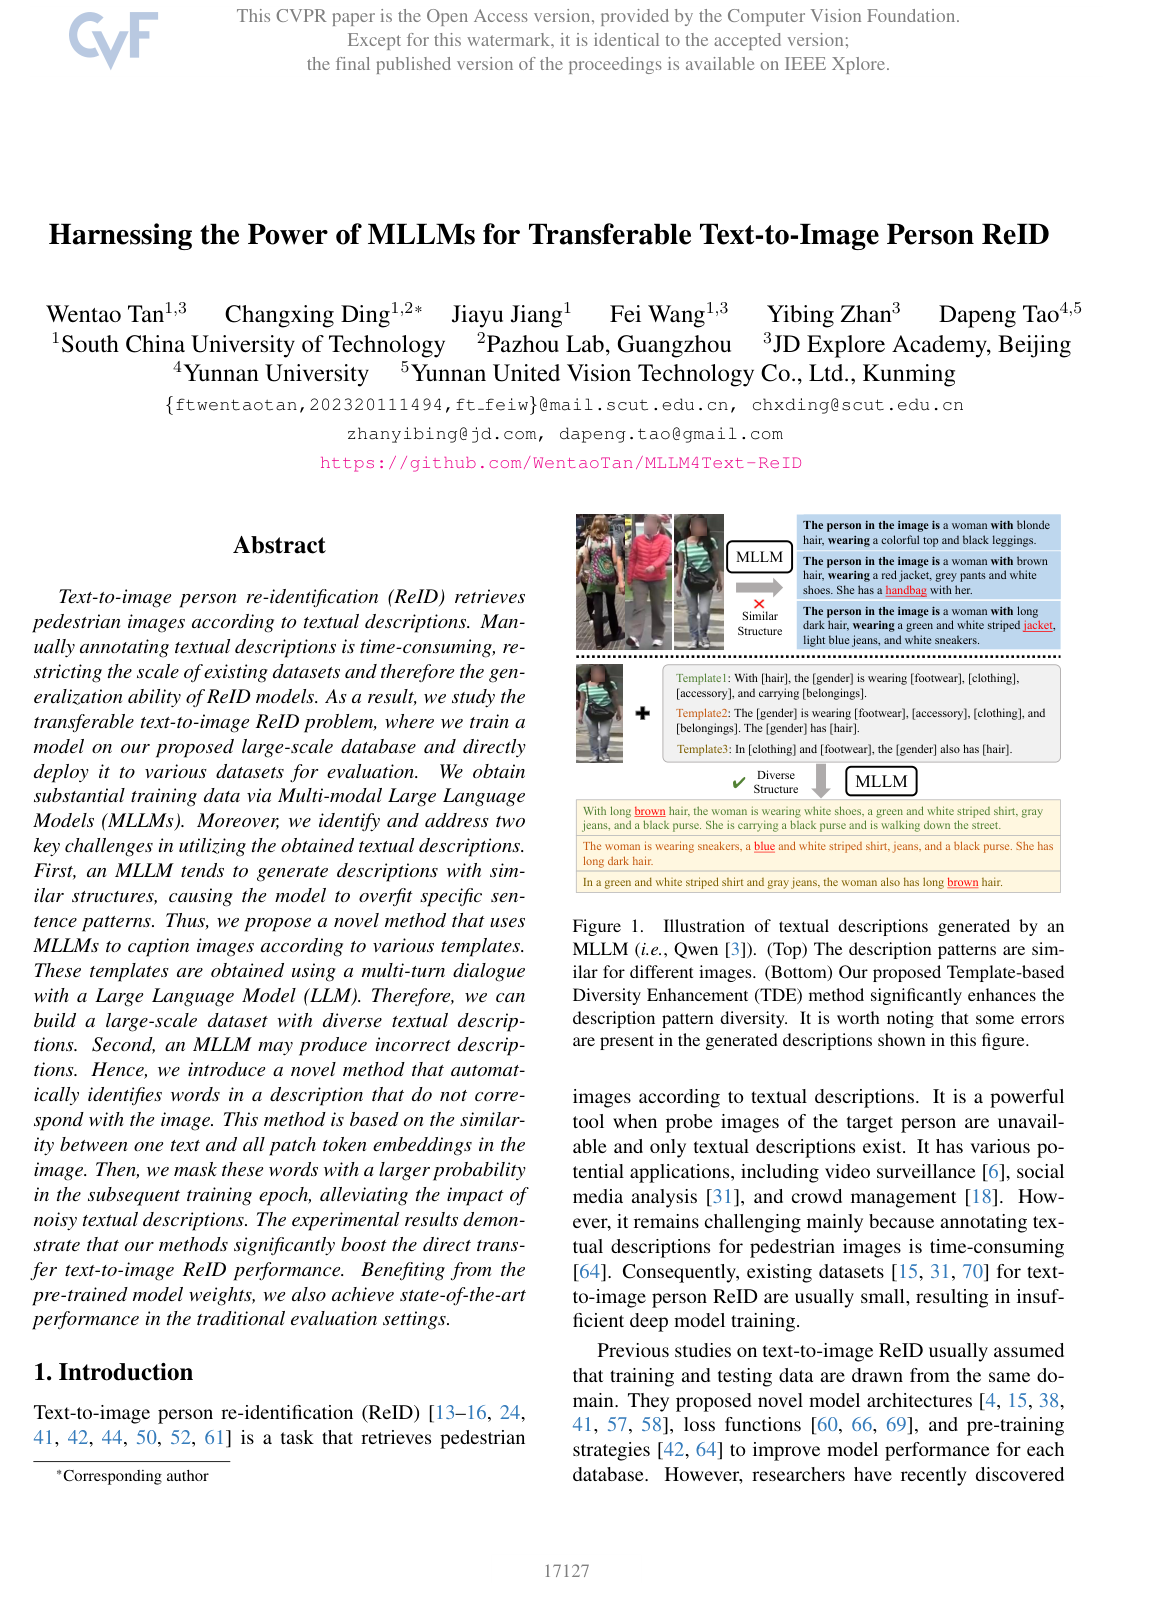
The LUPerson-MLLM dataset is a large-scale multimodal dataset designed for text-to-image person re-identification, constructed by pairing pedestrian images from the LUPerson dataset with rich textual descriptions generated by multimodal large language models. Developed to address the scalability limits and high costs of manual text annotation, it leverages varied prompt templates to generate linguistically diverse pedestrian captions, mitigating syntactic repetition and model overfitting. The dataset is primarily used for pre-training cross-modal models to associate detailed visual features of individuals with natural language queries, improving the zero-shot generalization and direct transfer performance of pedestrian retrieval systems across diverse target environments.