Built independently by an author, for readers. Read the story and support ChapterPal

keyword

long-term video recognition

Long-term video recognition is a computer vision task focused on identifying, classifying, and understanding actions, events, or complex activities across extended temporal durations rather than within isolated, short video clips. While conventional video recognition models typically analyze brief segments spanning only a few seconds due to memory and computational bottlenecks, long-term recognition requires systems to capture and reason over long-range temporal context spanning minutes, hours, or full-length videos. Successfully performing this task involves tracking sequential dependencies, contextual changes, and temporally distant interactions over time, typically through techniques such as persistent memory caching, hierarchical modeling, and efficient temporal aggregation architectures.

1 item

MeMViT: Memory-Augmented Multiscale Vision Transformer for Efficient Long-Term Video Recognition

MeMViT: Memory-Augmented Multiscale Vision Transformer for Efficient Long-Term Video Recognition

Chao-Yuan Wu, Yanghao Li, Karttikeya Mangalam, Haoqi Fan, Bo Xiong, Jitendra Malik, Christoph Feichtenhofer

OrganizationsMetaUniversity of California Berkeley

Why you should read this

Presents a memory-augmented multiscale vision transformer that processes videos sequentially and caches past representations, extending temporal context length by thirty times with only a four-and-a-half percent computational increase to achieve state-of-the-art long-term video recognition.

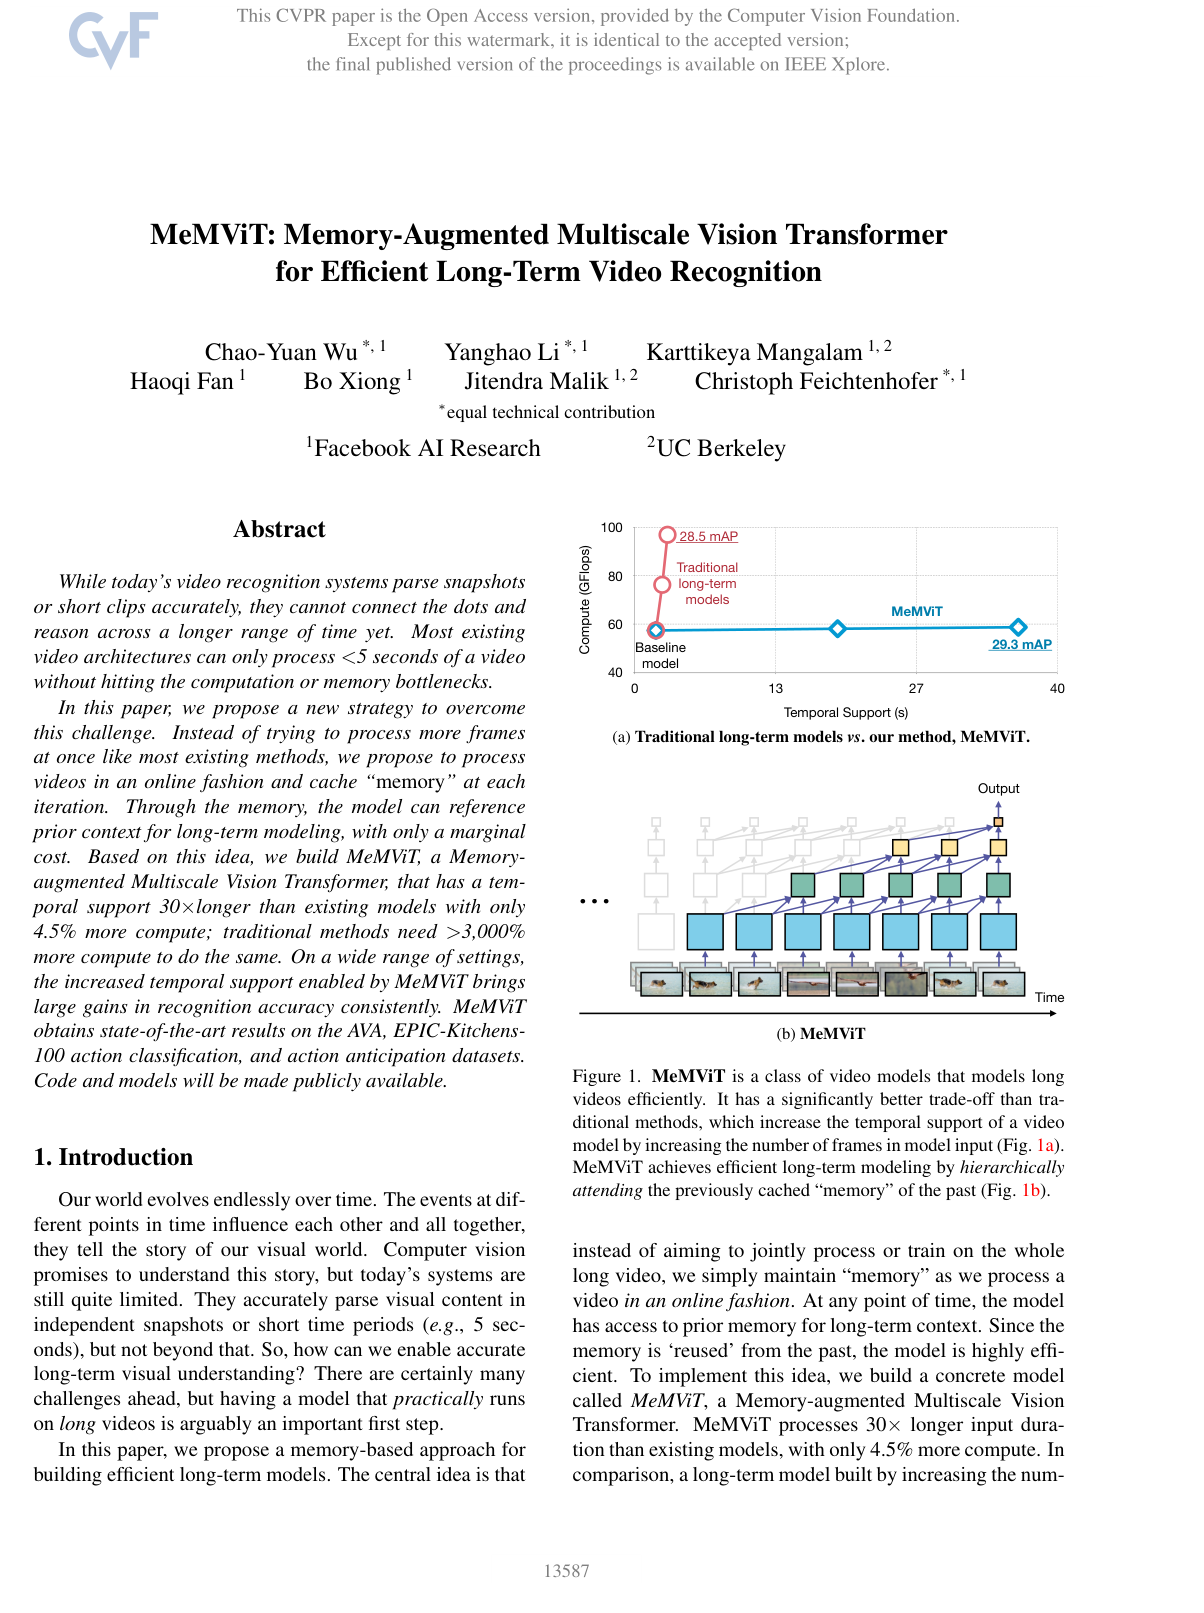
While today’s video recognition systems parse snapshots or short clips accurately, they cannot connect the dots and reason across a longer range of time yet. Most existing video architectures can only process <5 seconds of a video without hitting the computation or memory bottlenecks. In this paper, we propose a new strategy to overcome this challenge. Instead of trying to process more frames at once like most existing methods, we propose to process videos in an online fashion and cache “memory” at each iteration. Through the memory, the model can reference prior context for long-term modeling, with only a marginal cost. Based on this idea, we build MeMViT, a Memory-augmented Multiscale Vision Transformer, that has a temporal support 30× longer than existing models with only 4.5% more compute; traditional methods need >3,000% more compute to do the same. On a wide range of settings, the increased temporal support enabled by MeMViT brings large gains in recognition accuracy consistently. MeMViT obtains state-of-the-art results on the AVA, EPIC-Kitchens-100 action classification, and action anticipation datasets. Code and models will be made publicly available.

Added

2026-09-26