Built independently by an author, for readers. Read the story and support ChapterPal

keyword

long-duration video understanding

Long-duration video understanding is the capability of artificial intelligence and computer vision systems to process, analyze, and accurately comprehend continuous video content spanning extended timeframes, typically ranging from several minutes to hours. Unlike standard video processing that focuses on isolated actions or short-term visual clips, long-duration video understanding requires models to capture complex temporal dynamics, track long-range dependencies, and synthesize contextual relationships across vast amounts of visual and auditory information. Systems designed for this task often integrate interleaved multimodal data, such as video frames, speech, and subtitles, to perform complex reasoning, long-context question answering, event localization, and global narrative interpretation over extended temporal horizons.

1 item

LongVideoBench: A Benchmark for Long-context Interleaved Video-Language Understanding

LongVideoBench: A Benchmark for Long-context Interleaved Video-Language Understanding

Haoning Wu, Dongxu Li, Bei Chen, Junnan Li

Why you should read this

Establishes LongVideoBench, a challenging benchmark of hour-long interleaved video-subtitle inputs and a novel referring reasoning task that exposes substantial performance gaps in leading large multimodal models.

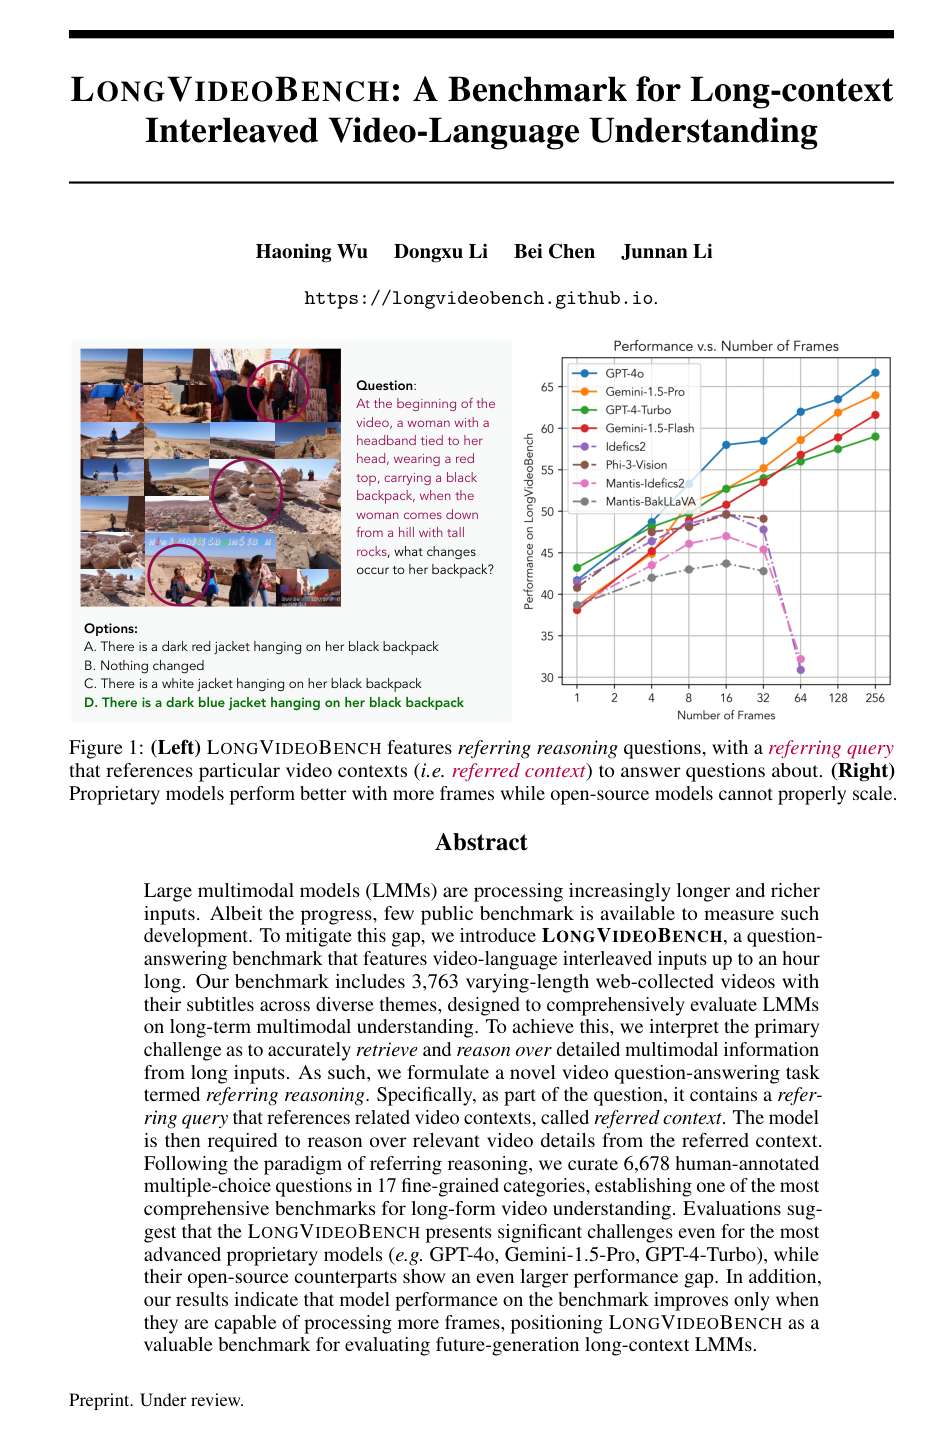
Large multimodal models (LMMs) are processing increasingly longer and richer inputs. Albeit the progress, few public benchmark is available to measure such development. To mitigate this gap, we introduce LongVideoBench, a question-answering benchmark that features video-language interleaved inputs up to an hour long. Our benchmark includes 3,763 varying-length web-collected videos with their subtitles across diverse themes, designed to comprehensively evaluate LMMs on long-term multimodal understanding. To achieve this, we interpret the primary challenge as to accurately retrieve and reason over detailed multimodal information from long inputs. As such, we formulate a novel video question-answering task termed referring reasoning. Specifically, as part of the question, it contains a referring query that references related video contexts, called referred context. The model is then required to reason over relevant video details from the referred context. Following the paradigm of referring reasoning, we curate 6,678 human-annotated multiple-choice questions in 17 fine-grained categories, establishing one of the most comprehensive benchmarks for long-form video understanding. Evaluations suggest that the LongVideoBench presents significant challenges even for the most advanced proprietary models (e.g. GPT-4o, Gemini-1.5-Pro, GPT-4-Turbo), while their open-source counterparts show an even larger performance gap. In addition, our results indicate that model performance on the benchmark improves only when they are capable of processing more frames, positioning LongVideoBench as a valuable benchmark for evaluating future-generation long-context LMMs.

Added

2026-09-27