Built independently by an author, for readers. Read the story and support ChapterPal

keyword

Llama-2 family

The Llama-2 family is a collection of open-weight, autoregressive large language models developed and released by Meta in 2023 for research and commercial use. Built on the transformer architecture and pretrained on two trillion tokens of publicly available text, the collection includes both foundational base models and conversational variants optimized for dialogue through supervised fine-tuning and reinforcement learning from human feedback. These models are offered across multiple scale sizes, specifically 7 billion, 13 billion, and 70 billion parameters, and are designed to perform a wide variety of natural language processing tasks while serving as an accessible foundation for generative artificial intelligence applications.

1 item

Do Llamas Work in English? On the Latent Language of Multilingual Transformers

Do Llamas Work in English? On the Latent Language of Multilingual Transformers

Chris Wendler, Veniamin Veselovsky, Giovanni Monea, Robert West

OrganizationsÉcole Polytechnique Fédérale de Lausanne

Why you should read this

Reveals through logit lens analysis that multilingual transformer models route non-English inputs through an internal, English-aligned concept space in intermediate layers before decoding them into the target language.

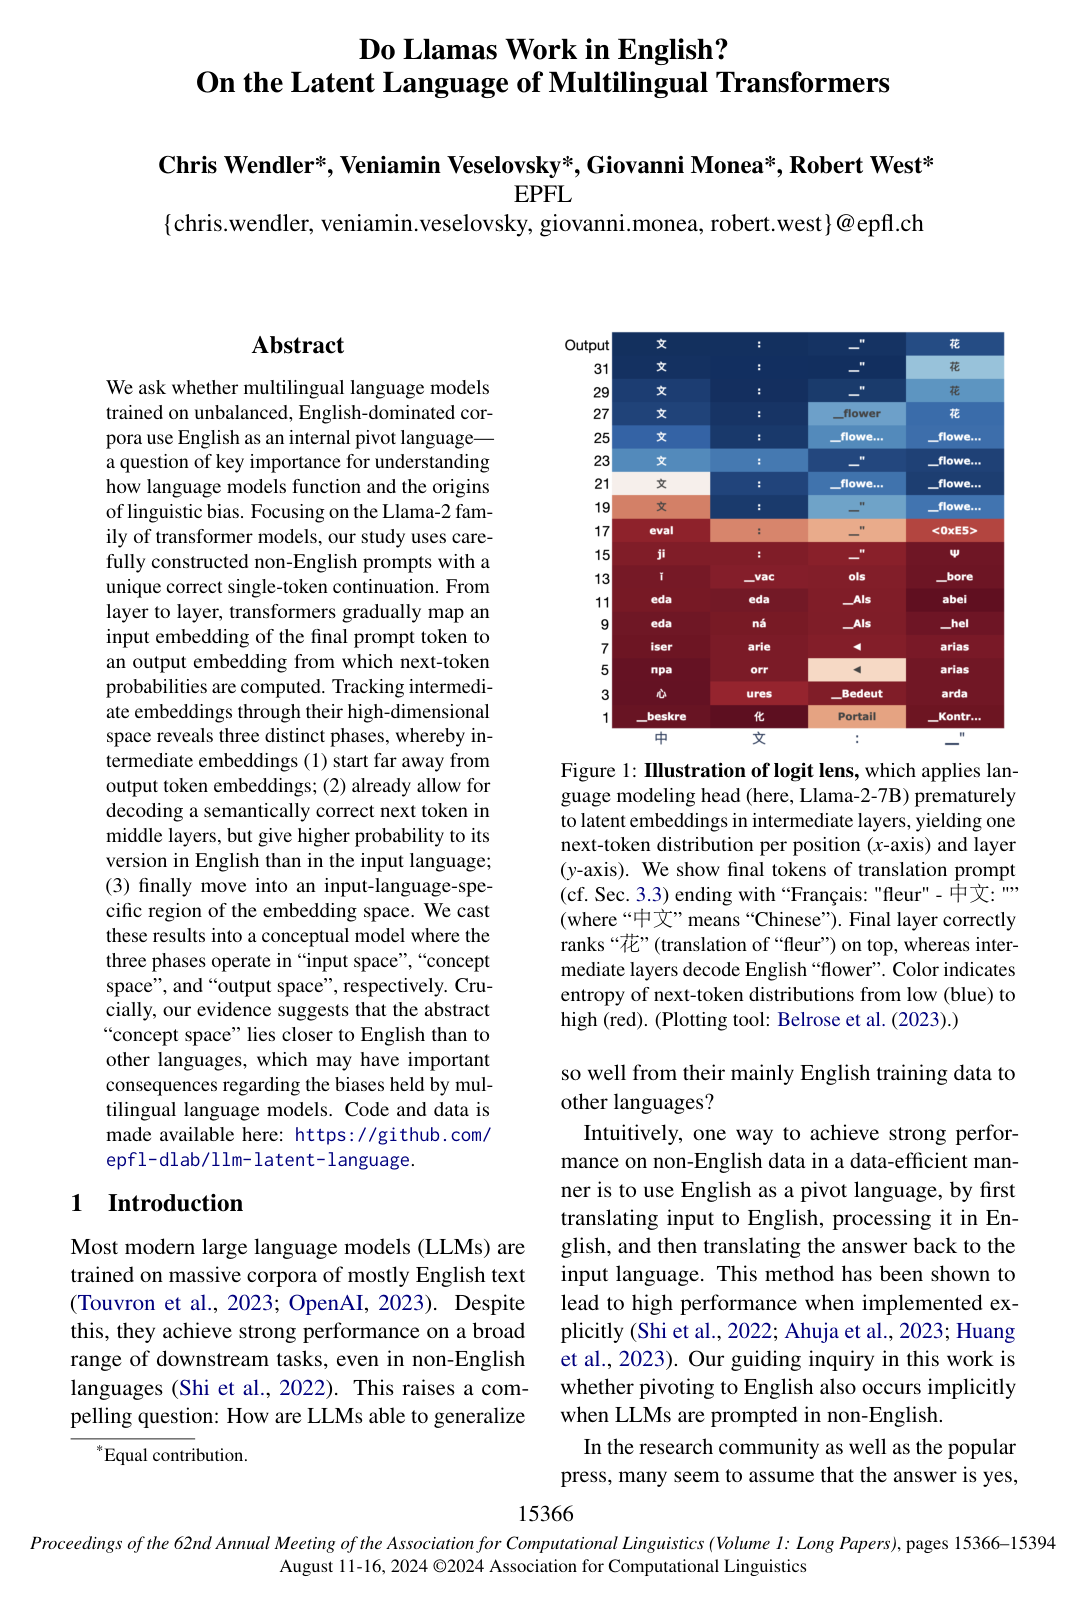
We ask whether multilingual language models trained on unbalanced, English-dominated corpora use English as an internal pivot language—a question of key importance for understanding how language models function and the origins of linguistic bias. Focusing on the Llama-2 family of transformer models, our study uses carefully constructed non-English prompts with a unique correct single-token continuation. From layer to layer, transformers gradually map an input embedding of the final prompt token to an output embedding from which next-token probabilities are computed. Tracking intermediate embeddings through their high-dimensional space reveals three distinct phases, whereby intermediate embeddings (1) start far away from output token embeddings; (2) already allow for decoding a semantically correct next token in middle layers, but give higher probability to its version in English than in the input language; (3) finally move into an input-language-specific region of the embedding space. We cast these results into a conceptual model where the three phases operate in “input space”, “concept space”, and “output space”, respectively. Crucially, our evidence suggests that the abstract “concept space” lies closer to English than to other languages, which may have important consequences regarding the biases held by multilingual language models. Code and data is made available here: https://github.com/epfl-dlab/llm-latent-language.

Added

2026-09-26