Built independently by an author, for readers. Read the story and support ChapterPal

keyword

layer-wise analysis

Layer-wise analysis is an evaluative approach in deep learning that examines the representations, behaviors, and properties across the individual successive layers of a neural network rather than assessing only the final output. By inspecting each intermediate stage of computation, this method evaluates how data transformations, feature abstraction, information retention, and semantic encoding evolve as inputs propagate through the architecture. It provides insight into the internal mechanics of complex models, helping researchers identify which network depths capture specific types of knowledge, utilize intermediate embeddings for downstream tasks, and understand how representations are progressively refined from input to output.

1 item

Layer by Layer: Uncovering Hidden Representations in Language Models

Layer by Layer: Uncovering Hidden Representations in Language Models

Oscar Skean, Md Rifat Arefin, Dan Zhao, Niket Patel, Jalal Naghiyev, Yann LeCun, Ravid Shwartz-Ziv

OrganizationsMetaMila – Québec Artificial Intelligence InstituteNew York UniversityUniversité de MontréalUniversity of California, Los AngelesUniversity of KentuckyWand.AI

Why you should read this

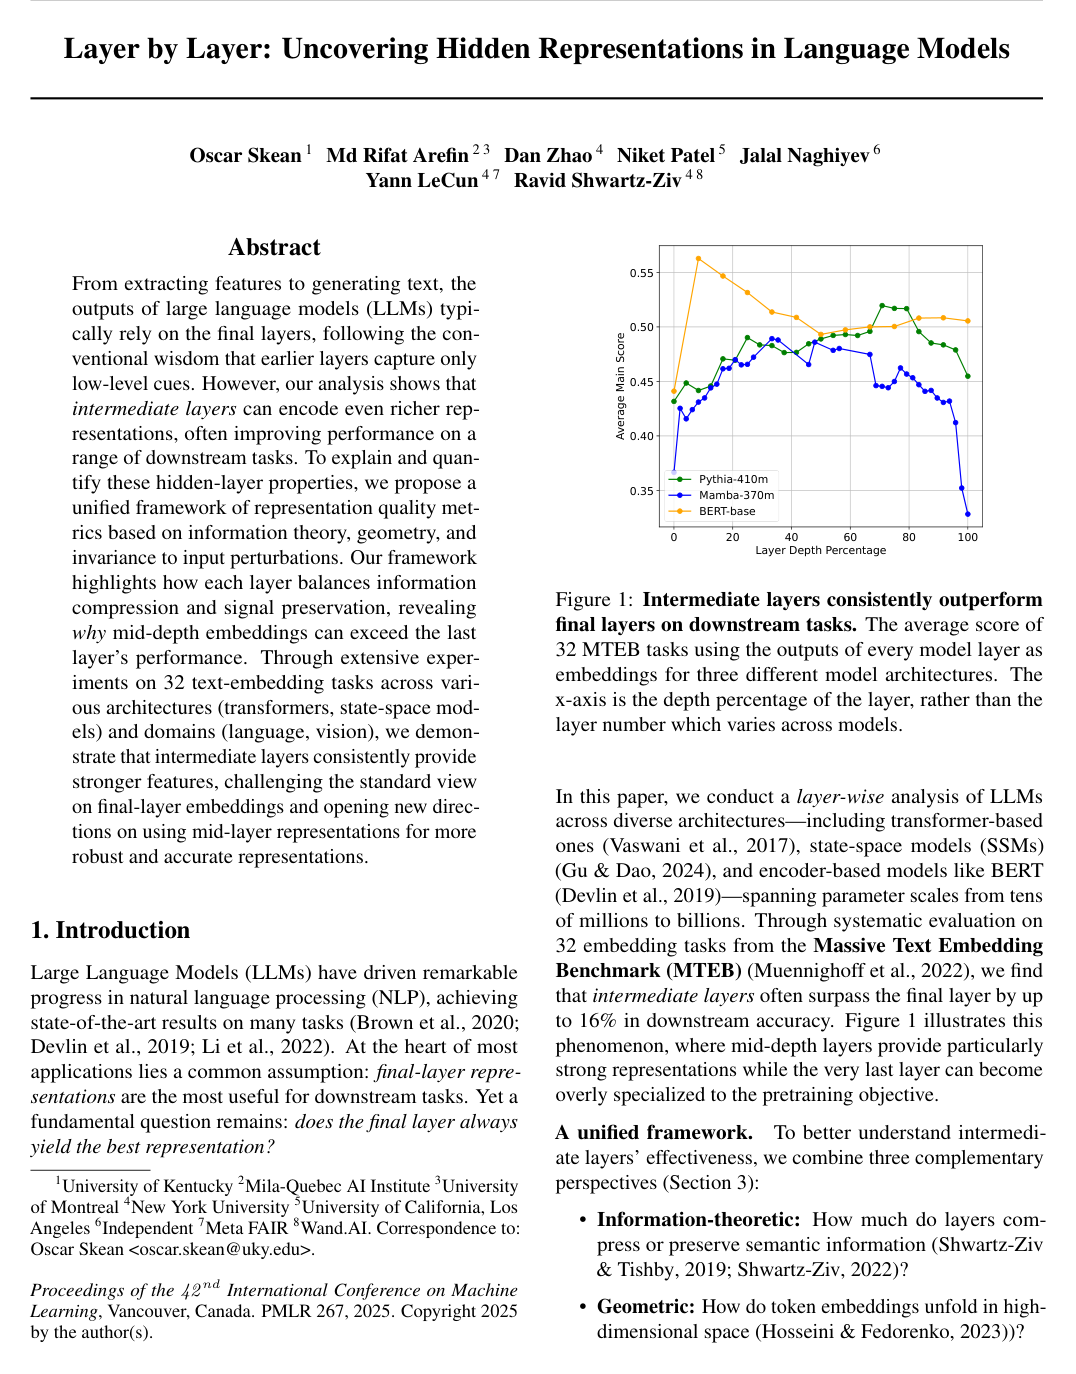
Demonstrates that intermediate layers in language models consistently produce richer representations than the final layer, introducing a geometric and information-theoretic framework that explains why mid-depth embeddings achieve superior performance across diverse downstream tasks.

From extracting features to generating text, the outputs of large language models (LLMs) typically rely on the final layers, following the conventional wisdom that earlier layers capture only low-level cues. However, our analysis shows that intermediate layers can encode even richer representations, often improving performance on a range of downstream tasks. To explain and quantify these hidden-layer properties, we propose a unified framework of representation quality metrics based on information theory, geometry, and invariance to input perturbations. Our framework highlights how each layer balances information compression and signal preservation, revealing why mid-depth embeddings can exceed the last layer's performance. Through extensive experiments on 32 text-embedding tasks across various architectures (transformers, state-space models) and domains (language, vision), we demonstrate that intermediate layers consistently provide stronger features, challenging the standard view on final-layer embeddings and opening new directions on using mid-layer representations for more robust and accurate representations.

Added

2026-09-28