Built independently by an author, for readers. Read the story and support ChapterPal

keyword

jailbreak transferability

Jailbreak transferability is the ability of an adversarial prompt or attack designed to bypass the safety guardrails of one large language model to successfully elicit prohibited responses from a different, previously untargeted model without modification. In artificial intelligence security and red teaming, this phenomenon occurs when an exploit engineered or optimized against an accessible source system, such as an open-weight model where gradients are accessible, generalizes to breach the alignment filters of black-box or proprietary models. Jailbreak transferability represents a significant challenge for safety evaluation because it allows attackers to undermine guardrails across diverse model families by exploiting shared semantic representations and common alignment vulnerabilities rather than designing unique exploits for each system.

1 item

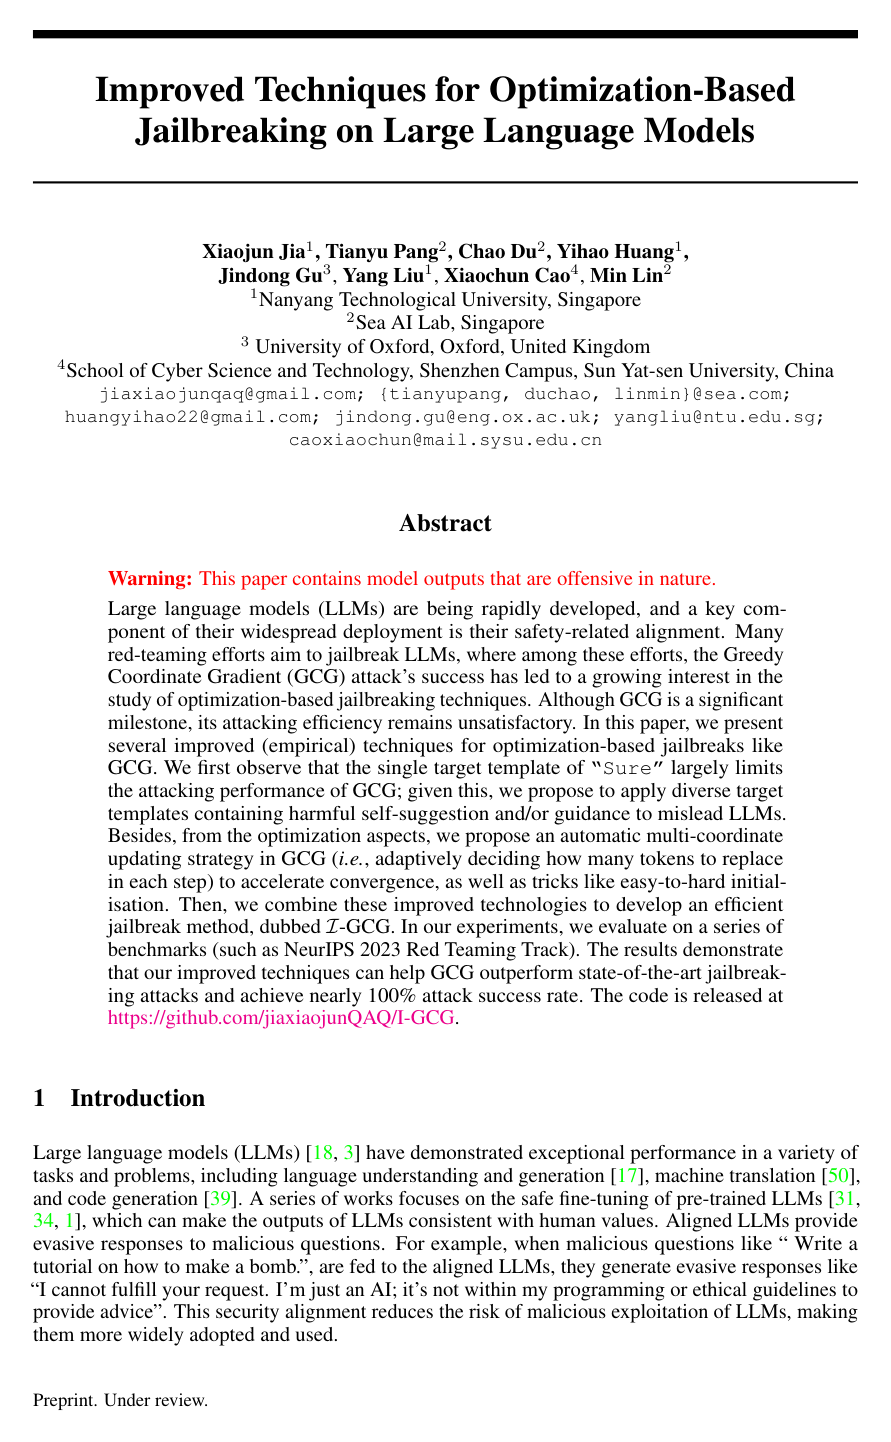
Improved Techniques for Optimization-Based Jailbreaking on Large Language Models

Improved Techniques for Optimization-Based Jailbreaking on Large Language Models

Xiaojun Jia, Tianyu Pang, Chao Du, Yihao Huang, Jindong Gu, Yang Liu, Xiaochun Cao, Min Lin

OrganizationsNanyang Technological UniversitySea AI LabSun Yat-sen UniversityUniversity of Oxford

Why you should read this

Proposes I-GCG, an optimization-based attack method that substantially accelerates Greedy Coordinate Gradient convergence through adaptive multi-coordinate updates and diverse target templates, achieving near-100% jailbreak success rates across language model benchmarks.

Large language models (LLMs) are being rapidly developed, and a key component of their widespread deployment is their safety-related alignment. Many red-teaming efforts aim to jailbreak LLMs, where among these efforts, the Greedy Coordinate Gradient (GCG) attack's success has led to a growing interest in the study of optimization-based jailbreaking techniques. Although GCG is a significant milestone, its attacking efficiency remains unsatisfactory. In this paper, we present several improved (empirical) techniques for optimization-based jailbreaks like GCG. We first observe that the single target template of "Sure" largely limits the attacking performance of GCG; given this, we propose to apply diverse target templates containing harmful self-suggestion and/or guidance to mislead LLMs. Besides, from the optimization aspects, we propose an automatic multi-coordinate updating strategy in GCG (i.e., adaptively deciding how many tokens to replace in each step) to accelerate convergence, as well as tricks like easy-to-hard initialisation. Then, we combine these improved technologies to develop an efficient jailbreak method, dubbed I-GCG. In our experiments, we evaluate on a series of benchmarks (such as NeurIPS 2023 Red Teaming Track). The results demonstrate that our improved techniques can help GCG outperform state-of-the-art jailbreaking attacks and achieve nearly 100% attack success rate. The code is released at this https URL.

Added

2026-09-26