
keyword
intermediate embeddings
Intermediate embeddings are vector representations of data generated by the hidden layers of a deep neural network, situated between the initial input layer and the final output layer. In multi-layer architectures such as transformer language models, input tokens are initially mapped into continuous vector spaces and then iteratively transformed layer by layer, producing updated internal representations that capture increasingly abstract syntactic, semantic, and contextual features across network depth. These internal vector states allow researchers and practitioners to inspect a model's latent information flow, track how representations evolve through distinct computational phases, and analyze intermediate predictions before the network projects representations to the final output vocabulary.
2 items
Do Llamas Work in English? On the Latent Language of Multilingual Transformers
Chris Wendler, Veniamin Veselovsky, Giovanni Monea, Robert West
Why you should read this
Reveals through logit lens analysis that multilingual transformer models route non-English inputs through an internal, English-aligned concept space in intermediate layers before decoding them into the target language.
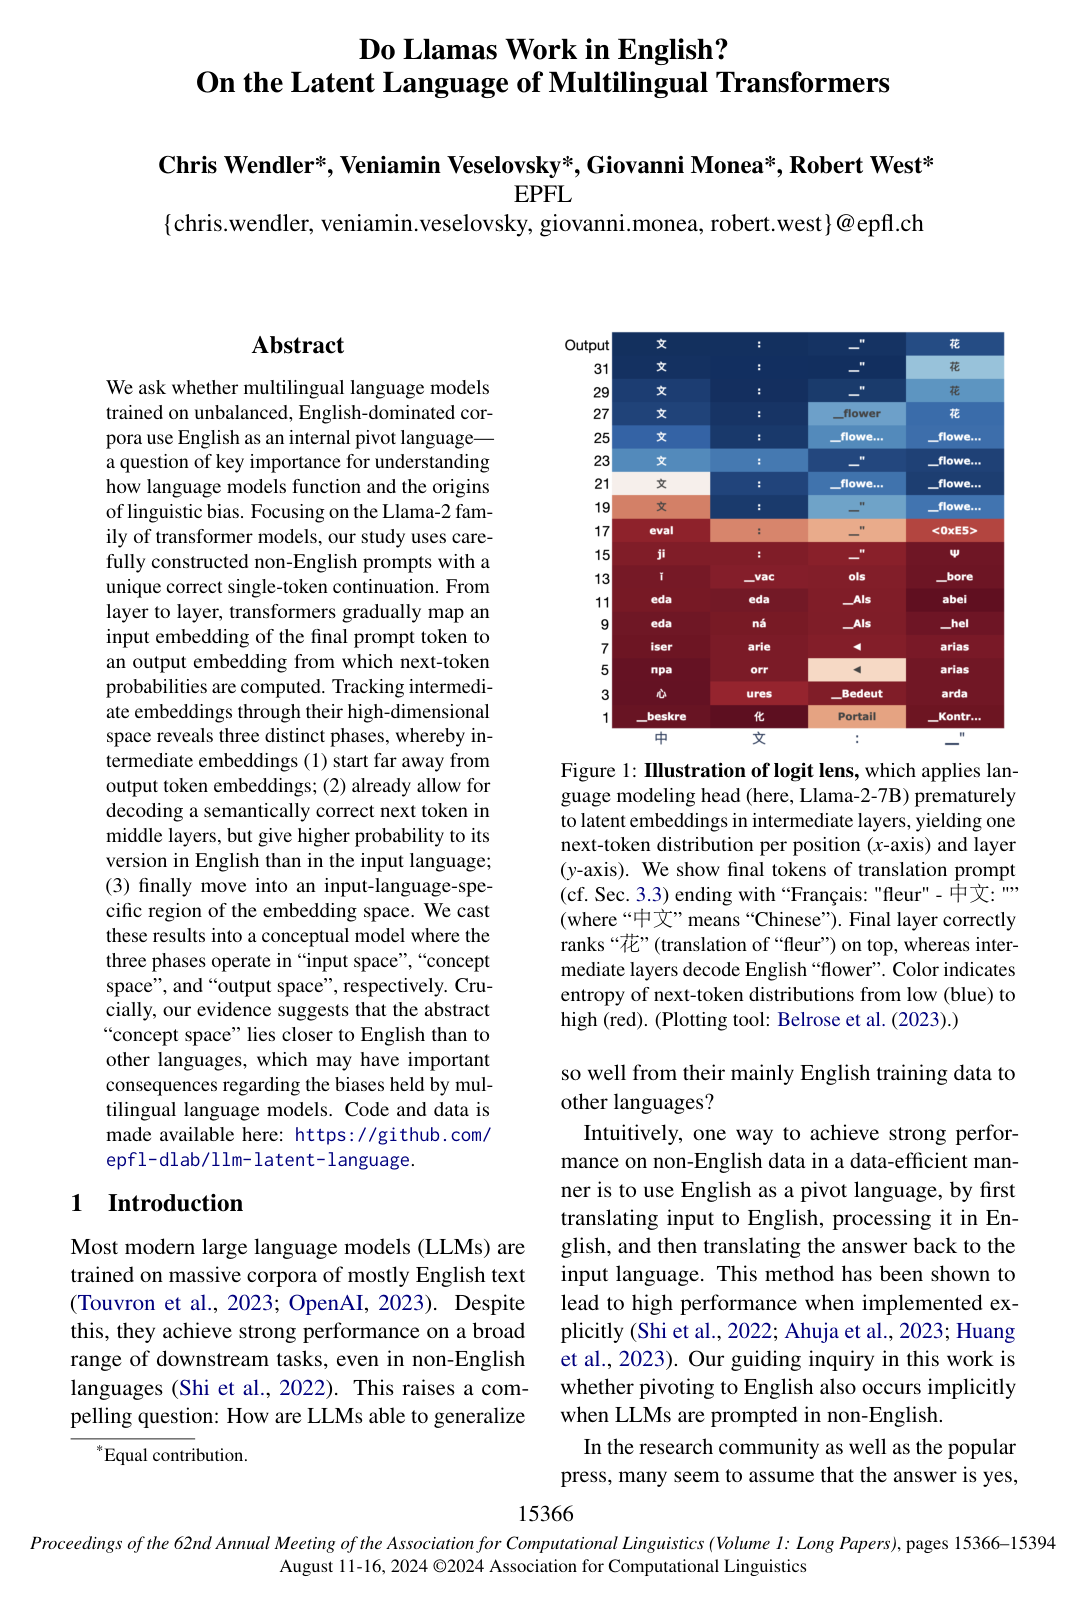
We ask whether multilingual language models trained on unbalanced, English-dominated corpora use English as an internal pivot language—a question of key importance for understanding how language models function and the origins of linguistic bias. Focusing on the Llama-2 family of transformer models, our study uses carefully constructed non-English prompts with a unique correct single-token continuation. From layer to layer, transformers gradually map an input embedding of the final prompt token to an output embedding from which next-token probabilities are computed. Tracking intermediate embeddings through their high-dimensional space reveals three distinct phases, whereby intermediate embeddings (1) start far away from output token embeddings; (2) already allow for decoding a semantically correct next token in middle layers, but give higher probability to its version in English than in the input language; (3) finally move into an input-language-specific region of the embedding space. We cast these results into a conceptual model where the three phases operate in “input space”, “concept space”, and “output space”, respectively. Crucially, our evidence suggests that the abstract “concept space” lies closer to English than to other languages, which may have important consequences regarding the biases held by multilingual language models. Code and data is made available here: https://github.com/epfl-dlab/llm-latent-language.
Added
2026-09-26
Language Models Are Implicitly Continuous
Samuele Marro, Davide Evangelista, X. Angelo Huang, Emanuele La Malfa, Michele Lombardi, Michael Wooldridge
Why you should read this
Demonstrates that state-of-the-art Large Language Models implicitly learn to represent language as continuous-time functions, fundamentally challenging our understanding of how LLMs process information and opening new avenues for linguistic and engineering advancements.
Language is typically modelled with discrete sequences. However, the most successful approaches to language modelling, namely neural networks, are continuous and smooth function approximators. In this work, we show that Transformer-based language models implicitly learn to represent sentences as continuous-time functions defined over a continuous input space. This phenomenon occurs in most state-of-the-art Large Language Models (LLMs), including Llama2, Llama3, Phi3, Gemma, Gemma2, and Mistral, and suggests that LLMs reason about language in ways that fundamentally differ from humans. Our work formally extends Transformers to capture the nuances of time and space continuity in both input and output space. Our results challenge the traditional interpretation of how LLMs understand language, with several linguistic and engineering implications.
Added
2026-01-13
License
Published with permission