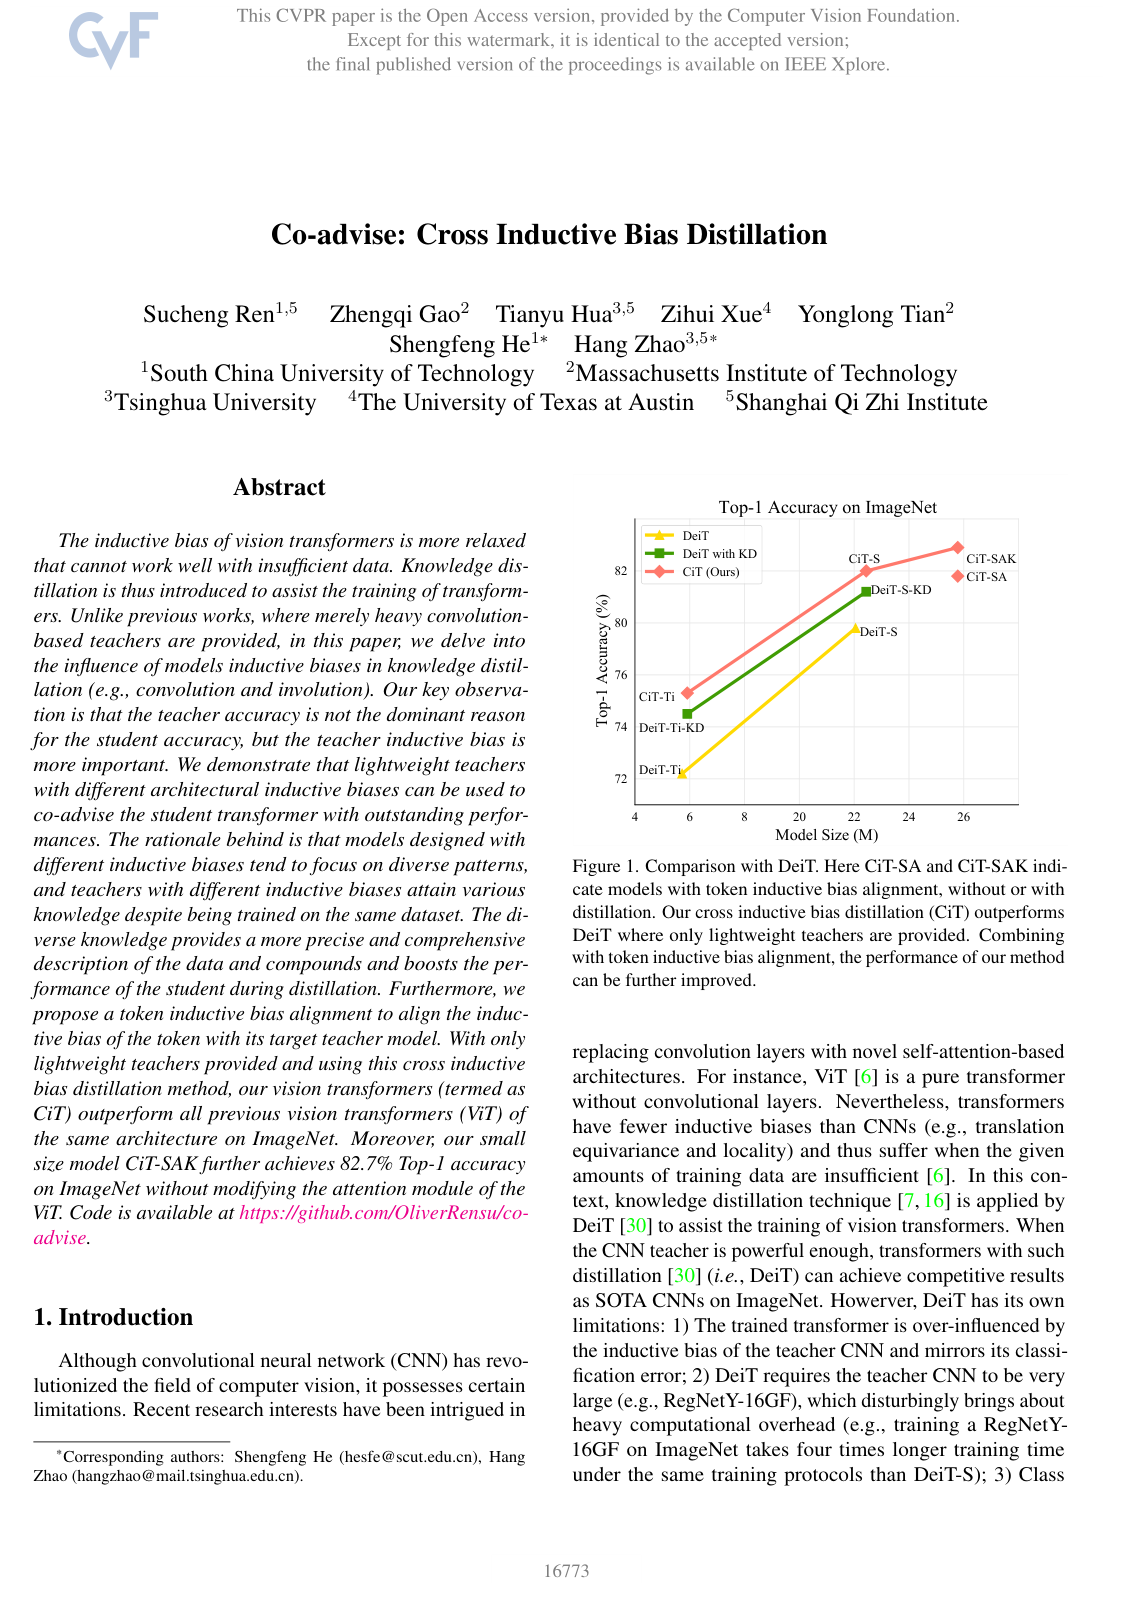
Inductive bias distillation is a machine learning method in knowledge distillation where a student model is trained to acquire the structural assumptions, or inductive biases, inherent in one or more teacher architectures. Unlike conventional distillation that primarily focuses on transferring raw predictive accuracy from larger networks, this approach deliberately transfers architectural priors, such as spatial locality or translation equivariance, from models embedded with strong domain constraints to more flexible, low-bias models like vision transformers. By absorbing the distinct structural patterns captured by these specialized teachers, the student network compensates for its own lack of built-in architectural constraints, resulting in improved data efficiency, feature representation, and generalization without requiring massive training datasets.