Built independently by an author, for readers. Read the story and support ChapterPal

keyword

image person re-identification

Image person re-identification is a computer vision task that involves identifying and matching images of the same individual across different, non-overlapping camera views or throughout a large image database. Given a query representing a specific pedestrian, algorithms extract robust visual feature representations, such as clothing patterns, body shape, and carried accessories, to retrieve corresponding instances of that person from a gallery of images. The primary challenge lies in correctly associating identities despite substantial variations in lighting conditions, camera angles, body poses, image resolutions, and visual occlusions. This technology serves as a foundational component in automated pedestrian tracking, video surveillance analysis, forensic search, and intelligent public safety systems.

1 item

Harnessing the Power of MLLMs for Transferable Text-to-Image Person ReID

Harnessing the Power of MLLMs for Transferable Text-to-Image Person ReID

Wentao Tan, Changxing Ding, Jiayu Jiang, Fei Wang, Yibing Zhan, Dapeng Tao

OrganizationsJD.comPazhou LaboratorySouth China University of TechnologyYunnan United Vision Technology Co., Ltd.Yunnan University

Why you should read this

Proposes a scalable framework for transferable text-to-image person re-identification that uses multimodal large language models to generate diverse text annotations via dynamic templates while filtering out hallucinated descriptions with noise-aware masking.

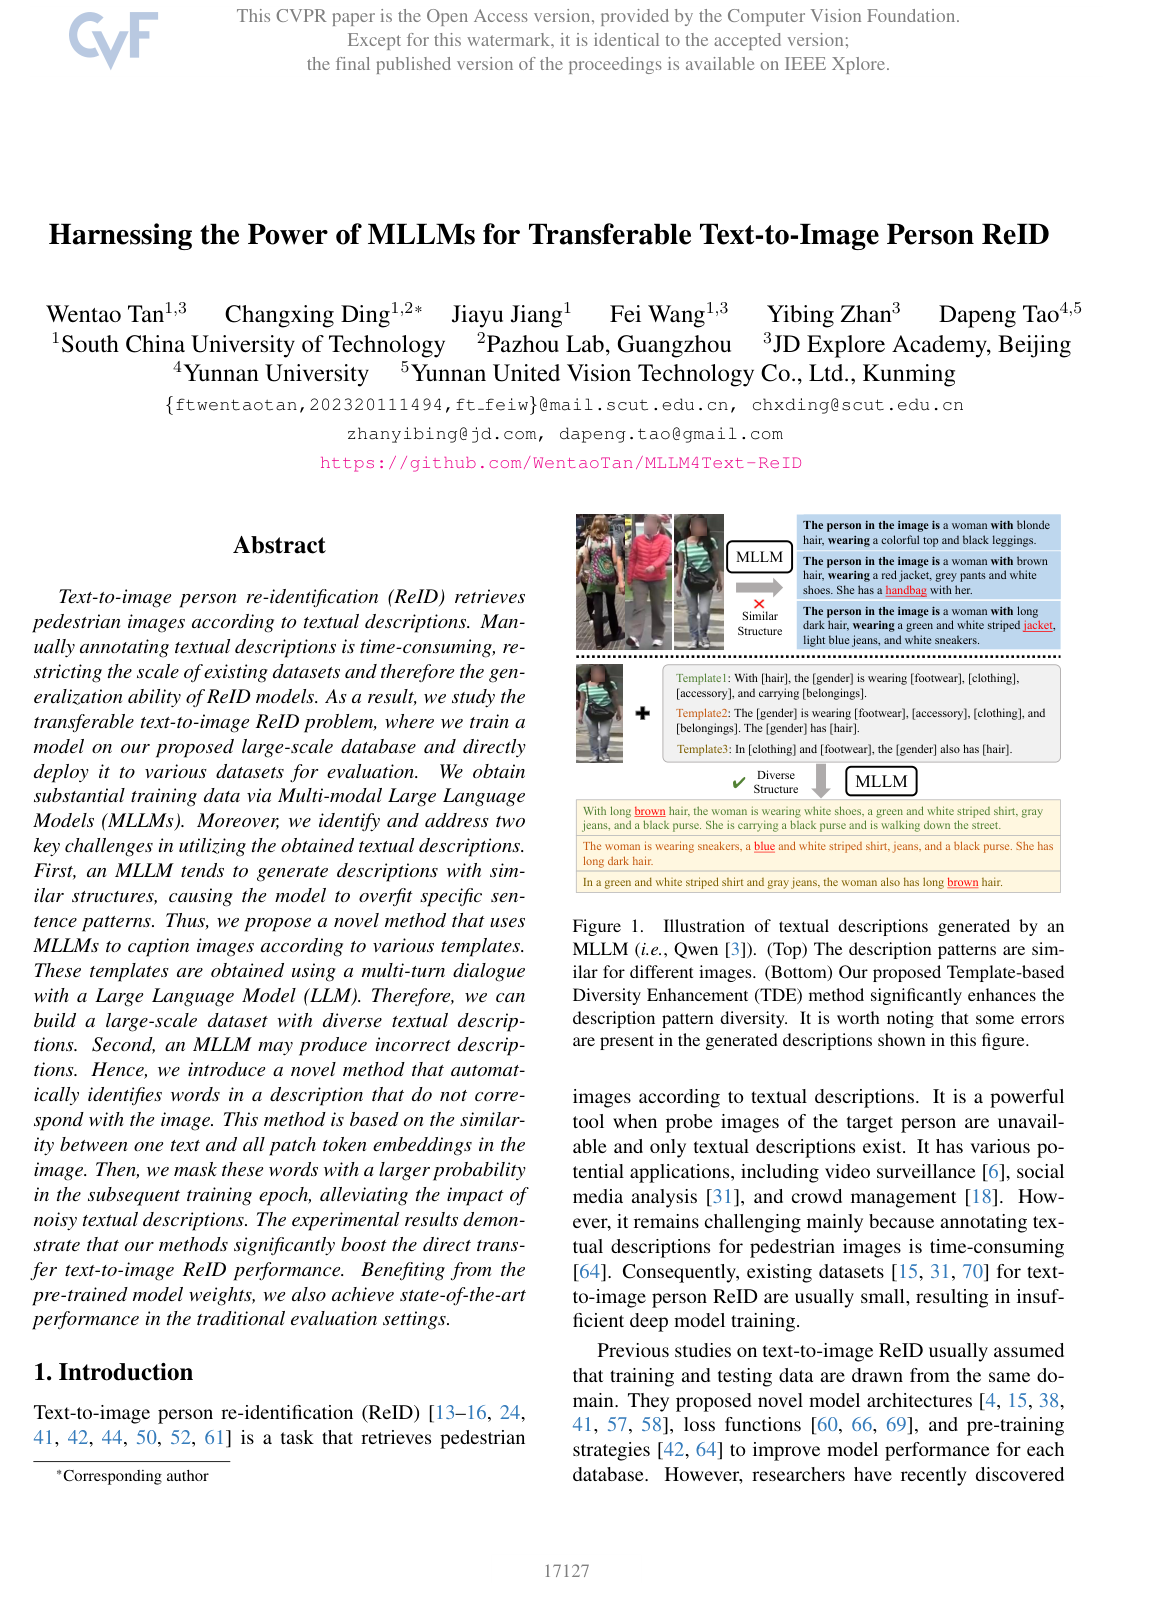
Text-to-image person re-identification (ReID) retrieves pedestrian images according to textual descriptions. Manually annotating textual descriptions is time-consuming, restricting the scale of existing datasets and therefore the generalization ability of ReID models. As a result, we study the transferable text-to-image ReID problem, where we train a model on our proposed large-scale database and directly deploy it to various datasets for evaluation. We obtain substantial training data via Multi-modal Large Language Models (MLLMs). Moreover, we identify and address two key challenges in utilizing the obtained textual descriptions. First, an MLLM tends to generate descriptions with similar structures, causing the model to overfit specific sentence patterns. Thus, we propose a novel method that uses MLLMs to caption images according to various templates. These templates are obtained using a multi-turn dialogue with a Large Language Model (LLM). Therefore, we can build a large-scale dataset with diverse textual descriptions. Second, an MLLM may produce incorrect descriptions. Hence, we introduce a novel method that automatically identifies words in a description that do not correspond with the image. This method is based on the similarity between one text and all patch token embeddings in the image. Then, we mask these words with a larger probability in the subsequent training epoch, alleviating the impact of noisy textual descriptions. The experimental results demonstrate that our methods significantly boost the direct transfer text-to-image ReID performance. Benefiting from the pre-trained model weights, we also achieve state-of-the-art performance in the traditional evaluation settings.

Added

2026-09-26