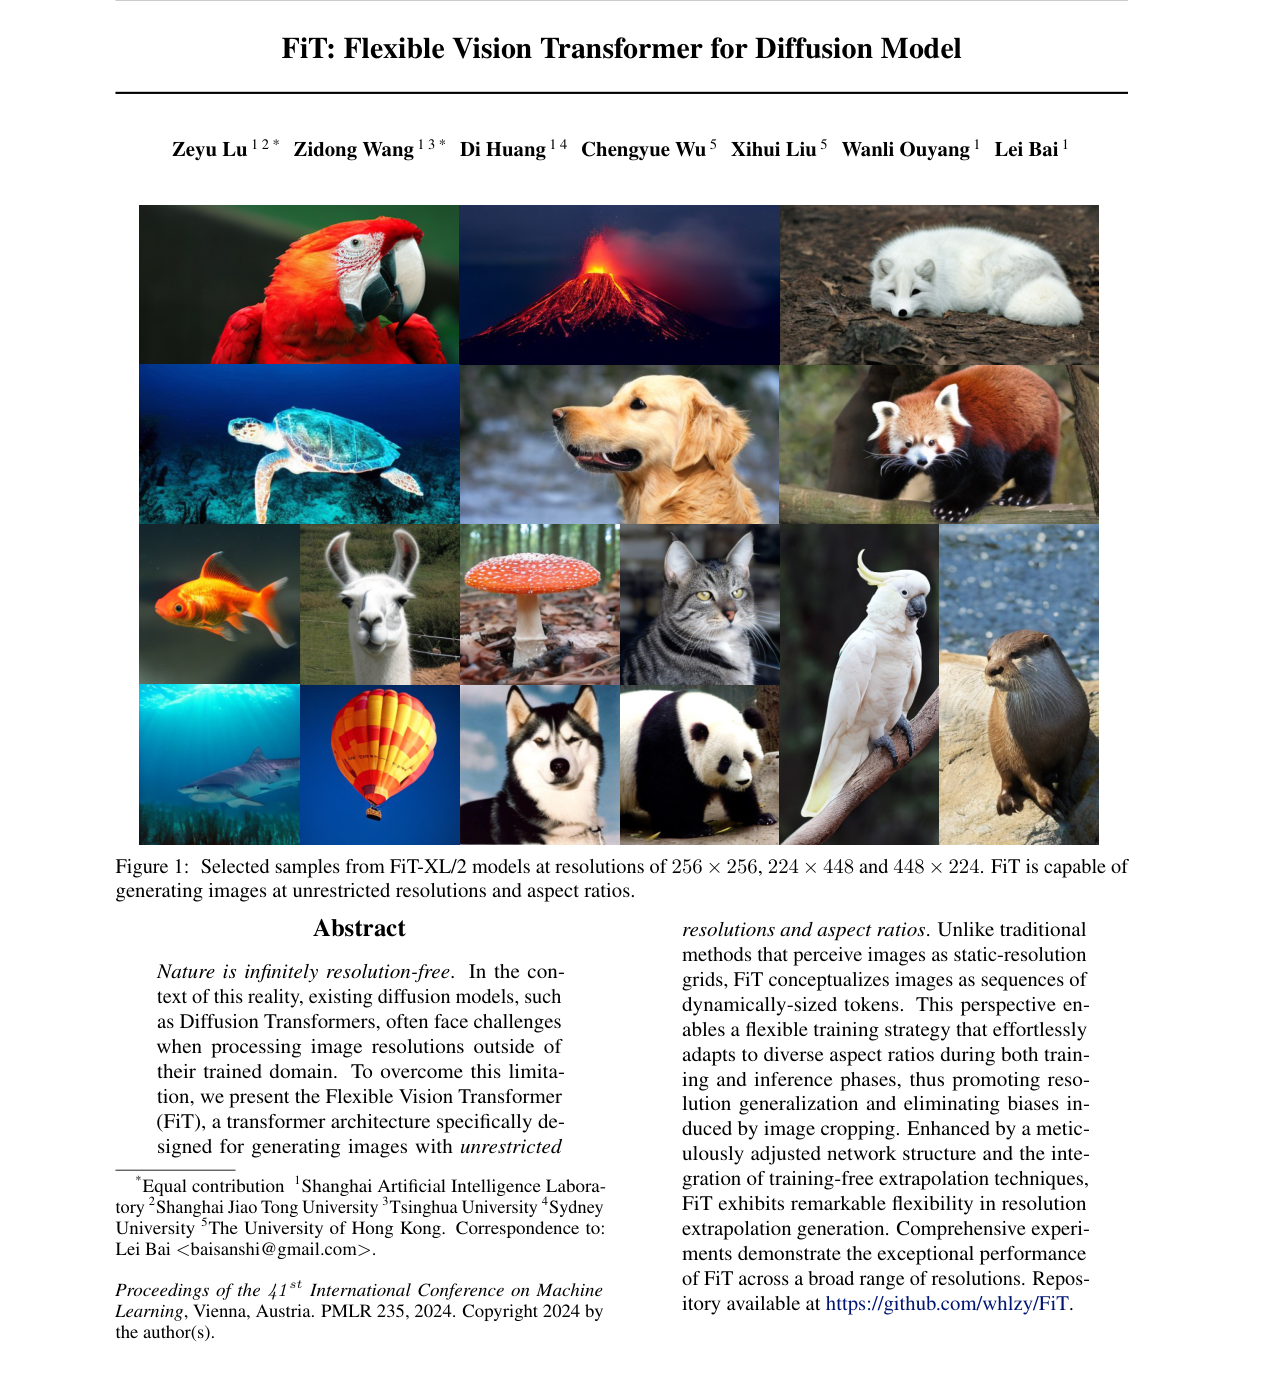
The FiT architecture, short for Flexible Vision Transformer, is a neural network design for diffusion-based image generation that accommodates unrestricted image resolutions and aspect ratios. Rather than treating images as static grids of a fixed size, this architecture conceptualizes visual inputs as sequences of dynamically sized tokens. By managing variable-length token sequences using specialized attention masking and multidimensional positional encodings, it allows models to train and perform inference across diverse image dimensions without the need for fixed cropping or standard resizing. This design eliminates cropping-induced spatial biases and improves the network's ability to extrapolate and generate high-quality visual content beyond its original training resolution.