
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

expression recognition transformer

An expression recognition transformer is a deep learning neural network architecture based on self-attention mechanisms designed to identify and classify human facial expressions and emotional states from visual data. Unlike traditional convolutional neural networks that focus primarily on local pixel neighborhoods, this model processes facial images or video sequences by dividing visual inputs into discrete tokens or patches to learn long-range spatial relationships across different facial regions, such as the eyes, eyebrows, and mouth. When applied to dynamic video, it can also model temporal dependencies and subtle muscle transitions across consecutive frames, providing robust performance against real-world variations in lighting, head pose, and facial occlusion.

1 item
Rethinking the Learning Paradigm for Dynamic Facial Expression Recognition

Rethinking the Learning Paradigm for Dynamic Facial Expression Recognition

Hanyang Wang, Bo Li, Shuang Wu, Siyuan Shen, Feng Liu, Shouhong Ding, Aimin Zhou

OrganizationsEast China Normal UniversityTencent

Why you should read this

Proposes a multi-instance learning framework for dynamic facial expression recognition that treats non-target video frames as weakly supervised data and balances short- and long-term temporal dependencies to achieve state-of-the-art accuracy using a standard 3D CNN backbone.

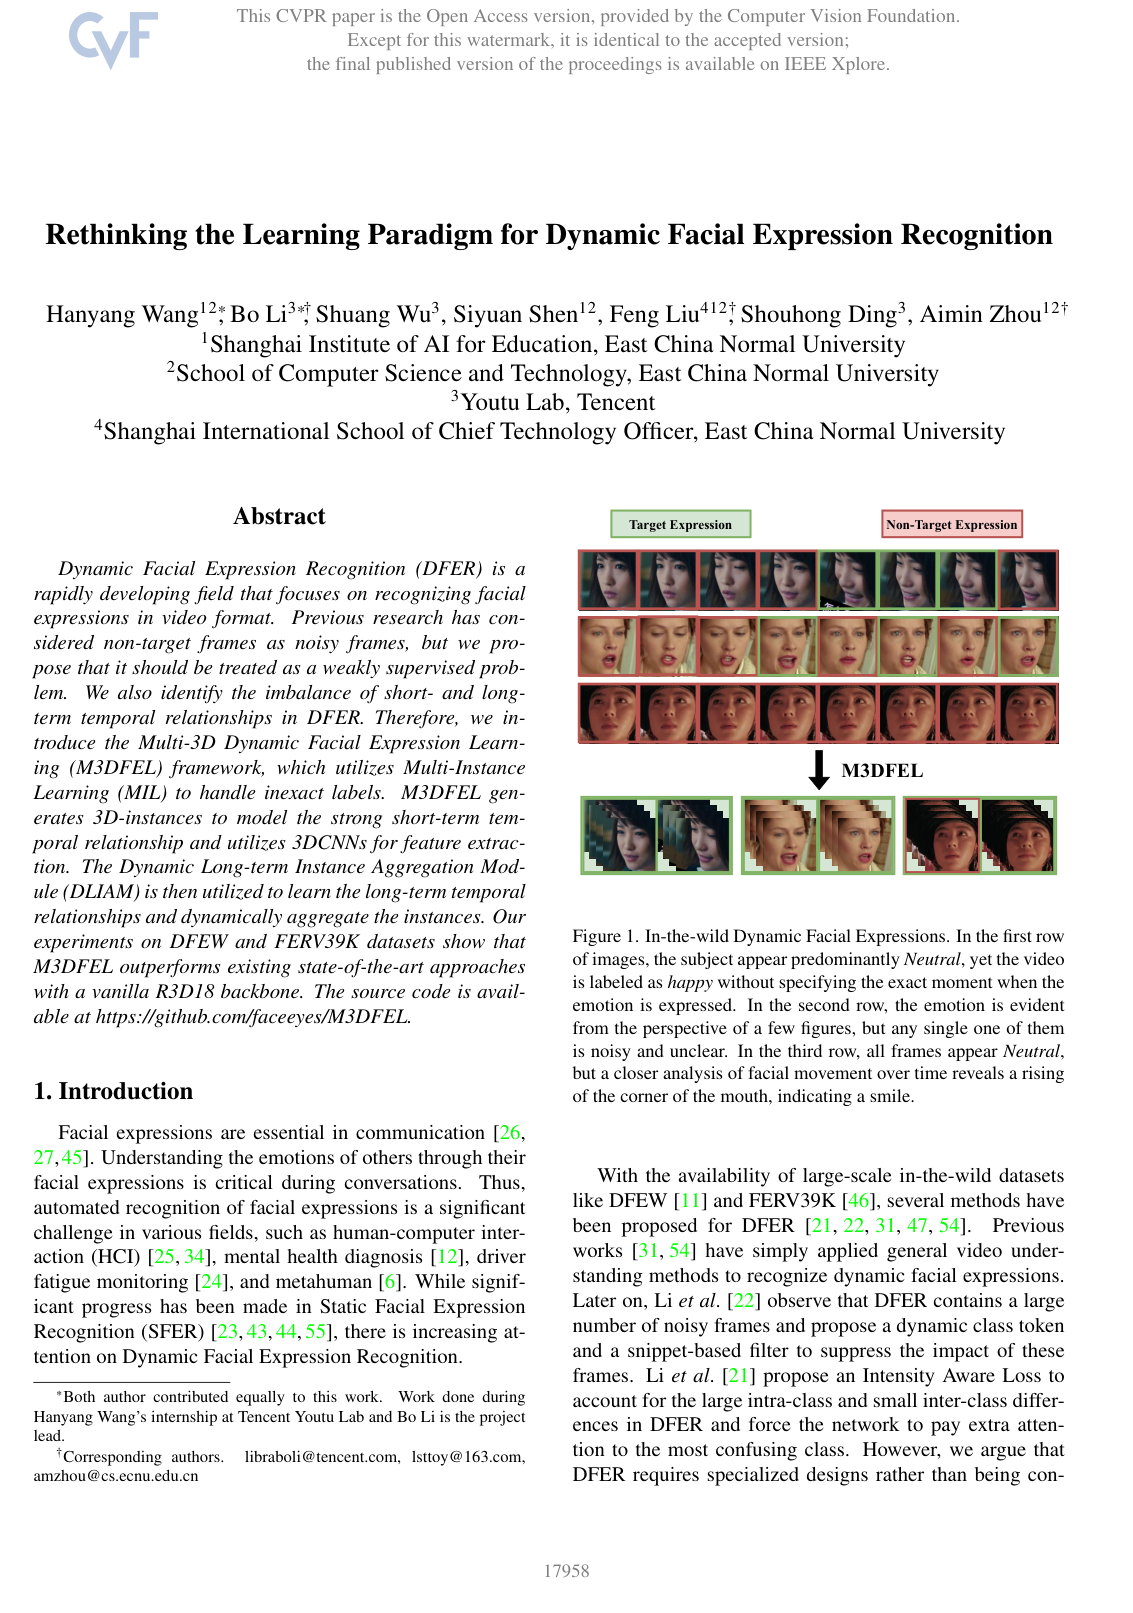
Dynamic Facial Expression Recognition (DFER) is a rapidly developing field that focuses on recognizing facial expressions in video format. Previous research has considered non-target frames as noisy frames, but we propose that it should be treated as a weakly supervised problem. We also identify the imbalance of short- and long-term temporal relationships in DFER. Therefore, we introduce the Multi-3D Dynamic Facial Expression Learning (M3DFEL) framework, which utilizes Multi-Instance Learning (MIL) to handle inexact labels. M3DFEL generates 3D-instances to model the strong short-term temporal relationship and utilizes 3DCNNs for feature extraction. The Dynamic Long-term Instance Aggregation Module (DLIAM) is then utilized to learn the long-term temporal relationships and dynamically aggregate the instances. Our experiments on DFEW and FERV39K datasets show that M3DFEL outperforms existing state-of-the-art approaches with a vanilla R3D18 backbone. The source code is available at https://github.com/faceeyes/M3DFEL.

Added

2026-09-26