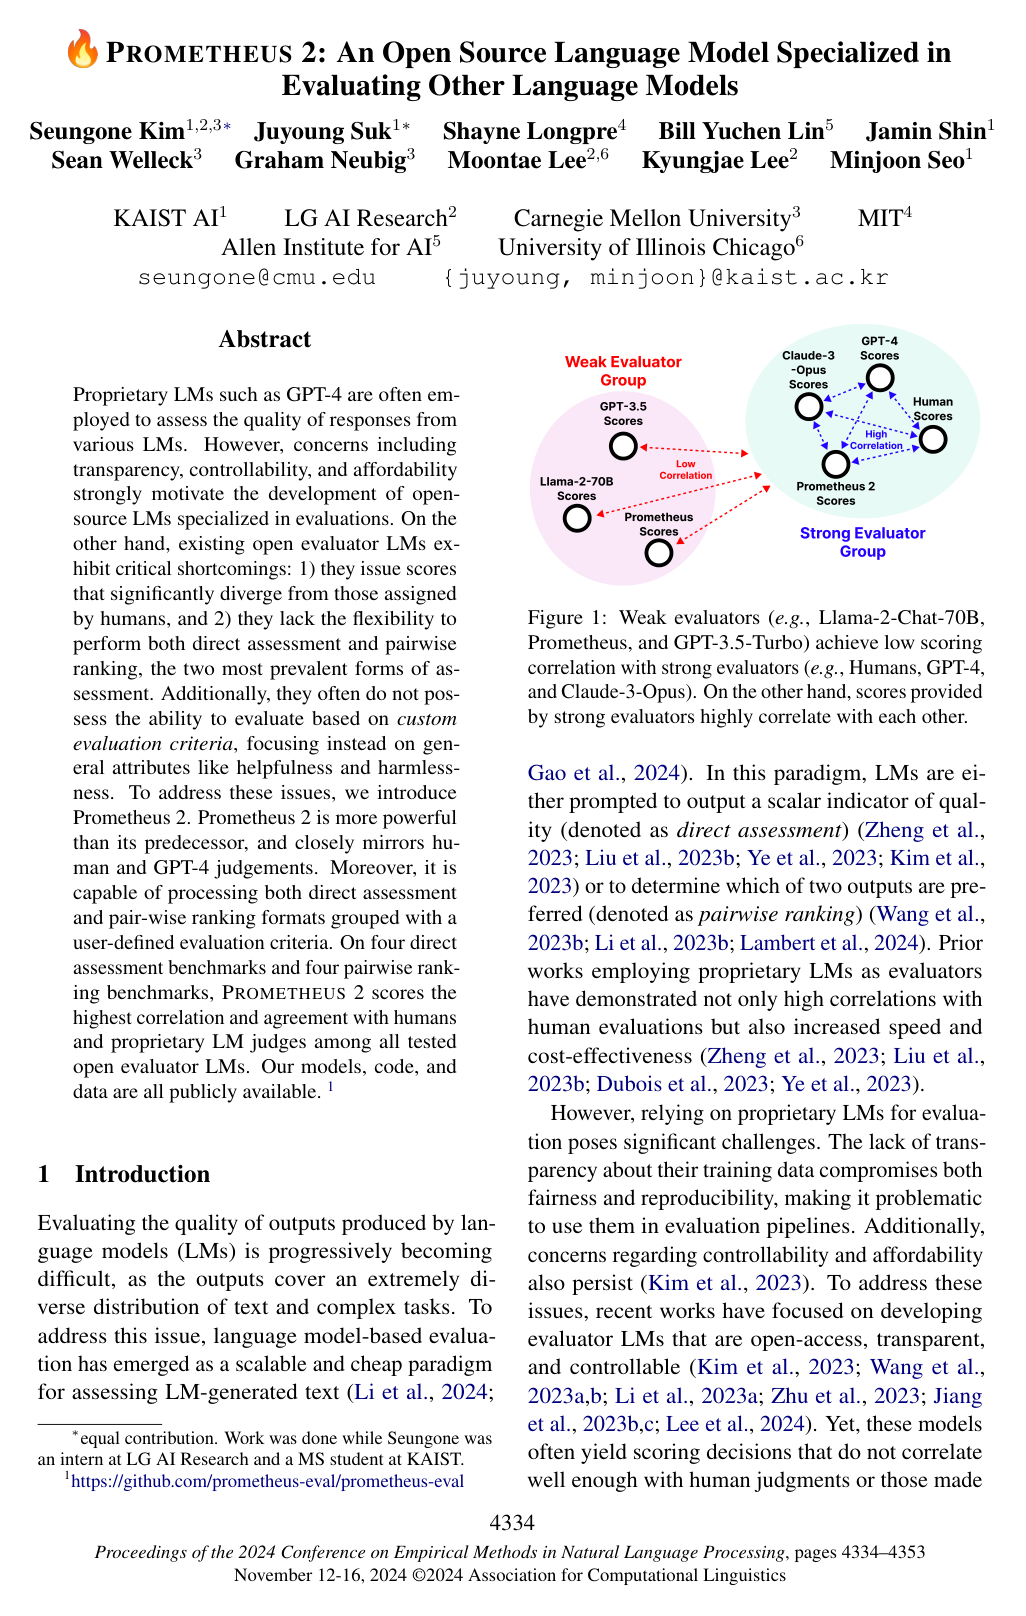
Evaluator language models are language models designed or fine-tuned specifically to assess, score, and rank the quality of text generated by other artificial intelligence systems. Operating as automated judges, these models evaluate candidate responses through methods such as direct scoring against specific rubrics or pairwise comparisons between competing outputs. They are applied across benchmarking, model alignment, and quality assurance workflows to measure attributes like accuracy, helpfulness, safety, or custom task criteria. By approximating human judgment, evaluator language models provide a scalable, consistent, and cost-effective alternative to manual human evaluation while generating structured feedback and quantitative metrics.