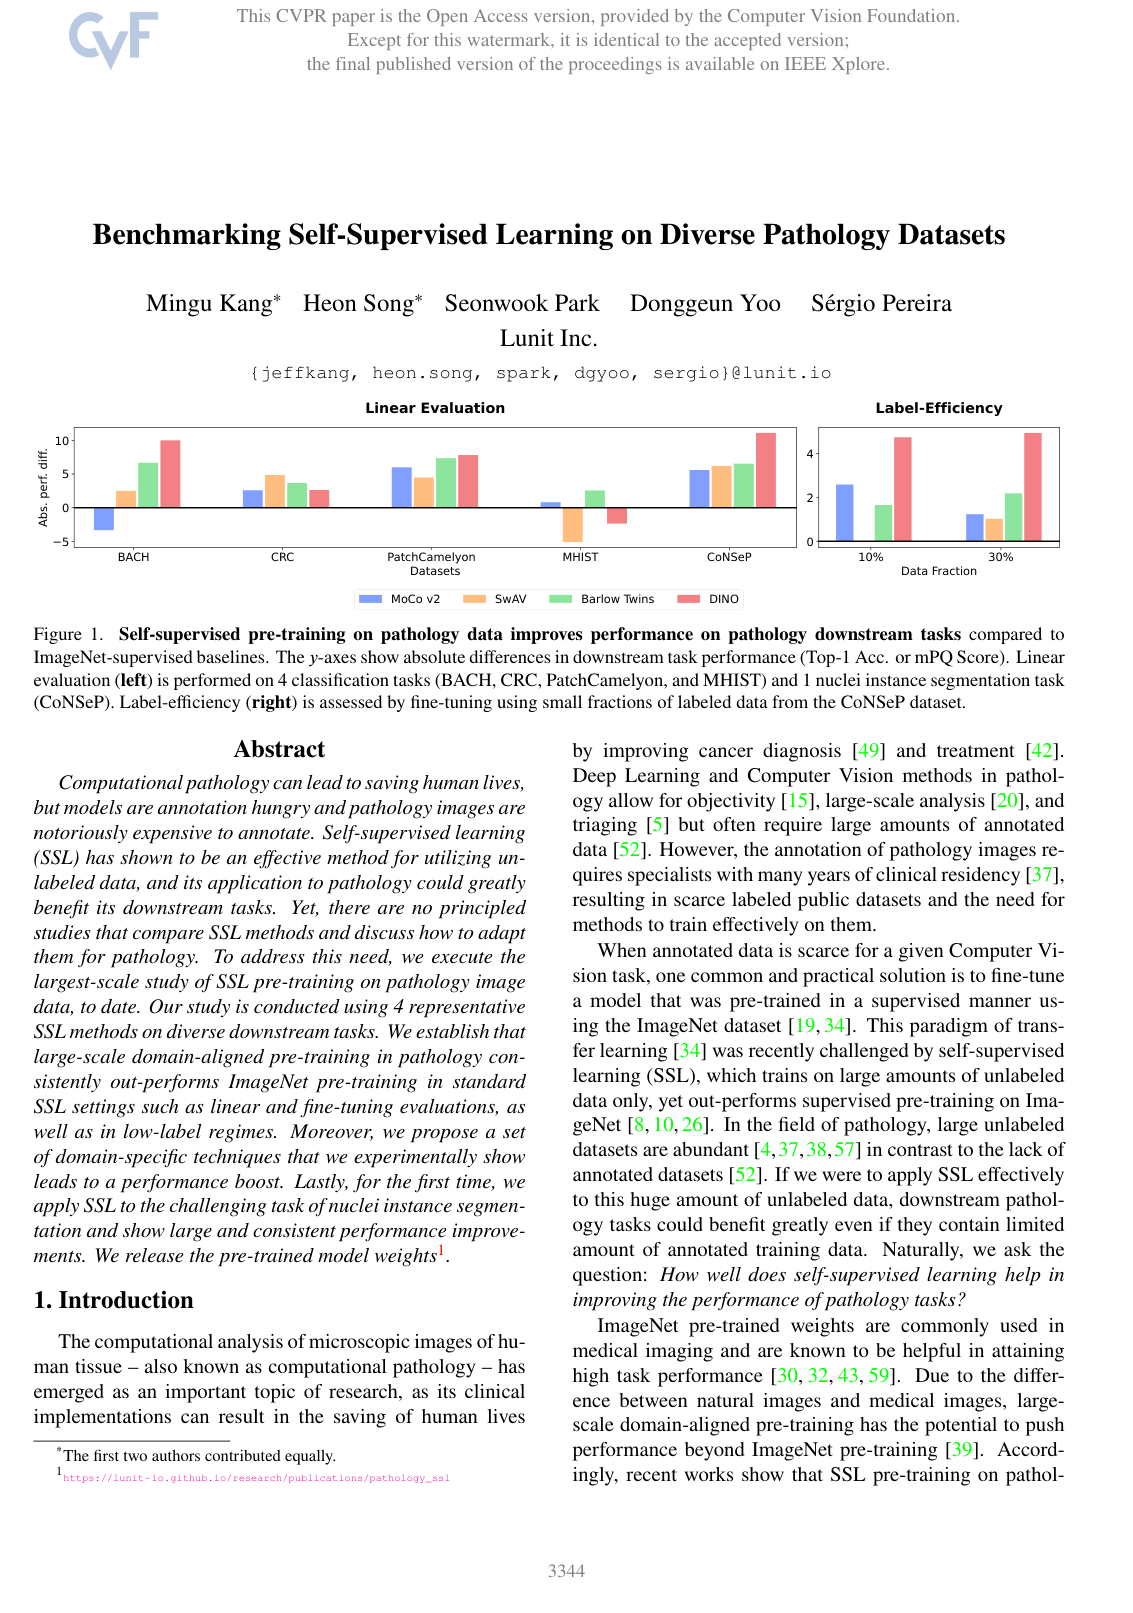
Domain-aligned pretraining is a machine learning approach in which a model is initially trained on data sourced specifically from the target application domain rather than from generic, out-of-domain datasets. By learning representations directly from data distributions that match the characteristics of the intended domain, such as specialized scientific text, satellite observations, or medical imagery, the model captures relevant structural, visual, and semantic features inherent to that field. This close alignment reduces the domain gap typically present when transferring general-purpose representations to specialized applications, leading to superior performance during downstream task evaluation, fine-tuning, and low-label regimes.