
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

cross-view decoders

Cross-view decoders are neural network modules in multi-view learning systems designed to project, translate, or reconstruct representations from one modality or viewpoint into another. Unlike standard or self-view decoders that reconstruct data within the same view, cross-view decoders take the latent features extracted from a source view and map them into the feature space or representation space of a different target view. This mechanism enables neural architectures to learn cross-view consistency and shared semantics while preserving view-specific characteristics across distinct embedding spaces. Furthermore, cross-view decoders provide a generative bridge that allows models to synthesize or recover missing modalities from available views, enhancing robustness in incomplete multi-view learning and clustering tasks.

1 item
Decoupled Contrastive Multi-View Clustering with High-Order Random Walks

Decoupled Contrastive Multi-View Clustering with High-Order Random Walks

Yiding Lu, Yijie Lin, Mouxing Yang, Dezhong Peng, Peng Hu, Xi Peng

OrganizationsSichuan University

Why you should read this

Proposes a decoupled multi-view clustering framework that uses high-order random walks to rectify false positive and false negative pairs globally while preserving view-specific information through cross-view reconstruction.

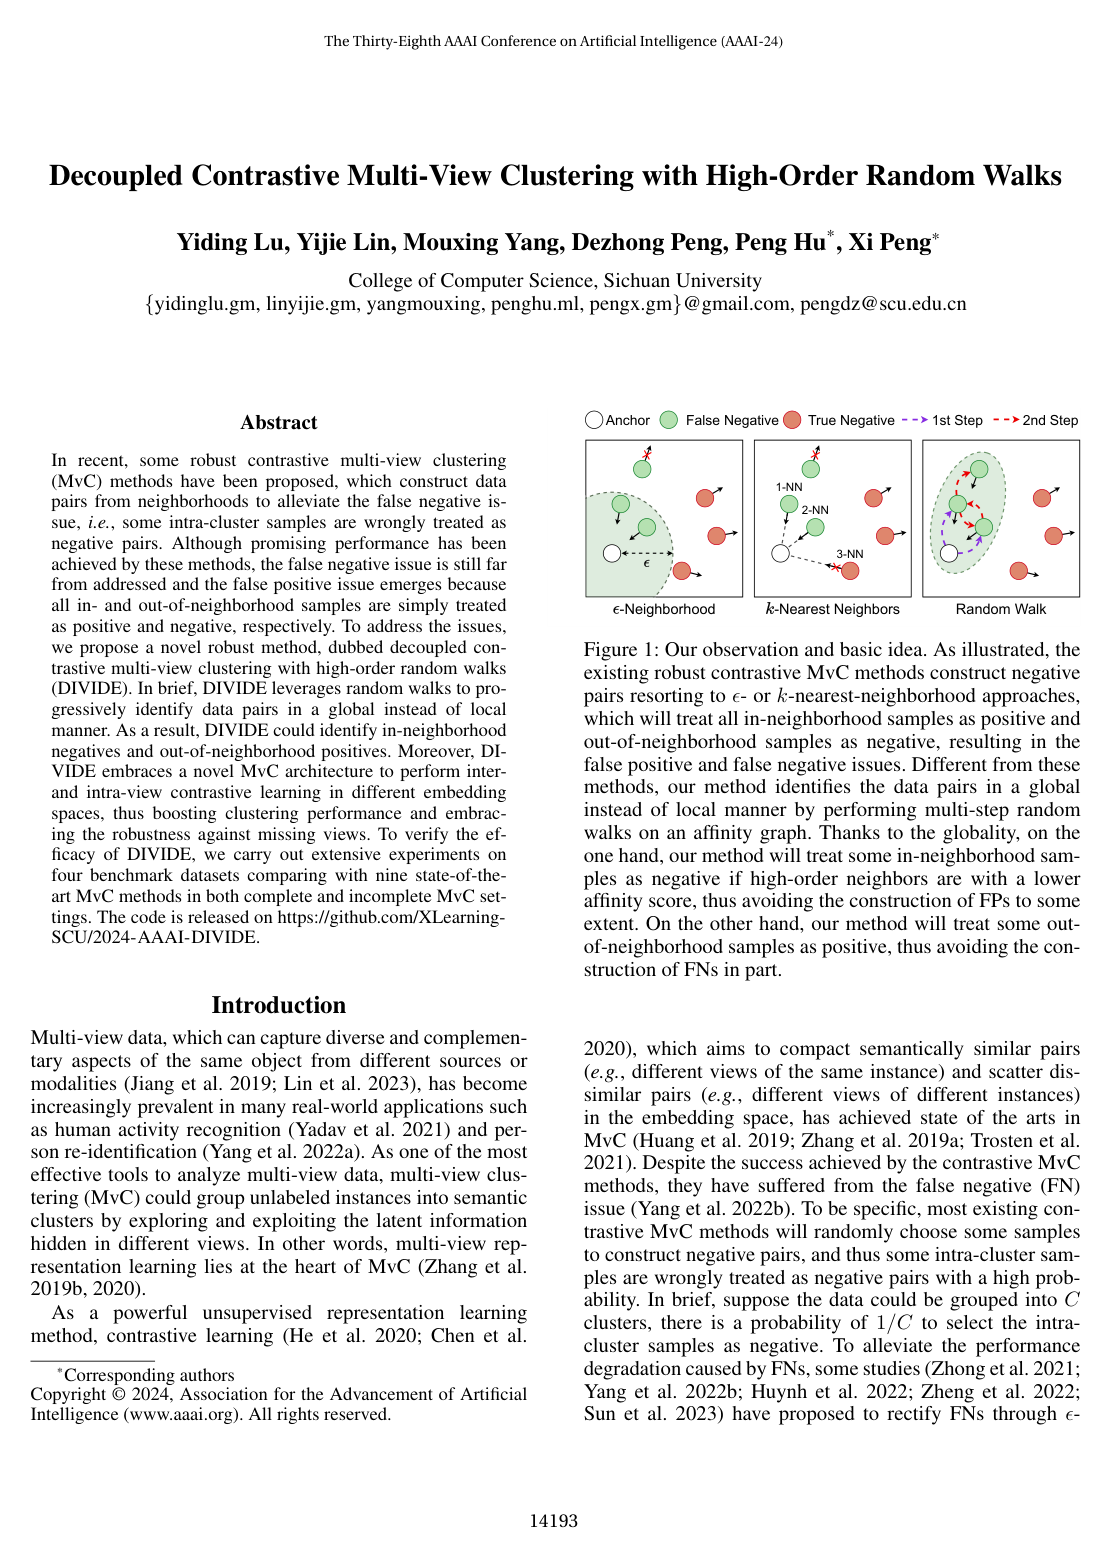
In recent, some robust contrastive multi-view clustering (MvC) methods have been proposed, which construct data pairs from neighborhoods to alleviate the false negative issue, i.e., some intra-cluster samples are wrongly treated as negative pairs. Although promising performance has been achieved by these methods, the false negative issue is still far from addressed and the false positive issue emerges because all in- and out-of-neighborhood samples are simply treated as positive and negative, respectively. To address the issues, we propose a novel robust method, dubbed decoupled contrastive multi-view clustering with high-order random walks (DIVIDE). In brief, DIVIDE leverages random walks to progressively identify data pairs in a global instead of local manner. As a result, DIVIDE could identify in-neighborhood negatives and out-of-neighborhood positives. Moreover, DIVIDE embraces a novel MvC architecture to perform inter- and intra-view contrastive learning in different embedding spaces, thus boosting clustering performance and embracing the robustness against missing views. To verify the efficacy of DIVIDE, we carry out extensive experiments on four benchmark datasets comparing with nine state-of-the-art MvC methods in both complete and incomplete MvC settings. The code is released on https://github.com/XLearning-SCU/2024-AAAI-DIVIDE.

Added

2026-09-26