Built independently by an author, for readers. Read the story and support ChapterPal

keyword

cross-domain attention layer

A cross-domain attention layer is a neural network module designed to facilitate information exchange, alignment, and feature fusion between distinct data modalities or representation domains. Operating within attention-based architectures, this layer computes attention weights that allow queries from one data domain to attend to keys and values from another, enabling features in one representation to dynamically reference and incorporate context from a complementary stream. In multi-modal and multi-view generative frameworks, such as models that jointly synthesize appearance and geometric data, cross-domain attention layers ensure structural, spatial, and semantic consistency across the different output domains.

1 item

Wonder3D: Single Image to 3D Using Cross-Domain Diffusion

Wonder3D: Single Image to 3D Using Cross-Domain Diffusion

Xiaoxiao Long, Yuan-Chen Guo, Cheng Lin, Yuan Liu, Zhiyang Dou, Lingjie Liu, Yuexin Ma, Song-Hai Zhang, Marc Habermann, Christian Theobalt, Wenping Wang

OrganizationsMax Planck Institute for InformaticsShanghaiTech UniversityTexas A&M UniversityTsinghua UniversityUniversity of Hong KongUniversity of PennsylvaniaVAST

Why you should read this

Proposes a cross-domain diffusion framework that jointly generates consistent multi-view normal maps and color images to extract detailed, high-fidelity 3D meshes from a single image in just two to three minutes.

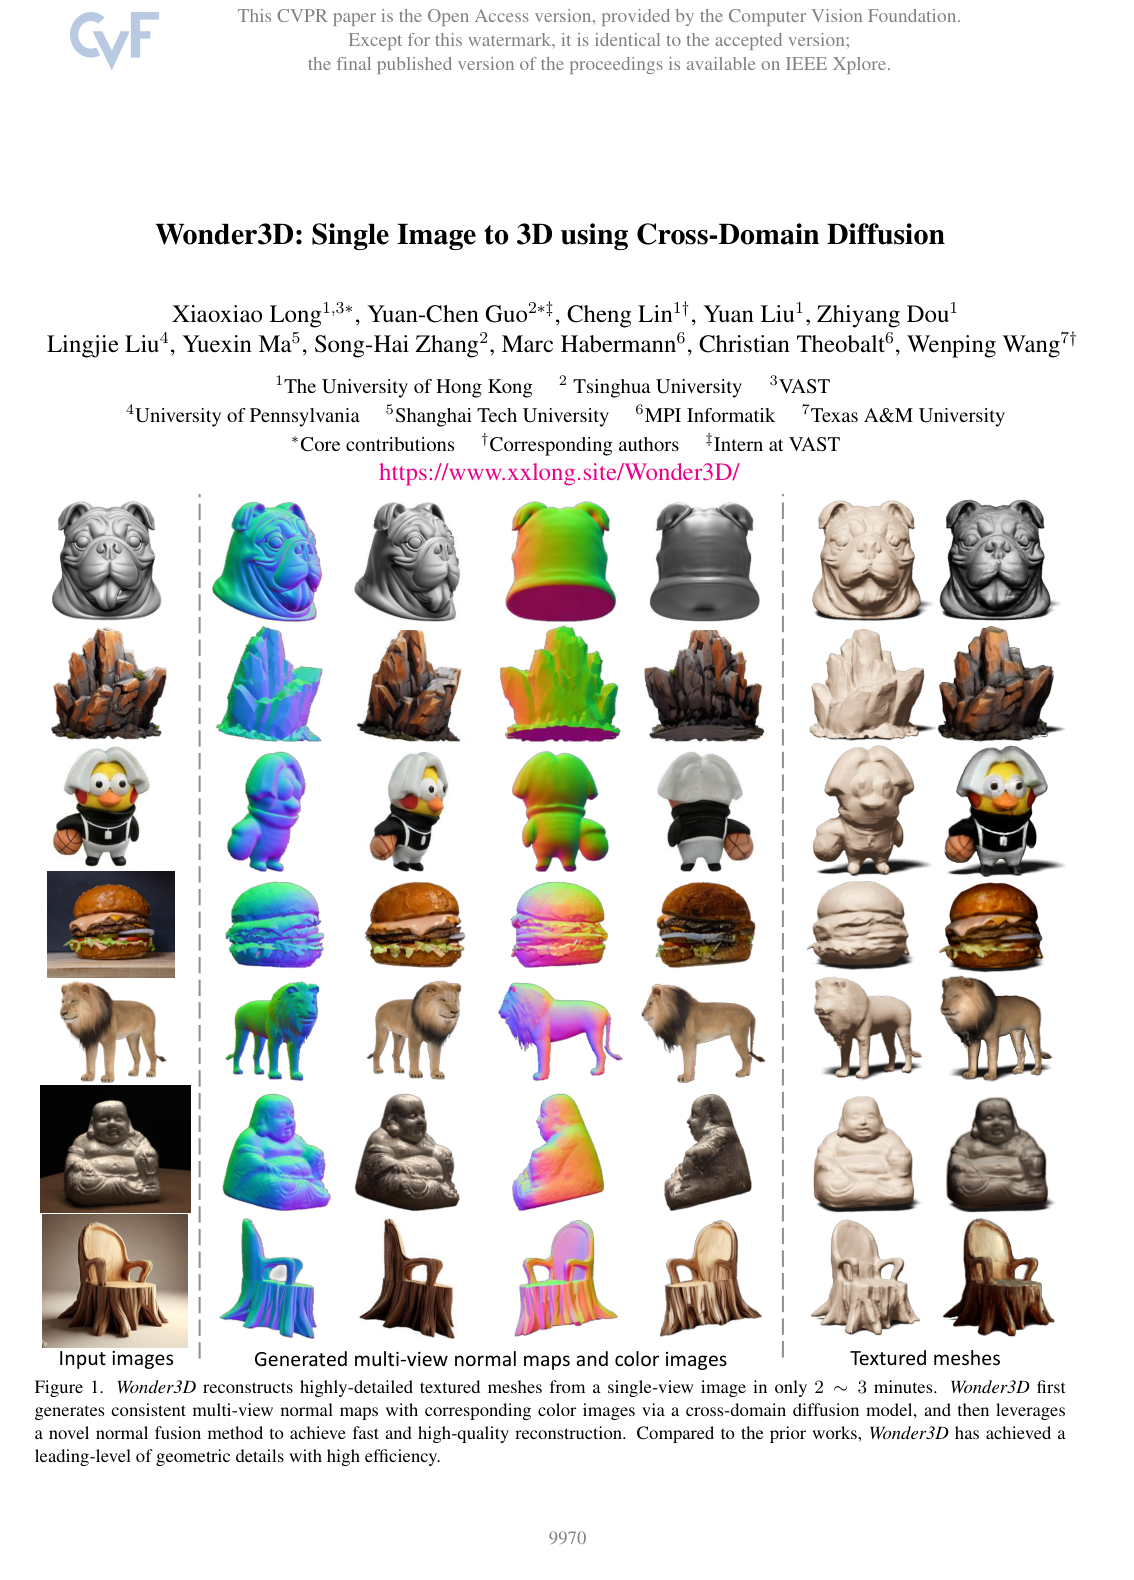
In this work, we introduce Wonder3D, a novel method for efficiently generating high-fidelity textured meshes from single-view images. Recent methods based on Score Distillation Sampling (SDS) have shown the potential to recover 3D geometry from 2D diffusion priors, but they typically suffer from time-consuming per-shape optimization and inconsistent geometry. In contrast, certain works directly produce 3D information via fast network inferences, but their results are often of low quality and lack geometric details. To holistically improve the quality, consistency, and efficiency of single-view reconstruction tasks, we propose a cross-domain diffusion model that generates multi-view normal maps and the corresponding color images. To ensure the consistency of generation, we employ a multi-view cross-domain attention mechanism that facilitates information exchange across views and modalities. Lastly, we introduce a geometry-aware normal fusion algorithm that extracts high-quality surfaces from the multi-view 2D representations in only 2 ∼ 3 minutes. Our extensive evaluations demonstrate that our method achieves high-quality reconstruction results, robust generalization, and good efficiency compared to prior works.

Added

2026-09-26