
keyword
community structure
Community structure is a topological property of complex networks in which nodes naturally divide into distinct groups or clusters characterized by dense internal connections and comparatively sparse connections between different groups. Within these systems, communities often represent functional subunits, social circles, or cohesive modules that operate with a degree of structural or behavioral independence. This organizational pattern commonly appears across social, biological, technological, and informational networks, manifesting as non-overlapping partitions, overlapping groups, or hierarchical multi-scale arrangements. Identifying and characterizing community structure provides fundamental insight into the macroscopic organization, functional units, and dynamic processes occurring within large-scale networks.
8 items
Community detection in networks: A user guide
Santo Fortunato, Darko Hric
Why you should read this
Clarifies the foundations of network community detection by evaluating the strengths and limitations of popular clustering algorithms, dispelling widespread methodological misconceptions, and providing practical criteria for performance validation.
Community detection in networks is one of the most popular topics of modern network science. Communities, or clusters, are usually groups of vertices having higher probability of being connected to each other than to members of other groups, though other patterns are possible. Identifying communities is an ill-defined problem. There are no universal protocols on the fundamental ingredients, like the definition of community itself, nor on other crucial issues, like the validation of algorithms and the comparison of their performances. This has generated a number of confusions and misconceptions, which undermine the progress in the field. We offer a guided tour through the main aspects of the problem. We also point out strengths and weaknesses of popular methods, and give directions to their use.
Added
2026-09-16
Group formation in large social networks: membership, growth, and evolution
Lars Backstrom, Dan Huttenlocher, Jon Kleinberg, Xiangyang Lan
Why you should read this
Demonstrates how underlying network structure dictates community growth and membership decisions in large-scale social networks, showing that an individual's probability of joining a group depends heavily on the internal connections among their existing member friends rather than simple friend counts alone.
The processes by which communities come together, attract new members, and develop over time is a central research issue in the social sciences — political movements, professional organizations, and religious denominations all provide fundamental examples of such communities. In the digital domain, on-line groups are becoming increasingly prominent due to the growth of community and social networking sites such as MySpace and LiveJournal. However, the challenge of collecting and analyzing large-scale time-resolved data on social groups and communities has left most basic questions about the evolution of such groups largely unresolved: what are the structural features that influence whether individuals will join communities, which communities will grow rapidly, and how do the overlaps among pairs of communities change over time? Here we address these questions using two large sources of data: friendship links and community membership on LiveJournal, and co-authorship and conference publications in DBLP. Both of these datasets provide explicit user-defined communities, where conferences serve as proxies for communities in DBLP. We study how the evolution of these communities relates to properties such as the structure of the underlying social networks. We find that the propensity of individuals to join communities, and of communities to grow rapidly, depends in subtle ways on the underlying network structure. For example, the tendency of an individual to join a community is influenced not just by the number of friends he or she has within the community, but also crucially by how those friends are connected to one another. We use decision-tree techniques to identify the most significant structural determinants of these properties. We also develop a novel methodology for measuring movement of individuals between communities, and show how such movements are closely aligned with changes in the topics of interest within the communities.
Added
2026-09-16
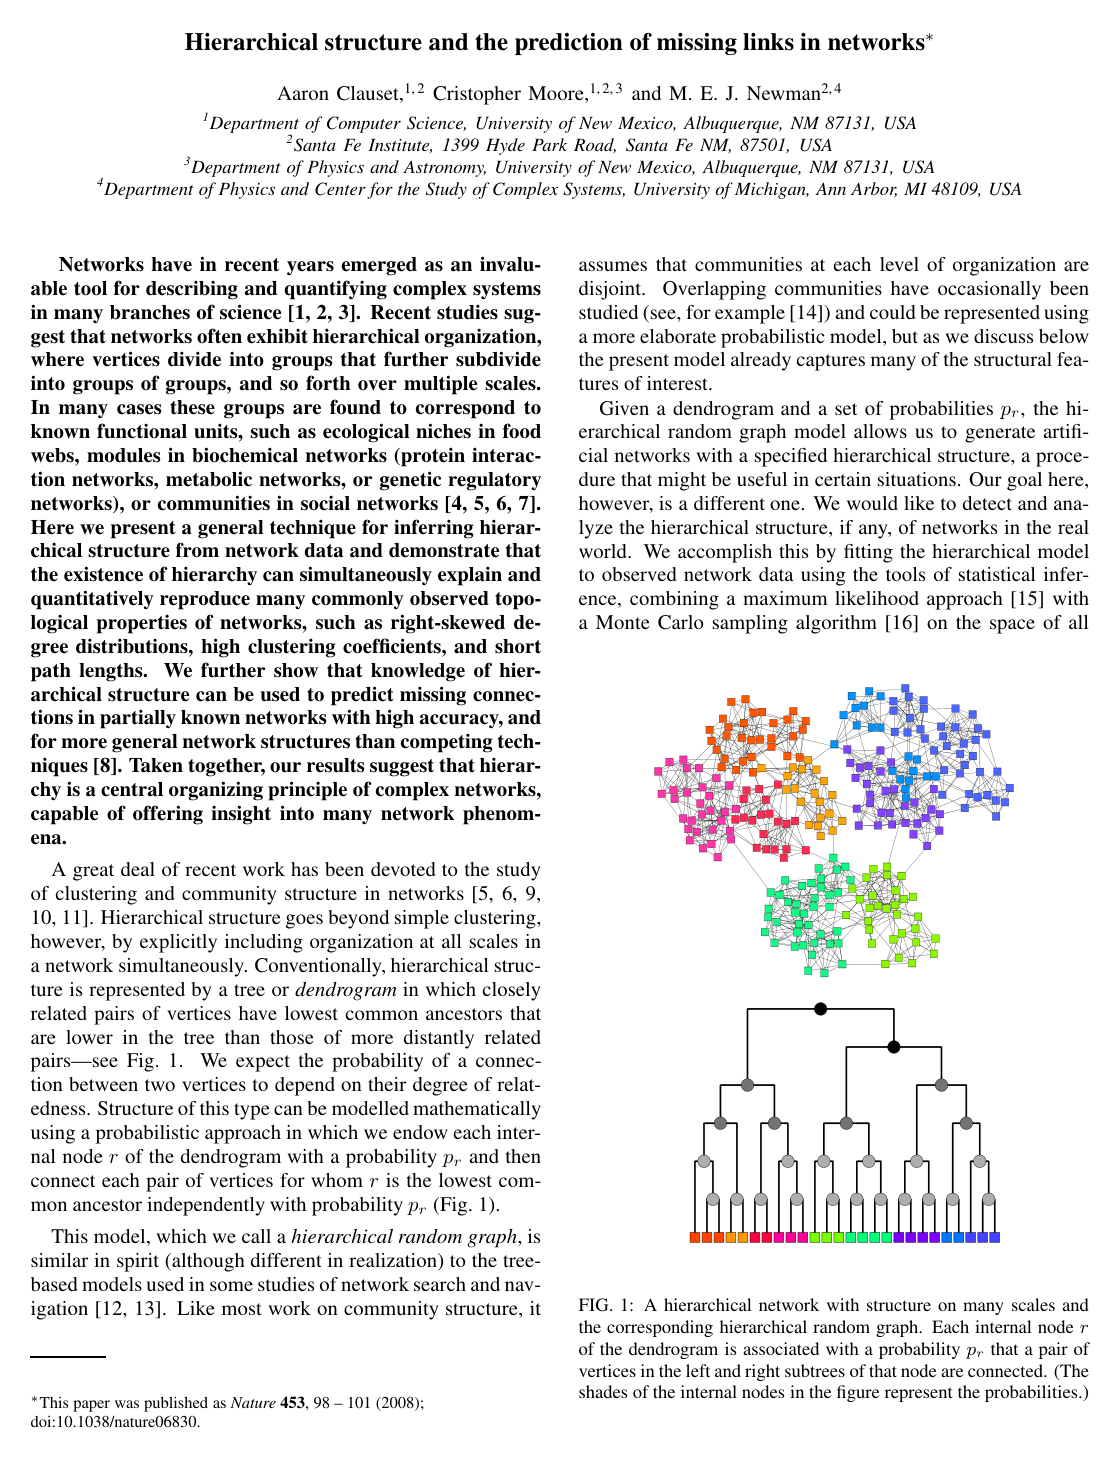
Hierarchical structure and the prediction of missing links in networks
Aaron Clauset, Cristopher Moore, M.E.J. Newman
Why you should read this
Introduces a statistical framework for inferring hierarchical organization from network data, demonstrating that multiscale hierarchy explains fundamental topological properties and enables highly accurate prediction of missing links.
Networks have in recent years emerged as an invaluable tool for describing and quantifying complex systems in many branches of science. Recent studies suggest that networks often exhibit hierarchical organization, where vertices divide into groups that further subdivide into groups of groups, and so forth over multiple scales. In many cases these groups are found to correspond to known functional units, such as ecological niches in food webs, modules in biochemical networks (protein interaction networks, metabolic networks, or genetic regulatory networks), or communities in social networks. Here we present a general technique for inferring hierarchical structure from network data and demonstrate that the existence of hierarchy can simultaneously explain and quantitatively reproduce many commonly observed topological properties of networks, such as right-skewed degree distributions, high clustering coefficients, and short path lengths. We further show that knowledge of hierarchical structure can be used to predict missing connections in partially known networks with high accuracy, and for more general network structures than competing techniques. Taken together, our results suggest that hierarchy is a central organizing principle of complex networks, capable of offering insight into many network phenomena.
Added
2026-09-16
Stochastic blockmodels and community structure in networks
Brian Karrer, M. E. J. Newman
Why you should read this
Introduces a degree-corrected stochastic blockmodel and optimization algorithm that prevents broad node-degree variations from distorting community detection in real-world networks.
Stochastic blockmodels have been proposed as a tool for detecting community structure in networks as well as for generating synthetic networks for use as benchmarks. Most blockmodels, however, ignore variation in vertex degree, making them unsuitable for applications to real-world networks, which typically display broad degree distributions that can significantly distort the results. Here we demonstrate how the generalization of blockmodels to incorporate this missing element leads to an improved objective function for community detection in complex networks. We also propose a heuristic algorithm for community detection using this objective function or its non-degree-corrected counterpart and show that the degree-corrected version dramatically outperforms the uncorrected one in both real-world and synthetic networks.
Added
2026-09-16
Learning to Discover Social Circles in Ego Networks
Julian McAuley, J. Leskovec
Why you should read this
Proposes an unsupervised generative model that automatically detects overlapping and hierarchically nested social circles within ego networks by jointly learning community memberships and circle-specific profile similarity metrics.
Our personal social networks are big and cluttered, and currently there is no good way to organize them. Social networking sites allow users to manually categorize their friends into social circles (e.g. ‘circles’ on Google+, and ‘lists’ on Facebook and Twitter), however they are laborious to construct and must be updated whenever a user’s network grows. We define a novel machine learning task of identifying users’ social circles. We pose the problem as a node clustering problem on a user’s ego-network, a network of connections between her friends. We develop a model for detecting circles that combines network structure as well as user profile information. For each circle we learn its members and the circle-specific user profile similarity metric. Modeling node membership to multiple circles allows us to detect overlapping as well as hierarchically nested circles. Experiments show that our model accurately identifies circles on a diverse set of data from Facebook, Google+, and Twitter for all of which we obtain hand-labeled ground-truth.
Added
2026-09-15
Defining and evaluating network communities based on ground-truth
Jaewon Yang, Jure Leskovec
Why you should read this
Evaluates thirteen structural definitions of network communities against ground-truth data from 230 real-world networks, identifying the most reliable topological metrics and introducing a parameter-free community detection algorithm that scales to hundreds of millions of nodes.
Nodes in real-world networks organize into densely linked communities where edges appear with high concentration among the members of the community. Identifying such communities of nodes has proven to be a challenging task mainly due to a plethora of definitions of a community, intractability of algorithms, issues with evaluation and the lack of a reliable gold-standard ground-truth. In this paper we study a set of 230 large real-world social, collaboration and information networks where nodes explicitly state their group memberships. For example, in social networks nodes explicitly join various interest based social groups. We use such groups to define a reliable and robust notion of ground-truth communities. We then propose a methodology which allows us to compare and quantitatively evaluate how different structural definitions of network communities correspond to ground-truth communities. We choose 13 commonly used structural definitions of network communities and examine their sensitivity, robustness and performance in identifying the ground-truth. We show that the 13 structural definitions are heavily correlated and naturally group into four classes. We find that two of these definitions, Conductance and Triad-participation-ratio, consistently give the best performance in identifying ground-truth communities. We also investigate a task of detecting communities given a single seed node. We extend the local spectral clustering algorithm into a heuristic parameter-free community detection method that easily scales to networks with more than hundred million nodes. The proposed method achieves 30% relative improvement over current local clustering methods.
Added
2026-09-15
From Louvain to Leiden: guaranteeing well-connected communities
Vincent Traag, Ludo Waltman, Nees Jan van Eck
Why you should read this
Introduces the Leiden algorithm for network community detection to resolve a critical flaw in the popular Louvain method, providing mathematical guarantees of well-connected communities alongside faster runtimes and higher-quality partitions.
Community detection is often used to understand the structure of large and complex networks. One of the most popular algorithms for uncovering community structure is the so-called Louvain algorithm. We show that this algorithm has a major defect that largely went unnoticed until now: the Louvain algorithm may yield arbitrarily badly connected communities. In the worst case, communities may even be disconnected, especially when running the algorithm iteratively. In our experimental analysis, we observe that up to 25% of the communities are badly connected and up to 16% are disconnected. To address this problem, we introduce the Leiden algorithm. We prove that the Leiden algorithm yields communities that are guaranteed to be connected. In addition, we prove that, when the Leiden algorithm is applied iteratively, it converges to a partition in which all subsets of all communities are locally optimally assigned. Furthermore, by relying on a fast local move approach, the Leiden algorithm runs faster than the Louvain algorithm. We demonstrate the performance of the Leiden algorithm for several benchmark and real-world networks. We find that the Leiden algorithm is faster than the Louvain algorithm and uncovers better partitions, in addition to providing explicit guarantees.
Added
2026-09-10
Community detection in graphs
Santo Fortunato
Why you should read this
Surveys fundamental algorithms, statistical physics approaches, and evaluation benchmarks for community detection, providing a definitive guide to identifying cluster structures across complex biological, social, and technological networks.
The modern science of networks has brought significant advances to our understanding of complex systems. One of the most relevant features of graphs representing real systems is community structure, or clustering, i. e. the organization of vertices in clusters, with many edges joining vertices of the same cluster and comparatively few edges joining vertices of different clusters. Such clusters, or communities, can be considered as fairly independent compartments of a graph, playing a similar role like, e. g., the tissues or the organs in the human body. Detecting communities is of great importance in sociology, biology and computer science, disciplines where systems are often represented as graphs. This problem is very hard and not yet satisfactorily solved, despite the huge effort of a large interdisciplinary community of scientists working on it over the past few years. We will attempt a thorough exposition of the topic, from the definition of the main elements of the problem, to the presentation of most methods developed, with a special focus on techniques designed by statistical physicists, from the discussion of crucial issues like the significance of clustering and how methods should be tested and compared against each other, to the description of applications to real networks.
Added
2026-09-06