
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

caption-image pairs

Caption-image pairs are multimodal data samples that couple a visual image with a corresponding natural language text describing its content. In machine learning and computer vision, these pairs serve as foundational training data for vision-language models, enabling algorithms to learn cross-modal associations between visual features and linguistic semantics. They are widely utilized in tasks such as image captioning, cross-modal retrieval, text-to-image generation, and open-vocabulary visual recognition, allowing models to acquire broad semantic knowledge from weakly supervised textual descriptions without relying exclusively on dense, manual pixel-level or bounding-box annotations.

1 item
Open-Vocabulary Instance Segmentation via Robust Cross-Modal Pseudo-Labeling

Open-Vocabulary Instance Segmentation via Robust Cross-Modal Pseudo-Labeling

Dat Huynh, Jason Kuen, Zhe Lin, Jiuxiang Gu, Ehsan Elhamifar

OrganizationsAdobeNortheastern University

Why you should read this

Proposes a cross-modal pseudo-labeling framework that aligns caption words with visual mask features and filters label noise to segment novel object classes without mask annotations.

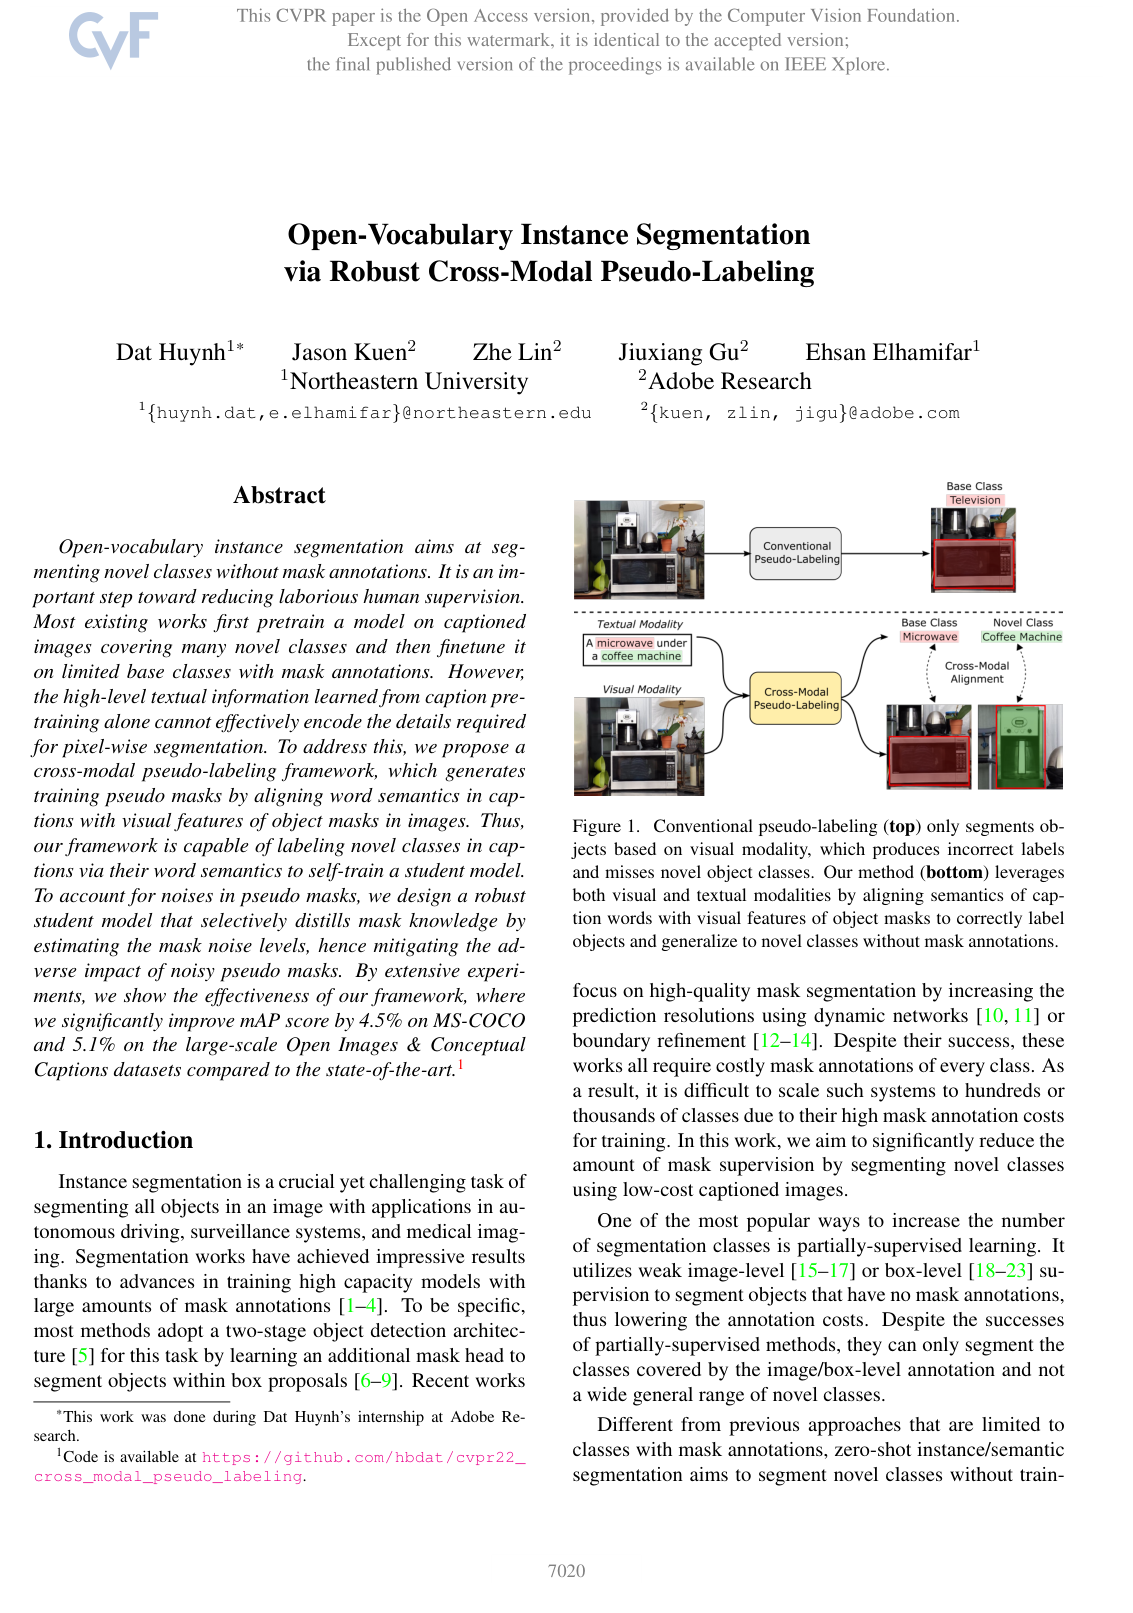
Open-vocabulary instance segmentation aims at segmenting novel classes without mask annotations. It is an important step toward reducing laborious human supervision. Most existing works first pretrain a model on captioned images covering many novel classes and then finetune it on limited base classes with mask annotations. However, the high-level textual information learned from caption pre-training alone cannot effectively encode the details required for pixel-wise segmentation. To address this, we propose a cross-modal pseudo-labeling framework, which generates training pseudo masks by aligning word semantics in captions with visual features of object masks in images. Thus, our framework is capable of labeling novel classes in captions via their word semantics to self-train a student model. To account for noises in pseudo masks, we design a robust student model that selectively distills mask knowledge by estimating the mask noise levels, hence mitigating the adverse impact of noisy pseudo masks. By extensive experiments, we show the effectiveness of our framework, where we significantly improve mAP score by 4.5% on MS-COCO and 5.1% on the large-scale Open Images & Conceptual Captions datasets compared to the state-of-the-art.

Added

2026-09-26