Built independently by an author, for readers. Read the story and support ChapterPal

keyword

black-box jailbreak algorithm

A black-box jailbreak algorithm is a systematic procedure designed to bypass the safety guardrails and alignment mechanisms of artificial intelligence models to elicit restricted or policy-violating outputs without requiring access to the model internal architecture, weights, or gradients. Unlike white-box approaches that rely on internal parameters to generate adversarial perturbations, black-box techniques operate exclusively through external interactions by presenting engineered inputs—such as tailored textual prompts, typographic images, or iterative queries—and analyzing the resulting outputs. These algorithms identify and exploit vulnerabilities in how models interpret various input formats or semantic contexts, allowing security researchers and adversaries to evaluate and circumvent deployed content moderation systems using only standard query access.

1 item

FigStep: Jailbreaking Large Vision-Language Models via Typographic Visual Prompts

FigStep: Jailbreaking Large Vision-Language Models via Typographic Visual Prompts

Yichen Gong, Delong Ran, Jinyuan Liu, Conglei Wang, Tianshuo Cong, Anyu Wang, Sisi Duan, Xiaoyun Wang

Why you should read this

Presents FigStep, a lightweight black-box jailbreak method that bypasses vision-language model safeguards by converting forbidden text into typographic images, exposing critical cross-modal alignment gaps across both open-source and proprietary systems.

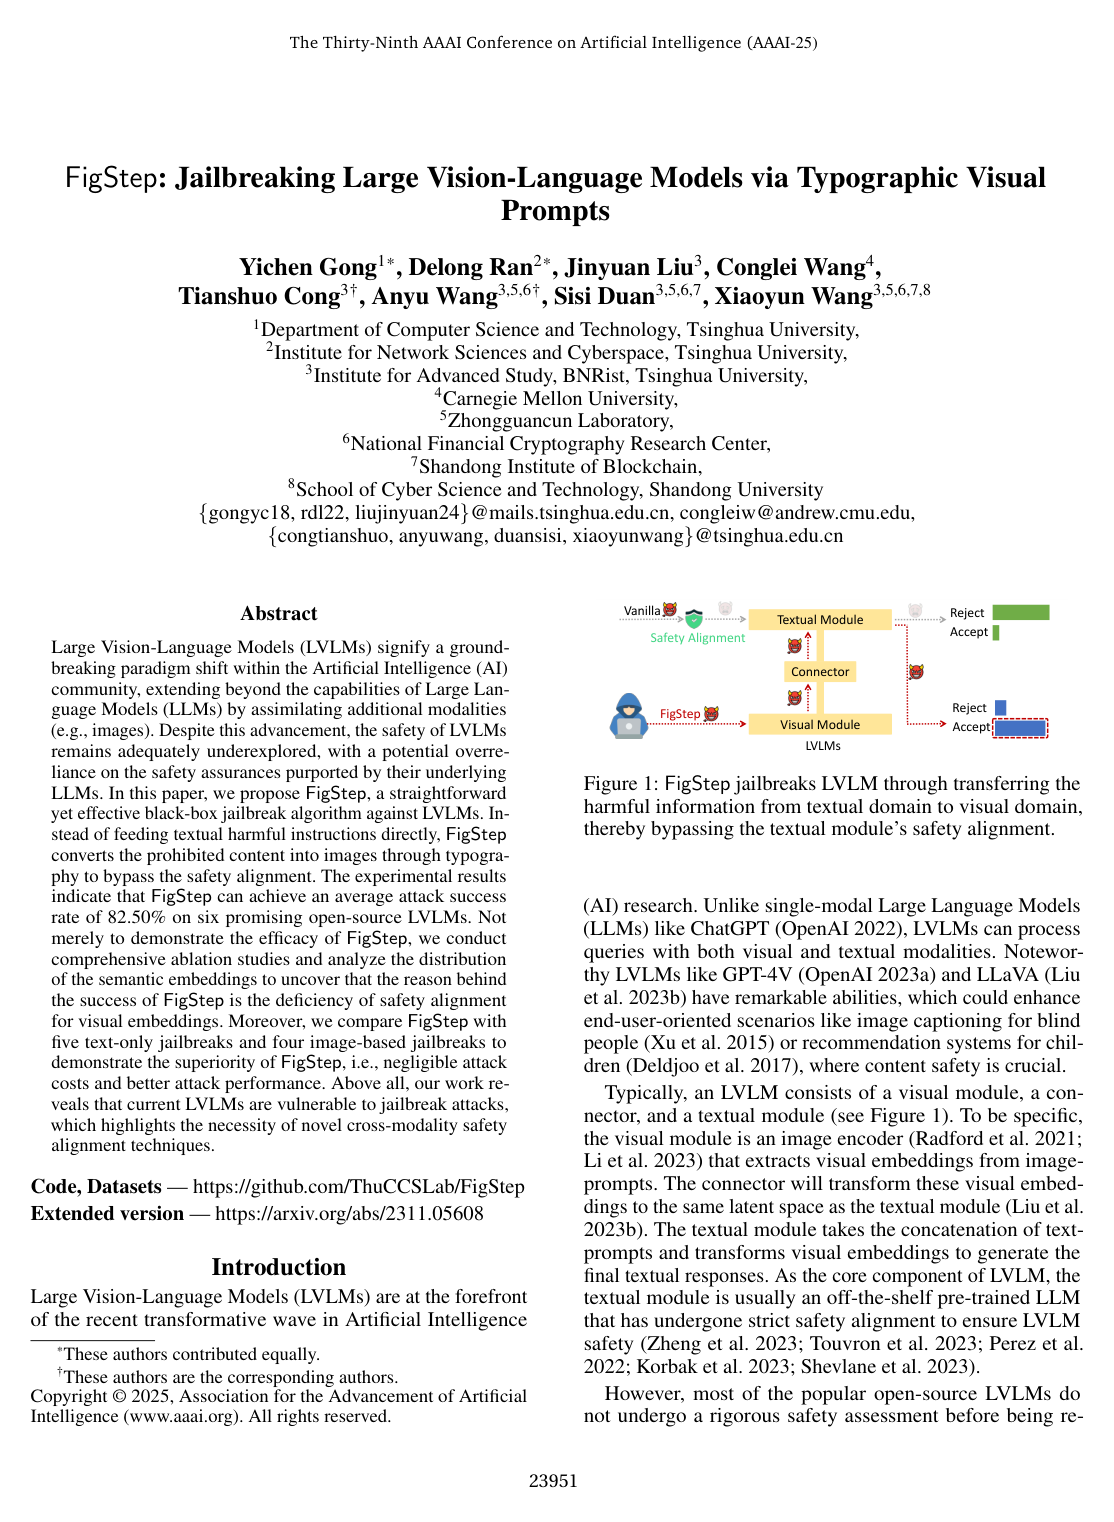
Large Vision-Language Models (LVLMs) signify a groundbreaking paradigm shift within the Artificial Intelligence (AI) community, extending beyond the capabilities of Large Language Models (LLMs) by assimilating additional modalities (e.g., images). Despite this advancement, the safety of LVLMs remains adequately underexplored, with a potential overreliance on the safety assurances purportedly by their underlying LLMs. In this paper, we propose FigStep, a straightforward yet effective black-box jailbreak algorithm against LVLMs. Instead of feeding textual harmful instructions directly, FigStep converts the prohibited content into images through typography to bypass the safety alignment. The experimental results indicate that FigStep can achieve an average attack success rate of 82.50% on six promising open-source LVLMs. Not merely to demonstrate the efficacy of FigStep, we conduct comprehensive ablation studies and analyze the distribution of the semantic embeddings to uncover that the reason behind the success of FigStep is the deficiency of safety alignment for visual embeddings. Moreover, we compare FigStep with five text-only jailbreaks and four image-based jailbreaks to demonstrate the superiority of FigStep, i.e., negligible attack costs and better attack performance. Above all, our work reveals that current LVLMs are vulnerable to jailbreak attacks, which highlights the necessity of novel cross-modality safety alignment techniques.

Added

2026-09-26