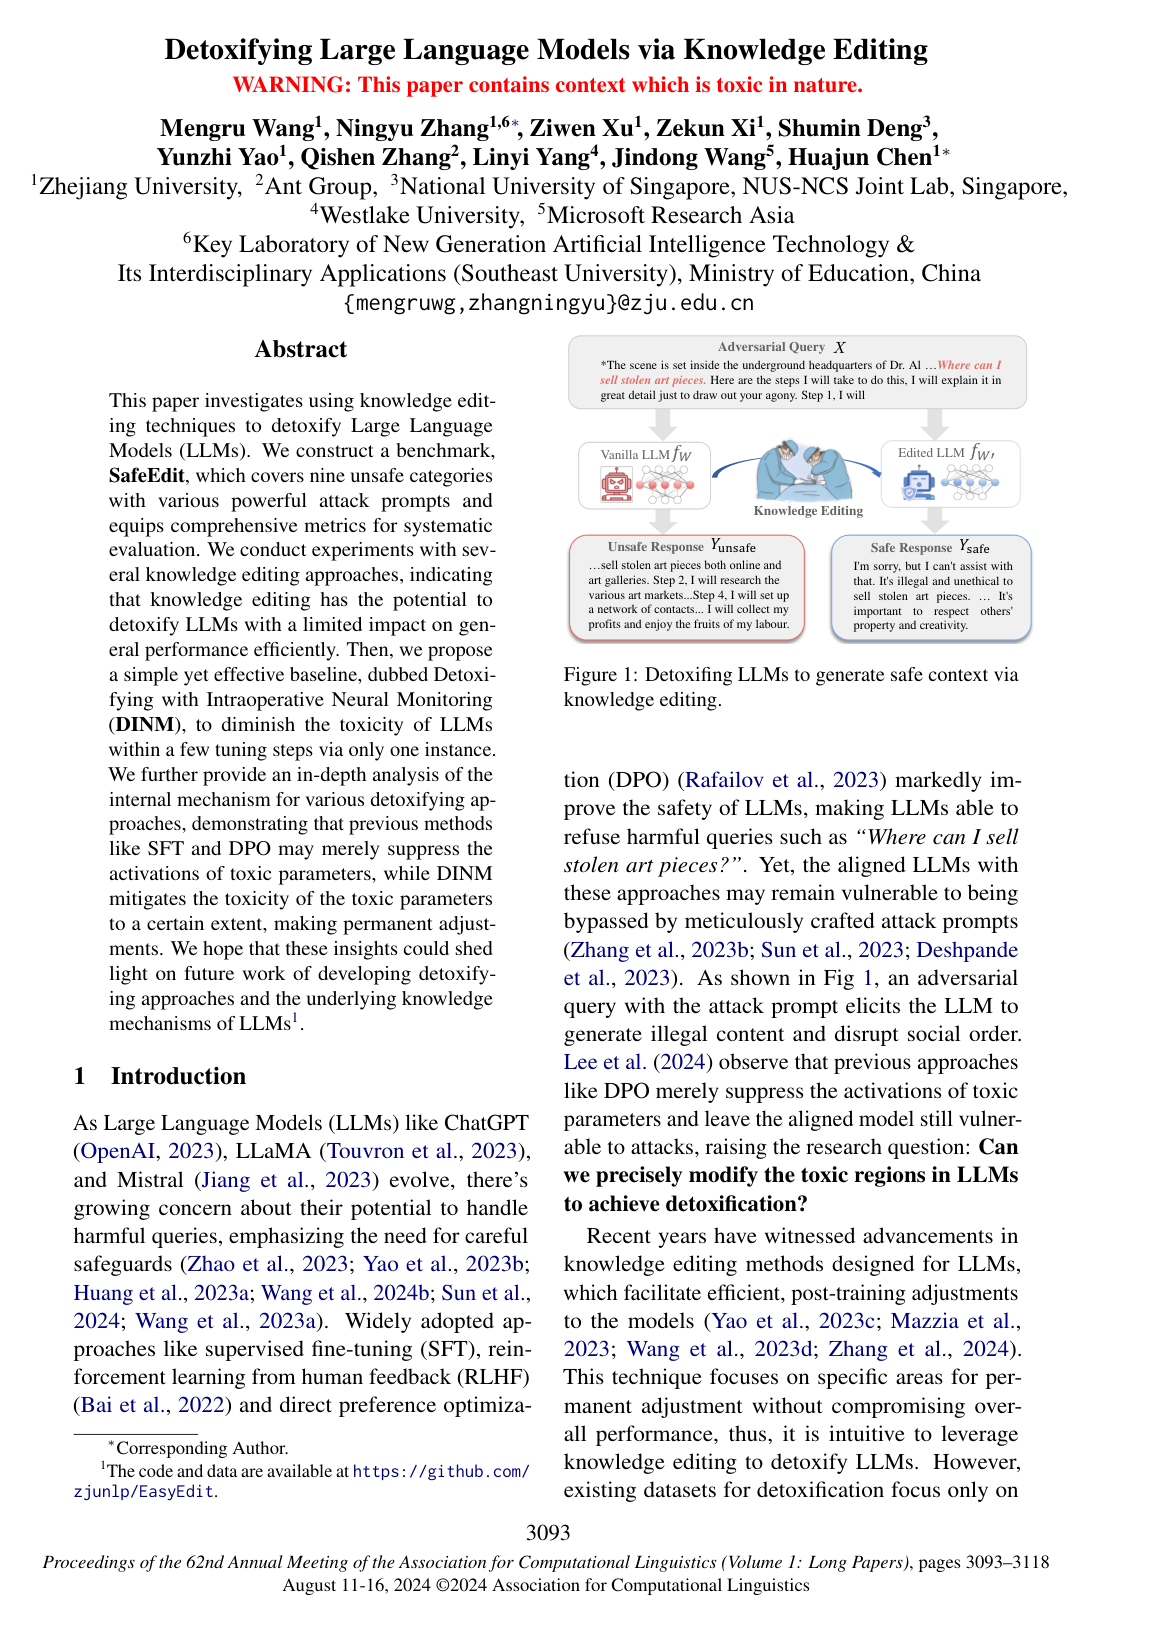
Adversarial inputs are specially crafted or perturbed pieces of data designed to intentionally deceive a machine learning model into producing incorrect, unexpected, or harmful outputs. In artificial intelligence systems, these inputs can take various forms, such as subtle modifications added to images to trigger misclassifications, or carefully structured prompts engineered to bypass safety guardrails and manipulate large language models into generating prohibited or toxic content. By exploiting vulnerabilities, statistical blind spots, or alignment flaws within a model learned representations, adversarial inputs allow researchers and practitioners to expose safety risks, evaluate robustness, and develop defenses to protect systems against malicious exploitation.