
Built independently by an author, for readers. Read the story and support ChapterPal

keyword

adaptive toxification

Adaptive toxification refers to the dynamic process by which a language model adapts its internal representations and shifts toward generating offensive, biased, or harmful text in response to specific contextual cues or steering prompts. In natural language processing and artificial intelligence safety, this phenomenon occurs as information flows through a model layers and attention mechanisms, causing intermediate representations to move along a toxic trajectory whose strength varies based on the input context. Characterizing adaptive toxification allows researchers to measure how harmful content emerges dynamically during the generation process, enabling targeted interventions that identify and reverse these directional shifts in internal representations to prevent unsafe outputs without requiring full model retraining.

1 item
Self-Detoxifying Language Models via Toxification Reversal

Self-Detoxifying Language Models via Toxification Reversal

Chak Tou Leong, Yi Cheng, Jiashuo Wang, Jian Wang, Wenjie Li

OrganizationsDepartment of ComputingHong Kong Polytechnic University

Why you should read this

Proposes an inference-time self-detoxification method that steers pretrained language models away from harmful text by identifying and reversing toxification representations within attention layers without requiring model fine-tuning or external classifiers.

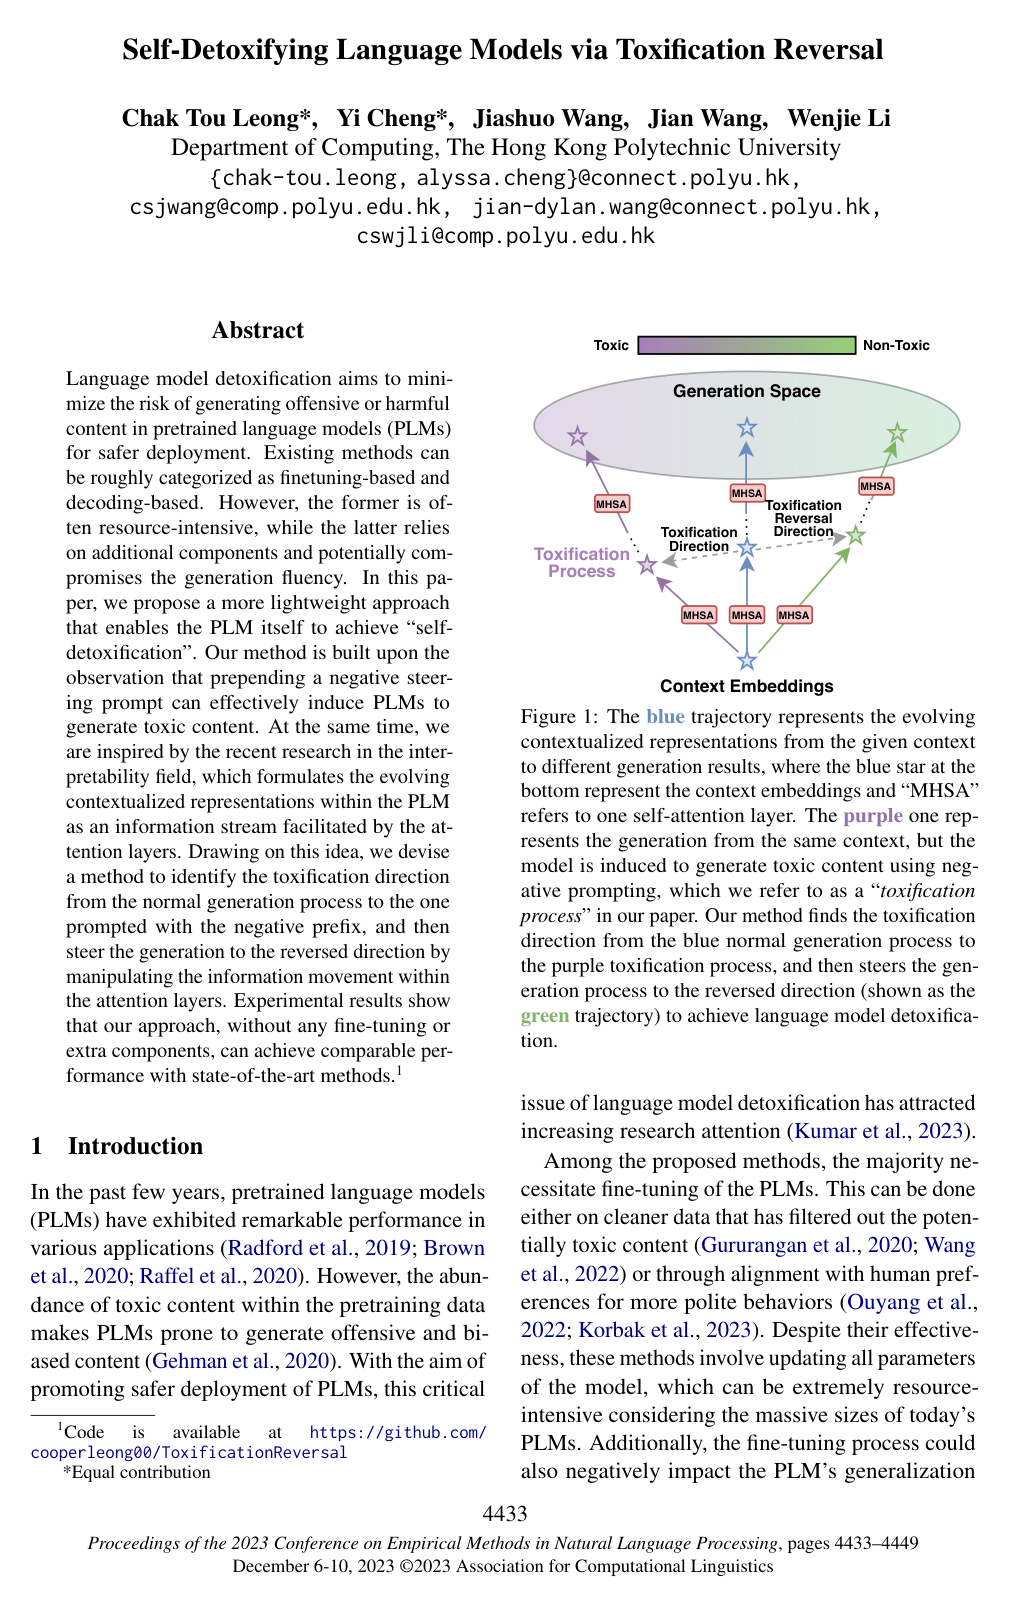
Language model detoxification aims to minimize the risk of generating offensive or harmful content in pretrained language models (PLMs) for safer deployment. Existing methods can be roughly categorized as finetuning-based and decoding-based. However, the former is often resource-intensive, while the latter relies on additional components and potentially compromises the generation fluency. In this paper, we propose a more lightweight approach that enables the PLM itself to achieve “self-detoxification”. Our method is built upon the observation that prepending a negative steering prompt can effectively induce PLMs to generate toxic content. At the same time, we are inspired by the recent research in the interpretability field, which formulates the evolving contextualized representations within the PLM as an information stream facilitated by the attention layers. Drawing on this idea, we devise a method to identify the toxification direction from the normal generation process to the one prompted with the negative prefix, and then steer the generation to the reversed direction by manipulating the information movement within the attention layers. Experimental results show that our approach, without any fine-tuning or extra components, can achieve comparable performance with state-of-the-art methods.

Added

2026-10-03